
🌠Beneficiary IDGen
Overview
Beneficiary IDGen is the shared ID factory and vending machine for a health campaign. Beneficiaries (and other entities) need unique, human-readable IDs — often pre-printed on cards, wristbands, or QR stickers handed out in the field. It's primarily used for beneficiaries who don't have a national ID (or equivalent government-issued identifier) to provide, giving them a system-generated identity they can be tracked and served under instead.
It has two main jobs:
Generate a tenant-specific pool of unique, human-readable beneficiary IDs from a configured format.
Dispatch a safe, non-overlapping batch of those IDs to a specific user and device in the field.
At a glance
Used by: setup or admin flows for generation, and DISTRIBUTOR users for field dispatch.
Input: tenant, ID format configuration, requested counts, dispatch context, and update criteria.
Output: generated pool records, dispatched ID allocations, search results, and audit logs.
Source of truth: Postgres
id_poolstores the ID pool state. Redis only enforces dispatch quotas.Generate: pre-mints IDs into the pool.
Dispatch: allocates IDs to one user and one device without overlap.
The Health Campaign Management app itself is offline-first — field staff often work in areas with low or no internet connectivity, so the app can't assume it can call IDGen live every time a new beneficiary or entity needs an ID.
To work around this, IDGen supports a pre-fetch/download model: when the field worker has connectivity (typically right after login, or whenever a sync window is available), the app downloads a batch of pre-generated IDs in advance and caches them locally. As new beneficiaries are registered in the field — even fully offline — the app assigns IDs from this local pool instead of waiting on a live call to IDGen.
The number of IDs downloaded per batch is configurable via MDMS, so this can be tuned per campaign (e.g. based on expected daily registration volume, device storage constraints, or field team size) without needing a code change.
In short: IDGen isn't just a request/response ID generator — it's designed as a vending machine that dispenses IDs in bulk upfront, so the offline app always has a local supply to draw from until the next sync, at which point it can top up.
It prepares IDs before campaign runtime, then hands them out in controlled batches during execution.
Dependencies
egov-mdms-service — supplies the ID format template for each tenant. Format tokens such as
[seq...],[fy:...],[cy:...],[city],[tenantid], and random[d{n}]patterns are expanded into final IDs. A DB fallback exists ifidformat.from.mdms=false.PostgreSQL — stores the ID pool and dispatch audit trail. Main tables are
id_poolandid_transaction_log. Postgres sequences back the[seq]portion of configured formats.Redis (via Redisson) — stores per-user and per-device dispatch counters for total and per-day limits, with TTL-based expiry.
Kafka — carries async generation requests, bulk updates, persister writes, and dispatch audit events.
egov-persister — persists
save-in-id-pool,update-id-pool-status, andsave-dispatch-id-logevents into Postgres.health-services-common / -models — shared producers, validators, POJOs, and
ResponseInfoutilities.mdms-client and tracer — inherited support for MDMS access, correlation IDs, and exception handling.
Data Model
The service stores two kinds of state:
generated ID pool records
dispatch audit records
Key relationships:
each generated beneficiary ID lives in
id_pooldispatch assigns IDs from that pool to a user and device
id_transaction_logrecords who received which IDs and when
Flyway migrations for these tables live under db/migration/main.
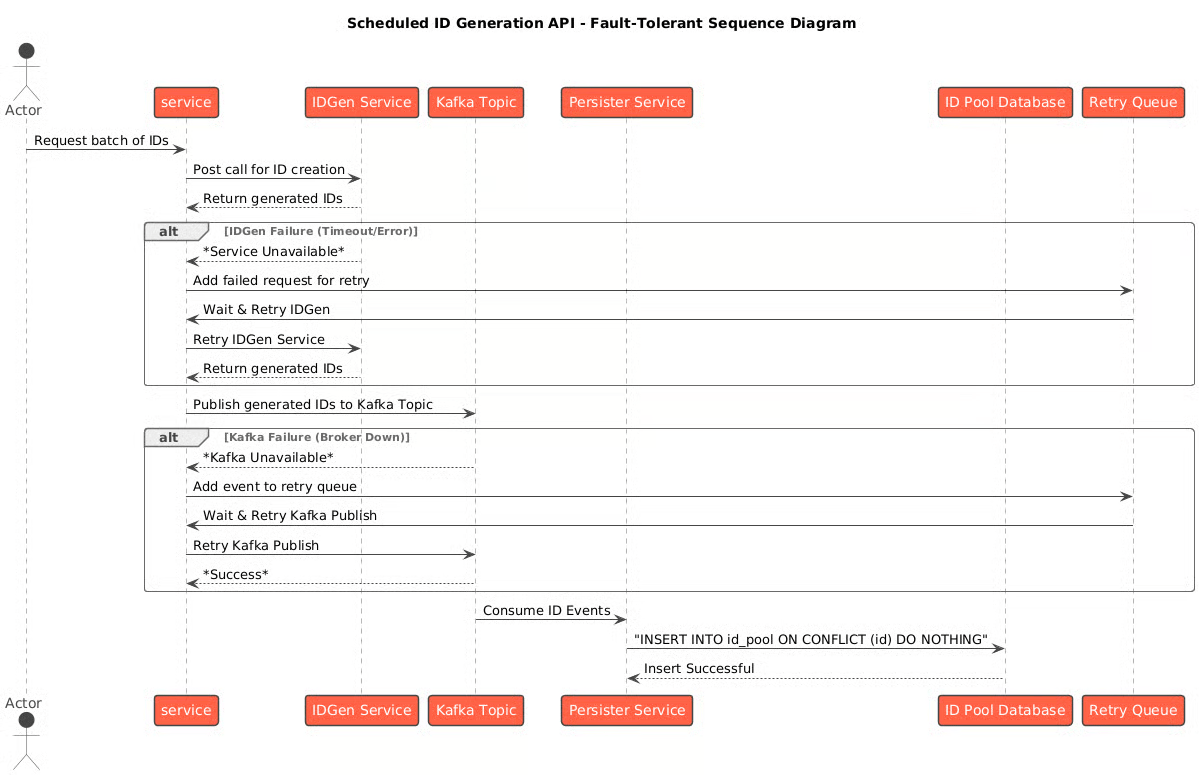
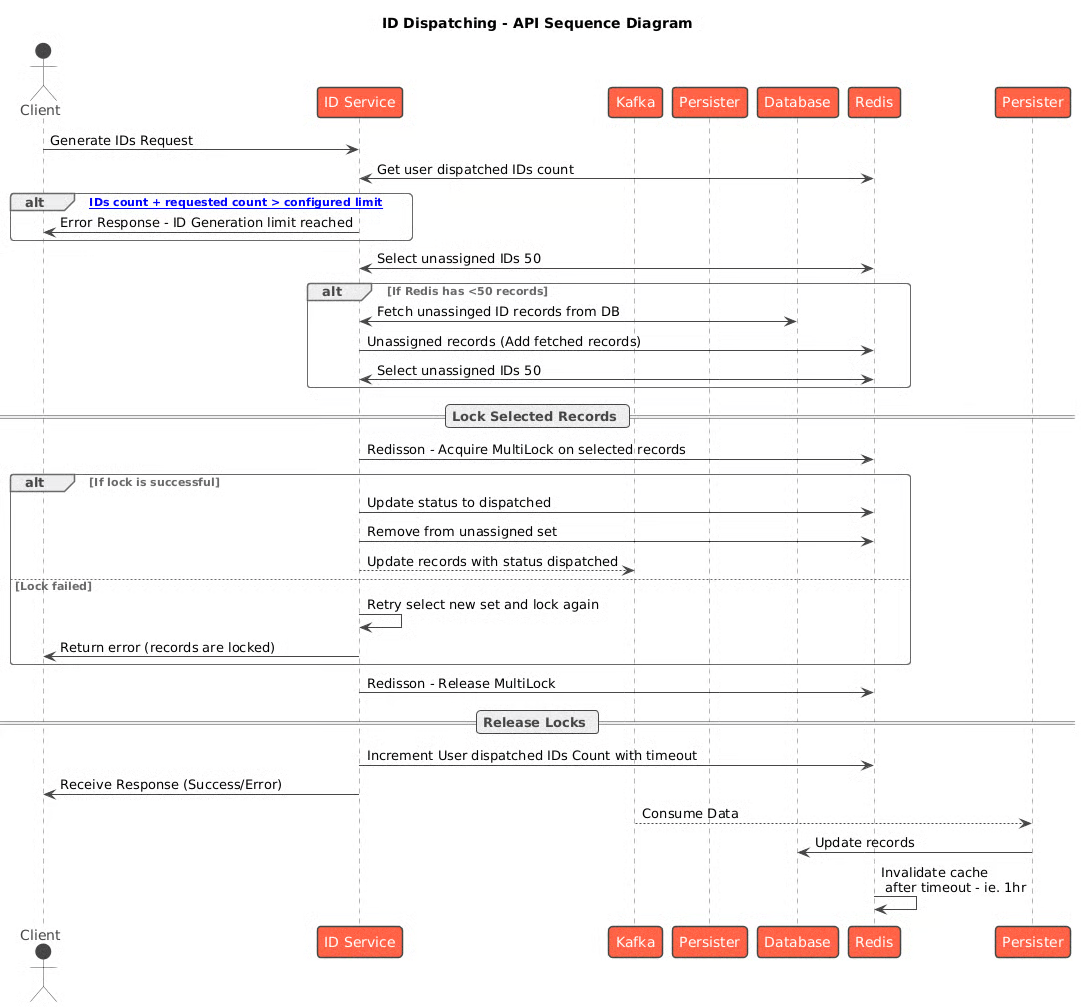
Web Sequence Diagrams

Business Flow
The service follows a simple four-step flow:
Generate pool. A setup or admin flow calls
_generatewith the tenant and requested count.Dispatch IDs. A field device calls
_dispatchto receive a reserved batch.Re-sync or search. The client can call
_dispatchwithfetchAllocatedIds=true, or use_searchto inspect pool records.Update status. The client calls
_updatelater to reconcile the issued IDs.
Generation is asynchronous because large pools can take time to mint.
Dispatch is online and allocation-safe.
The service ensures that two devices do not receive the same ID.
API Details
From a client's point of view:
_generateis asynchronous_dispatchand_searchare synchronous_updateis asynchronous bulk processing
POST /id_pool/_generate
Queue asynchronous generation of a tenant-specific pool of IDs. Returns immediately after the work is chunked and queued.
POST /id_pool/_dispatch
Allocate a block of unused IDs to one user + device, subject to total and daily limits. With fetchAllocatedIds=true, returns IDs already assigned to that device instead.
POST /id_pool/_search
Search ID pool records by ID list, status, and tenant.
POST /id_pool/_update
Accept an async bulk status update request for pool records, such as marking IDs as used.
Internal Flow
This section explains how the service implements the API behaviour internally.
Generation path. _generate splits the requested count into chunks and publishes them to id-gen-consumer-bulk-create-topic. The service's own consumer mints IDs from the configured format, then emits save-in-id-pool for persistence.
Dispatch path. _dispatch selects unused IDs from Postgres using locking semantics, checks total and daily quotas in Redis, assigns the IDs to the user and device, and emits audit events on save-dispatch-id-log.
Update path. _update publishes to id-gen-consumer-bulk-update-topic. The consumer validates the request and emits status changes on update-id-pool-status.
There is no published Swagger contract for this service under docs/health-api-specs/contracts/.
Kafka Topics
id-gen-consumer-bulk-create-topic
in
Bulk id-pool create requests
id-gen-consumer-bulk-update-topic
in
Bulk id-pool update requests
save-in-id-pool
out
Persist generated IDs into the pool
update-id-pool-status
out
Update ID status after dispatch or later reconciliation
save-dispatch-id-log
out
Persist dispatch audit logs
Process Flow
Use this reading order:
Queue generation.
_generatevalidates the request, splits it into chunks, and queues the work.Mint and persist. The consumer expands the format, generates unique IDs, and persists them into
id_pool.Dispatch atomically.
_dispatchdraws from the unused pool, applies limits, and assigns IDs to one user and device.Inspect or reconcile.
_searchreads back pool state, and_updateapplies later lifecycle changes.Audit the action. Dispatch and update flows write audit data for tracing and reconciliation.
The generate and update paths are asynchronous.
Dispatch happens in-line, but uses DB locking and Redis counters to stay safe.

Failure & Retry Handling
Generation never blocks the caller and never half-fails the request.
_generatereturns once chunks are queued; the actual minting happens in the consumer. If a chunk fails, it is logged and the request is not retried automatically.Dispatch is concurrency-safe. The pool draw uses
FOR UPDATE SKIP LOCKED, so simultaneous dispatches skip locked rows rather than deadlock or double-allocate.Dispatch limits are enforced. Per-user and per-device total and per-day caps are checked against Redis counters. Exceeding them returns
USER_DEVICE_LIMIT_EXCEEDED.No IDs left returns
NO IDS AVAILABLE— a signal that the pool needs topping up via_generate.Random-format buffer. When a format contains a random pattern, the batch is over-generated by a configurable buffer percentage to absorb collisions. The pool insert uses
ON CONFLICT (id) DO NOTHING, so duplicate random IDs are dropped rather than failing the batch.Persister dependency trap. If persister wiring for these topics is missing or stale in an environment, the API can accept generate or update work while rows silently never appear in Postgres.
Known Risks & Limitations
The pool must be filled before it can be drawn from.
_dispatchonly hands out IDs that_generatehas already minted. An empty or exhausted pool returnsNO IDS AVAILABLE.Two stores must agree. The authoritative pool is in Postgres, but dispatch quotas live in Redis. If Redis is flushed or lost, quota tracking resets even though Postgres still shows IDs as dispatched.
Limits are per user + device, keyed by date in a configured timezone. "Per day" boundaries follow
id.timezoneorapp.timezone. A bad timezone shifts when a quota resets.Generation failures are swallowed in the consumer — logged, but not retried. There is no dead-letter queue today, so a failed chunk simply means fewer IDs in the pool.
_updatevalidation assumes a single tenant per bulk request. It readstenantIdfrom the first record, so mixed-tenant batches are not supported.ID status and format correctness are largely convention-driven. A malformed MDMS
IdFormatsurfaces during generation time, not at configuration time.
Recent Changes
Last updated
Was this helpful?