
🌠Referral Management
Overview
Referral Management records follow-up care during a health campaign. Field workers use it when a beneficiary needs care that cannot be provided immediately. It helps facilities and workers continue that care.
It manages three related records:
Referral — records further care for a beneficiary. It identifies the referrer, recipient, reason, and any triggering side effect.
Side Effect — records an adverse reaction after a campaign task, such as a vaccine dose.
HF Referral (Health Facility referral) — records a referral created at or for a health facility. It includes symptoms and a referral code.
A referral links to its campaign project and beneficiary. It can also link to its originating side effect. An HF referral links to its project facility and locality.
It also powers the offline-first mobile app: it can bulk-pull everything a device needs for a locality in one call (the downsync endpoint), so workers can keep operating with no network.
In short: "who got sent for follow-up, why, and what does the offline app need to carry with it?"
Business Flow
During the campaign (runtime), field workers register referrals and side effects from the mobile app — usually offline, queued, and pushed up when connectivity returns.
Health-facility staff/distributors raise HF referrals tied to a project facility and locality.
Every record links back to the campaign context — the project, the project beneficiary, and (for referrals) the originating side effect — so follow-up is traceable to the right person and campaign.
The mobile app periodically downsyncs a locality's data (households, members, beneficiaries, tasks, referrals, side effects, HF referrals) so a worker has the full picture on-device.
The records feed the dashboards (via the transformer/indexer → Elasticsearch) so programme managers can see referral and adverse-event volumes.
Key APIs / Entry Points
All endpoints use the /referralmanagement base path. The table omits this base path. Referral, side effect, and HF referral each support create, update, delete, bulk operations, and search. The remaining endpoints support offline sync.
POST /v1/_create, /v1/bulk/_create
Record a referral (single or bulk).
POST /v1/_update · /v1/_delete (+ /bulk/…)
Correct or soft-delete a referral.
POST /v1/_search
Find referrals (by beneficiary, project, ids, since-time …; supports includeOnlyUpdatedByOthers).
POST /side-effect/v1/_create … _search (+ bulk)
Same shape for adverse-event records.
POST /hf-referral/v1/_create … _search (+ bulk)
Same shape for health-facility referrals.
POST /beneficiary-downsync/v1/_get
Offline bulk pull — everything a locality needs in one response (or pre-generated file links).
POST /downsync/v1/_generate · /downsync/v1/jobs/_search
Kick off background generation of downsync files for a tenant/project, and poll the job.
Kafka entry points (async). Bulk requests land on save-referral-bulk-topic / update-… / delete-… (and the side-effect / hf-referral equivalents) and are processed by the service's own consumer. Persisted results go out on save-referral-topic / update-referral-topic / delete-referral-topic (+ side-effect and hf-referral topics) for the persister and transformer.
Swagger contract:

Kafka topics
save-referral-bulk-topic
in
Bulk referral create requests
update-referral-bulk-topic
in
Bulk referral update requests
delete-referral-bulk-topic
in
Bulk referral delete requests
save-side-effect-bulk-topic
in
Bulk side-effect create requests
update-side-effect-bulk-topic
in
Bulk side-effect update requests
delete-side-effect-bulk-topic
in
Bulk side-effect delete requests
save-hfreferral-bulk-topic
in
Bulk HF-referral create requests
update-hfreferral-bulk-topic
in
Bulk HF-referral update requests
delete-hfreferral-bulk-topic
in
Bulk HF-referral delete requests
save-referral-topic
out
Persist new referrals
update-referral-topic
out
Persist referral updates
delete-referral-topic
out
Persist referral soft-deletes
save-side-effect-topic
out
Persist new side-effects
update-side-effect-topic
out
Persist side-effect updates
delete-side-effect-topic
out
Persist side-effect soft-deletes
save-hfreferral-topic
out
Persist new HF-referrals
update-hfreferral-topic
out
Persist HF-referral updates
delete-hfreferral-topic
out
Persist HF-referral soft-deletes
Dependencies
idgen — generates referral/side-effect / hf-referral ids.
project — validates the project, project-beneficiary, project-task and project-facility a record links to.
facility — validates the health facility an HF referral is for.
household/individual — read during downsync to assemble the full beneficiary bundle.
service-request — optional services pulled into downsync when enabled.
MDMS — resolves project type/beneficiary type used to drive downsync.
egov-enc-service — decrypts beneficiary fields where needed during downsync.
health-services-common / -models — shared clients, validators, POJOs (the
Referral,SideEffect,HFReferralmodels live here).Kafka — async create/update/delete pipeline.
egov-persister (deployed via the
configs/repo) — actually writes the rows to Postgres off thesave-*topics.transformer/indexer → Elasticsearch — builds the dashboard read-model from the same topics.
Redis — caches incoming bulk referrals before the consumer processes them (and search caching in the shared repository layer).
S3 (object storage) — stores pre-generated downsync files; the service hands back time-limited download links.
Process Flow
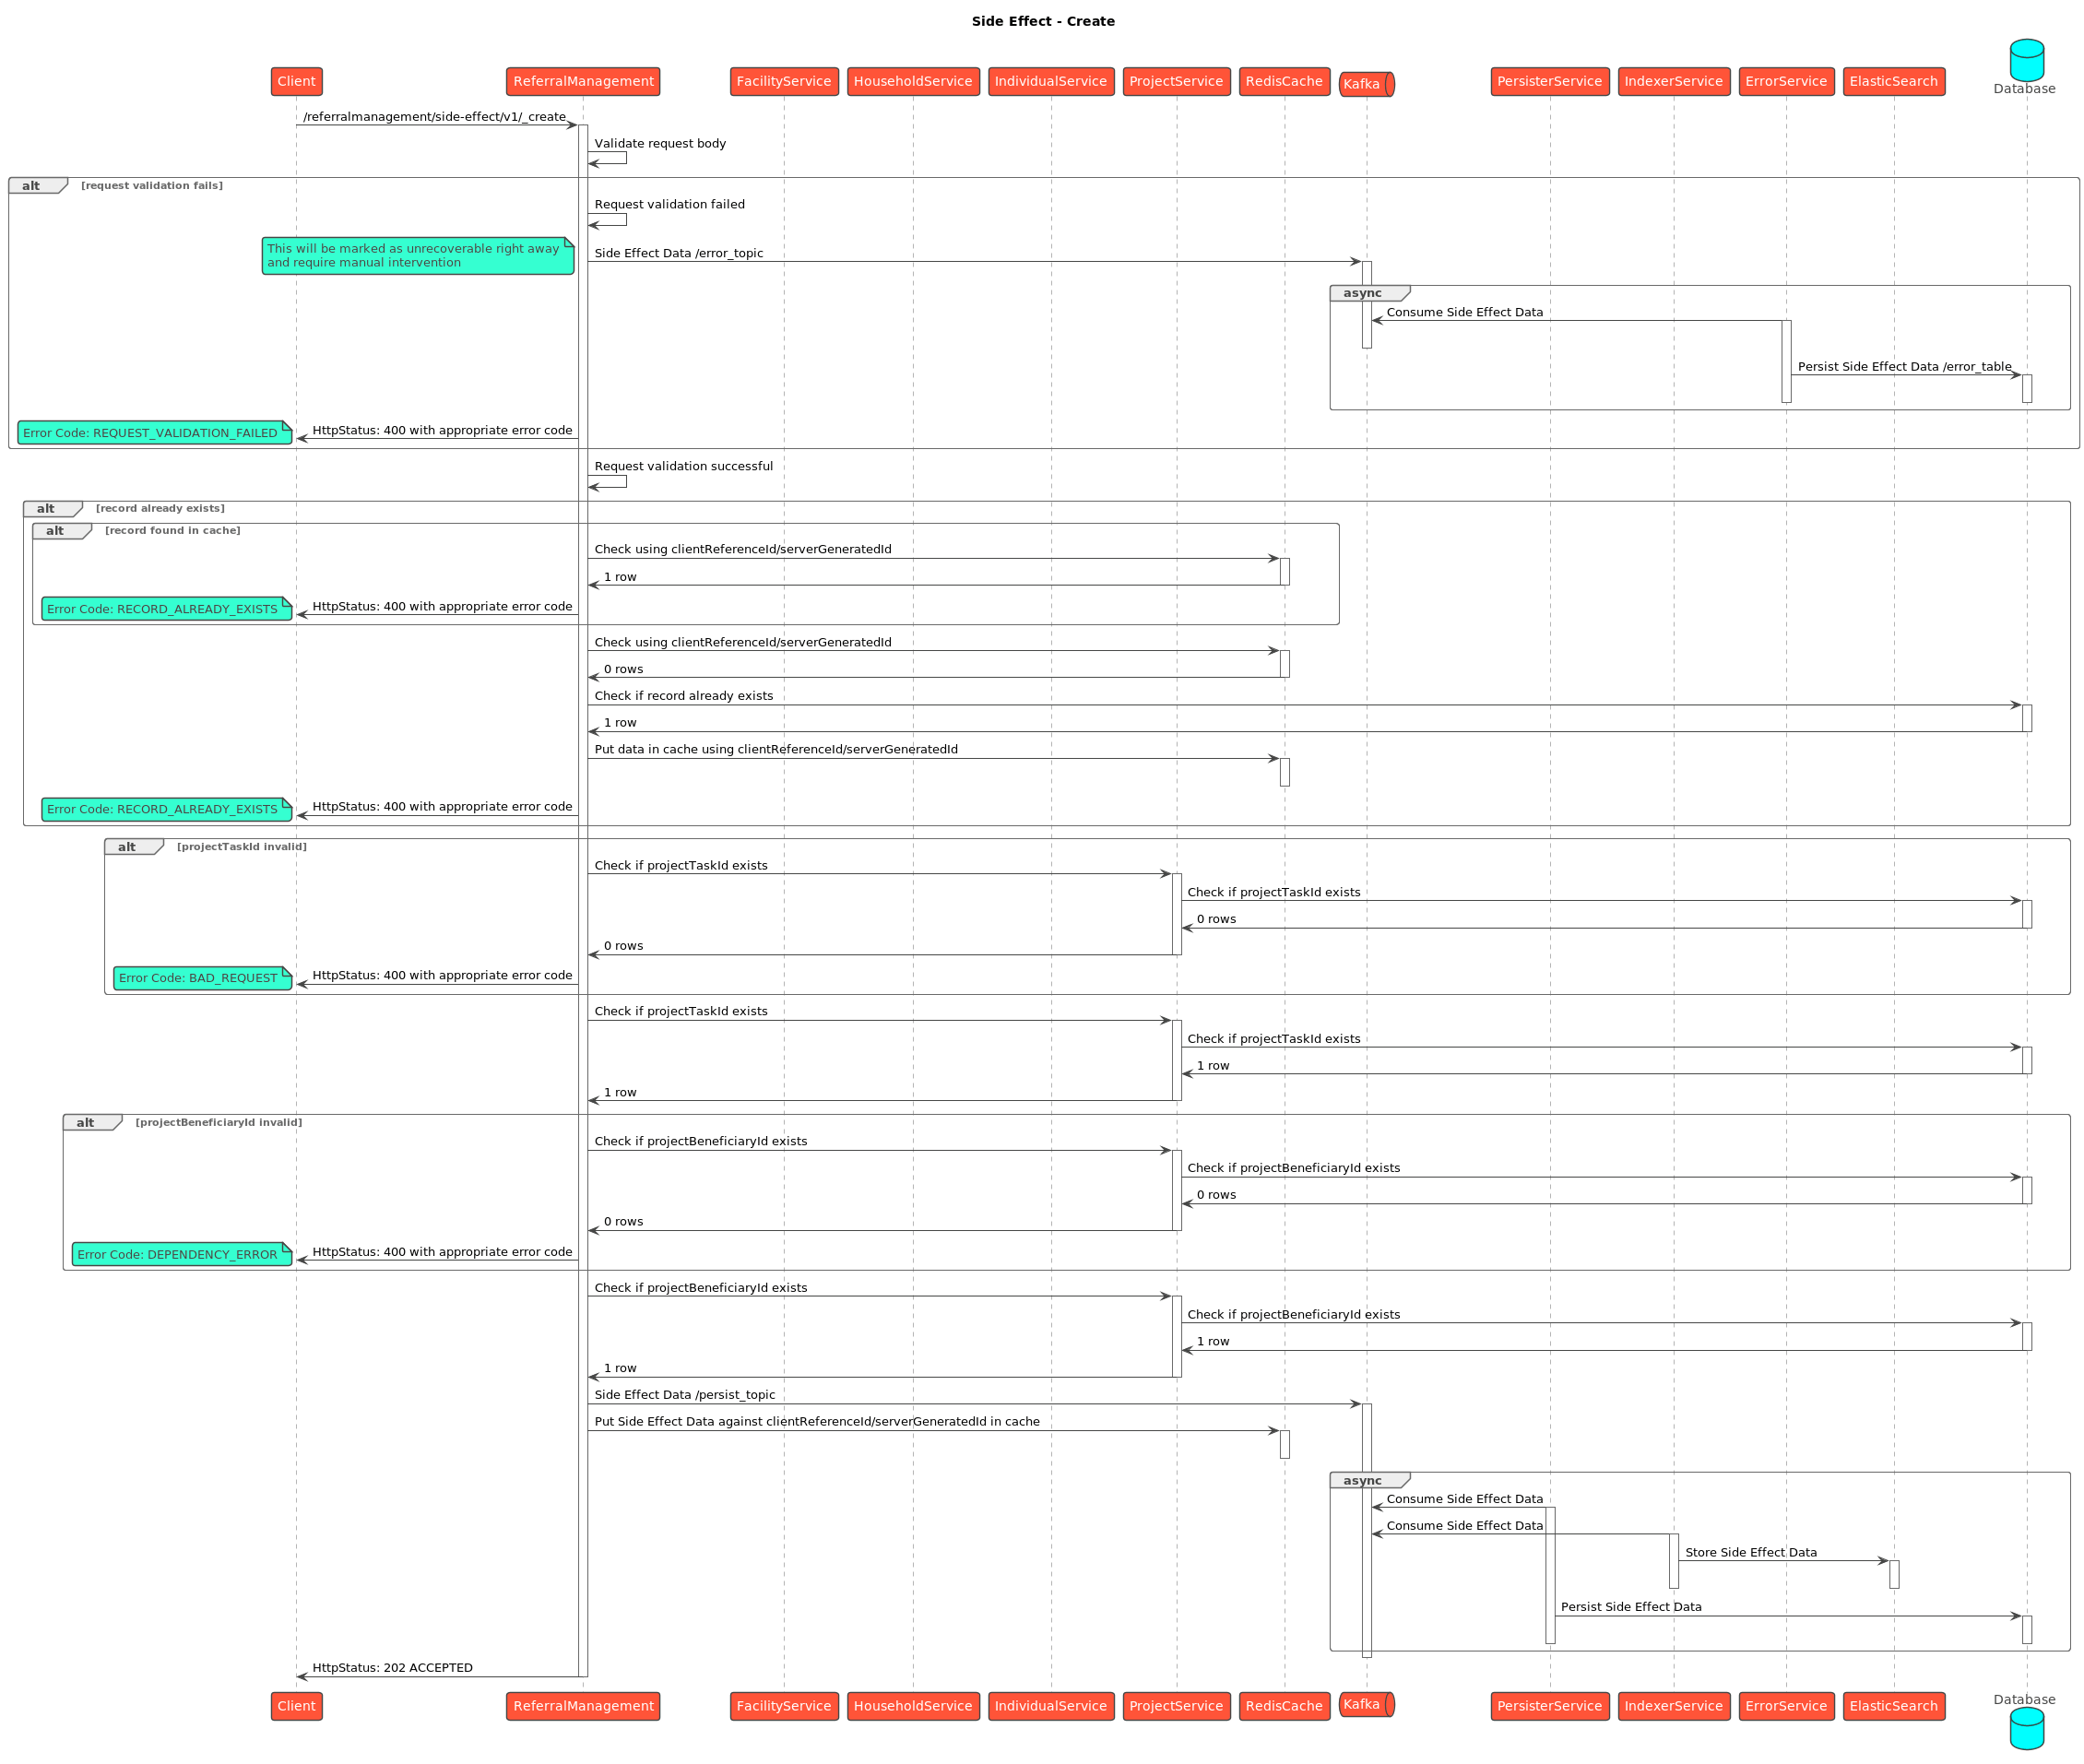
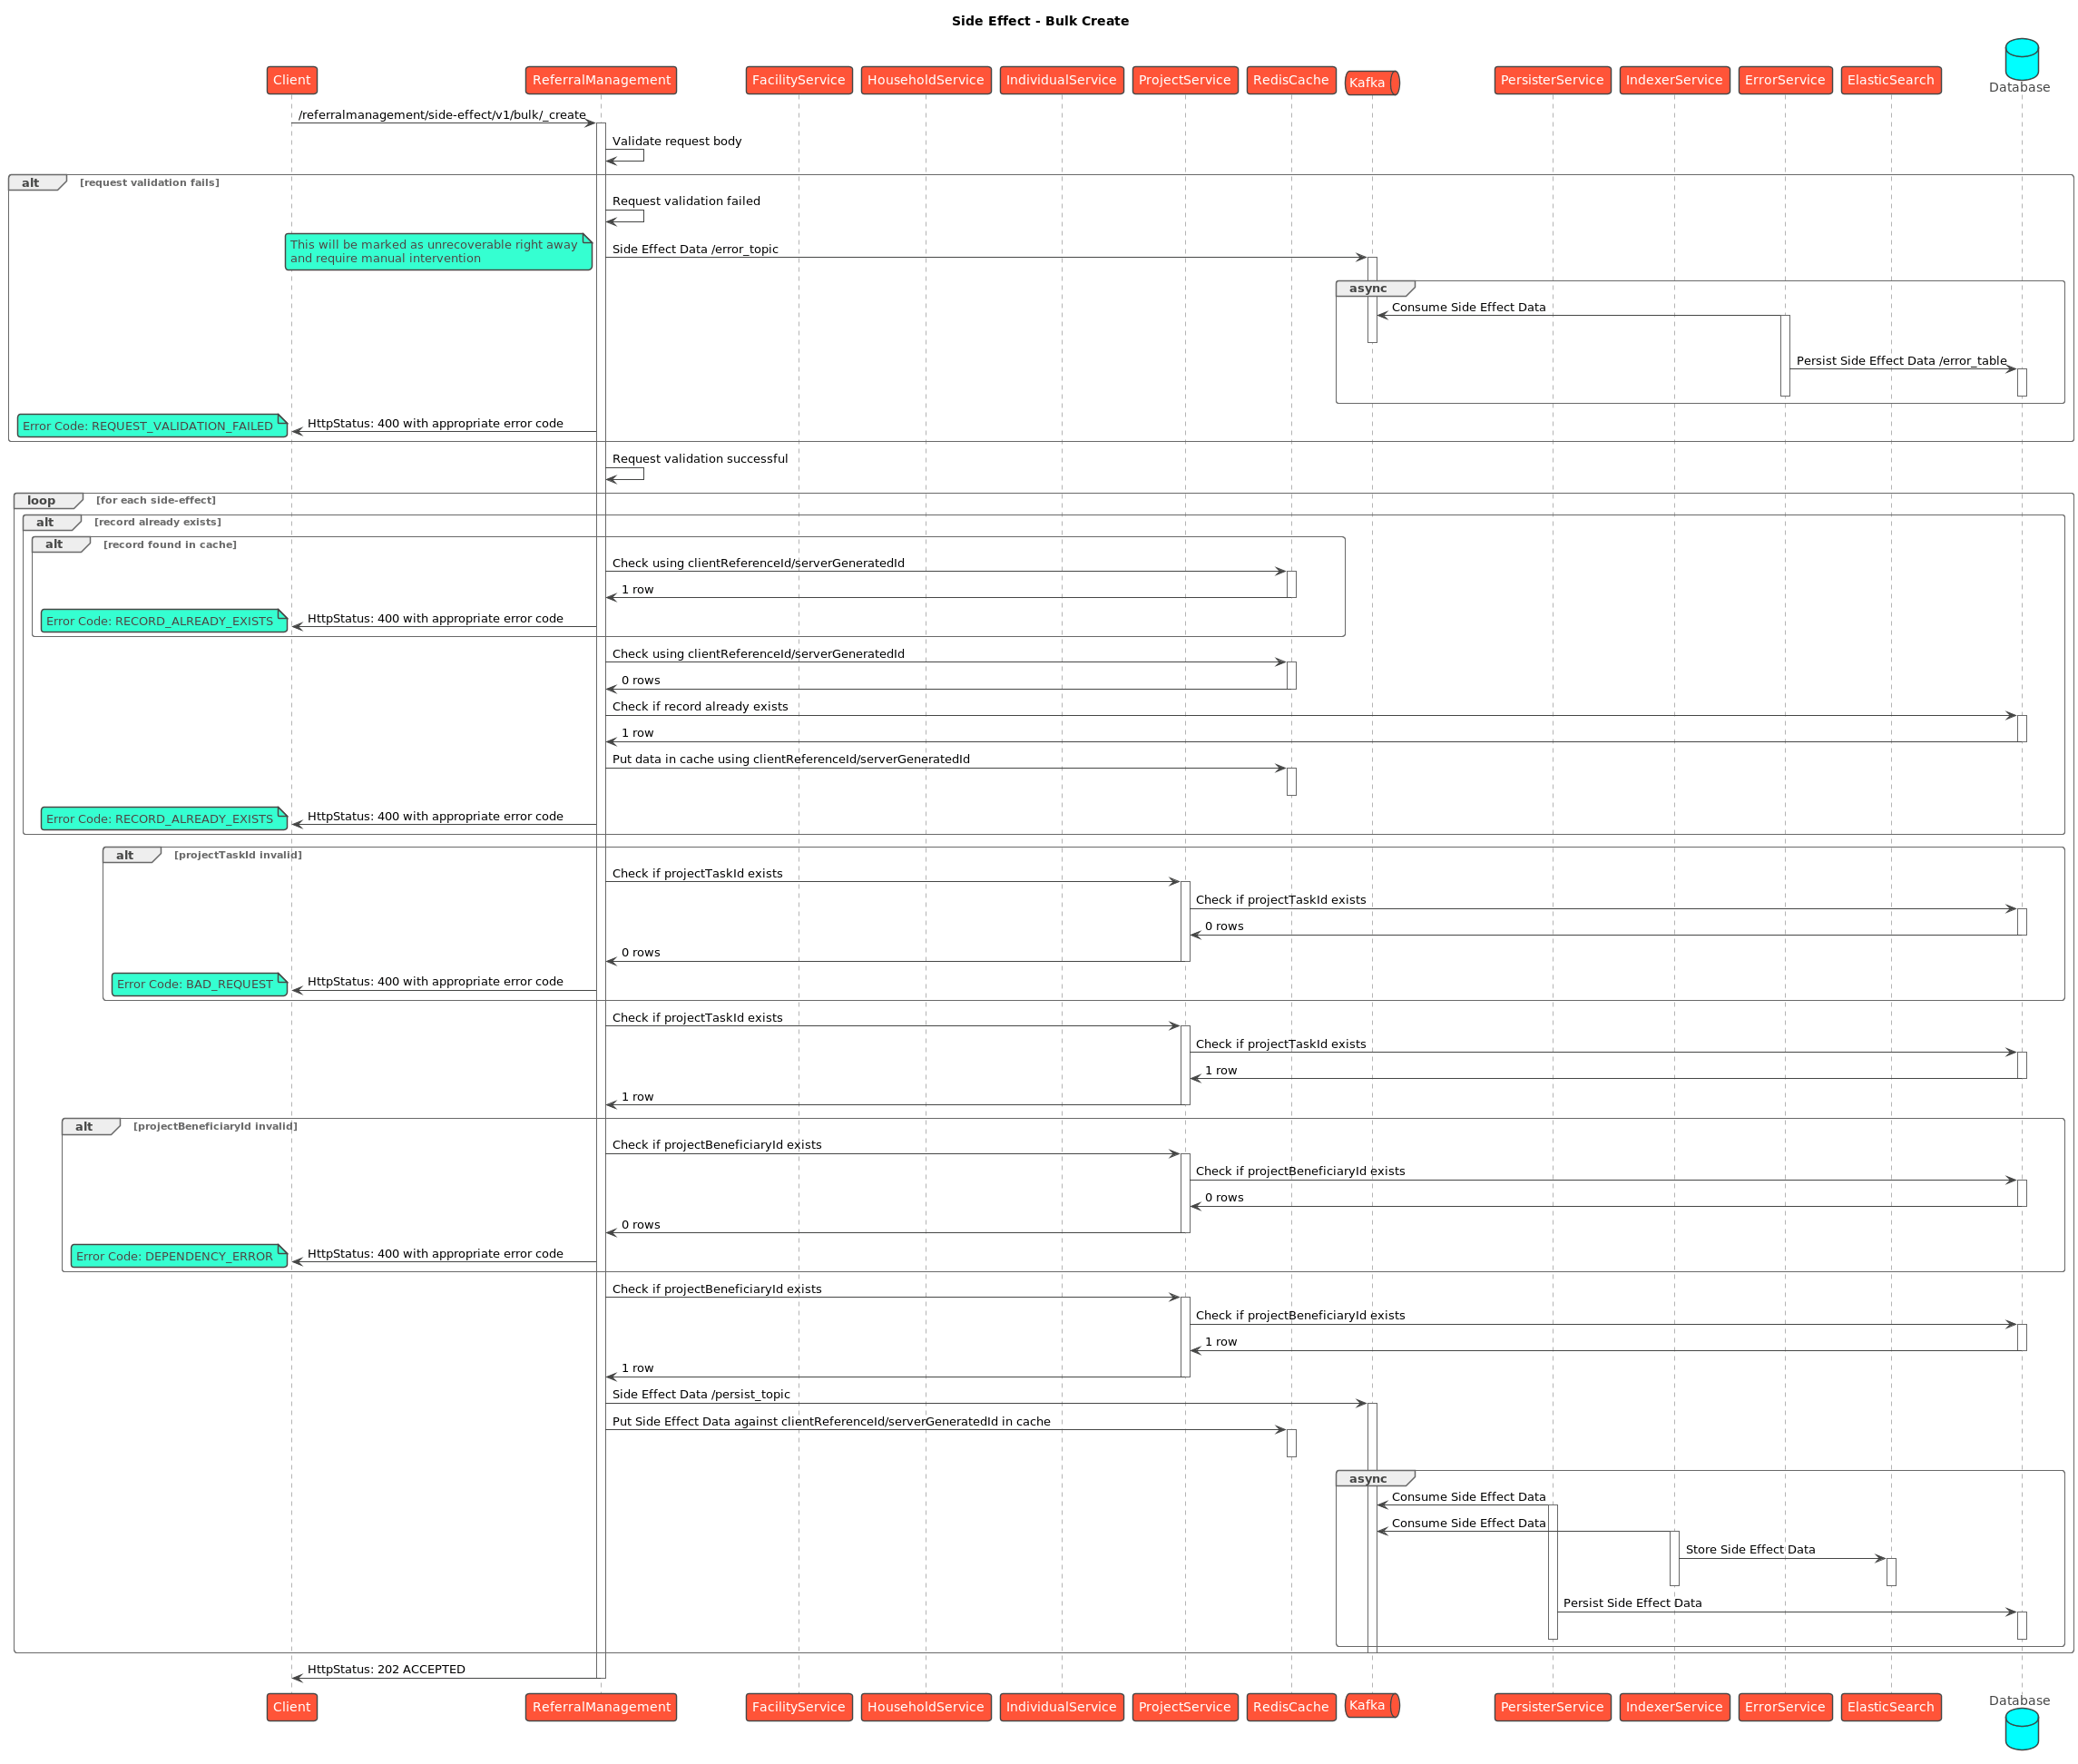
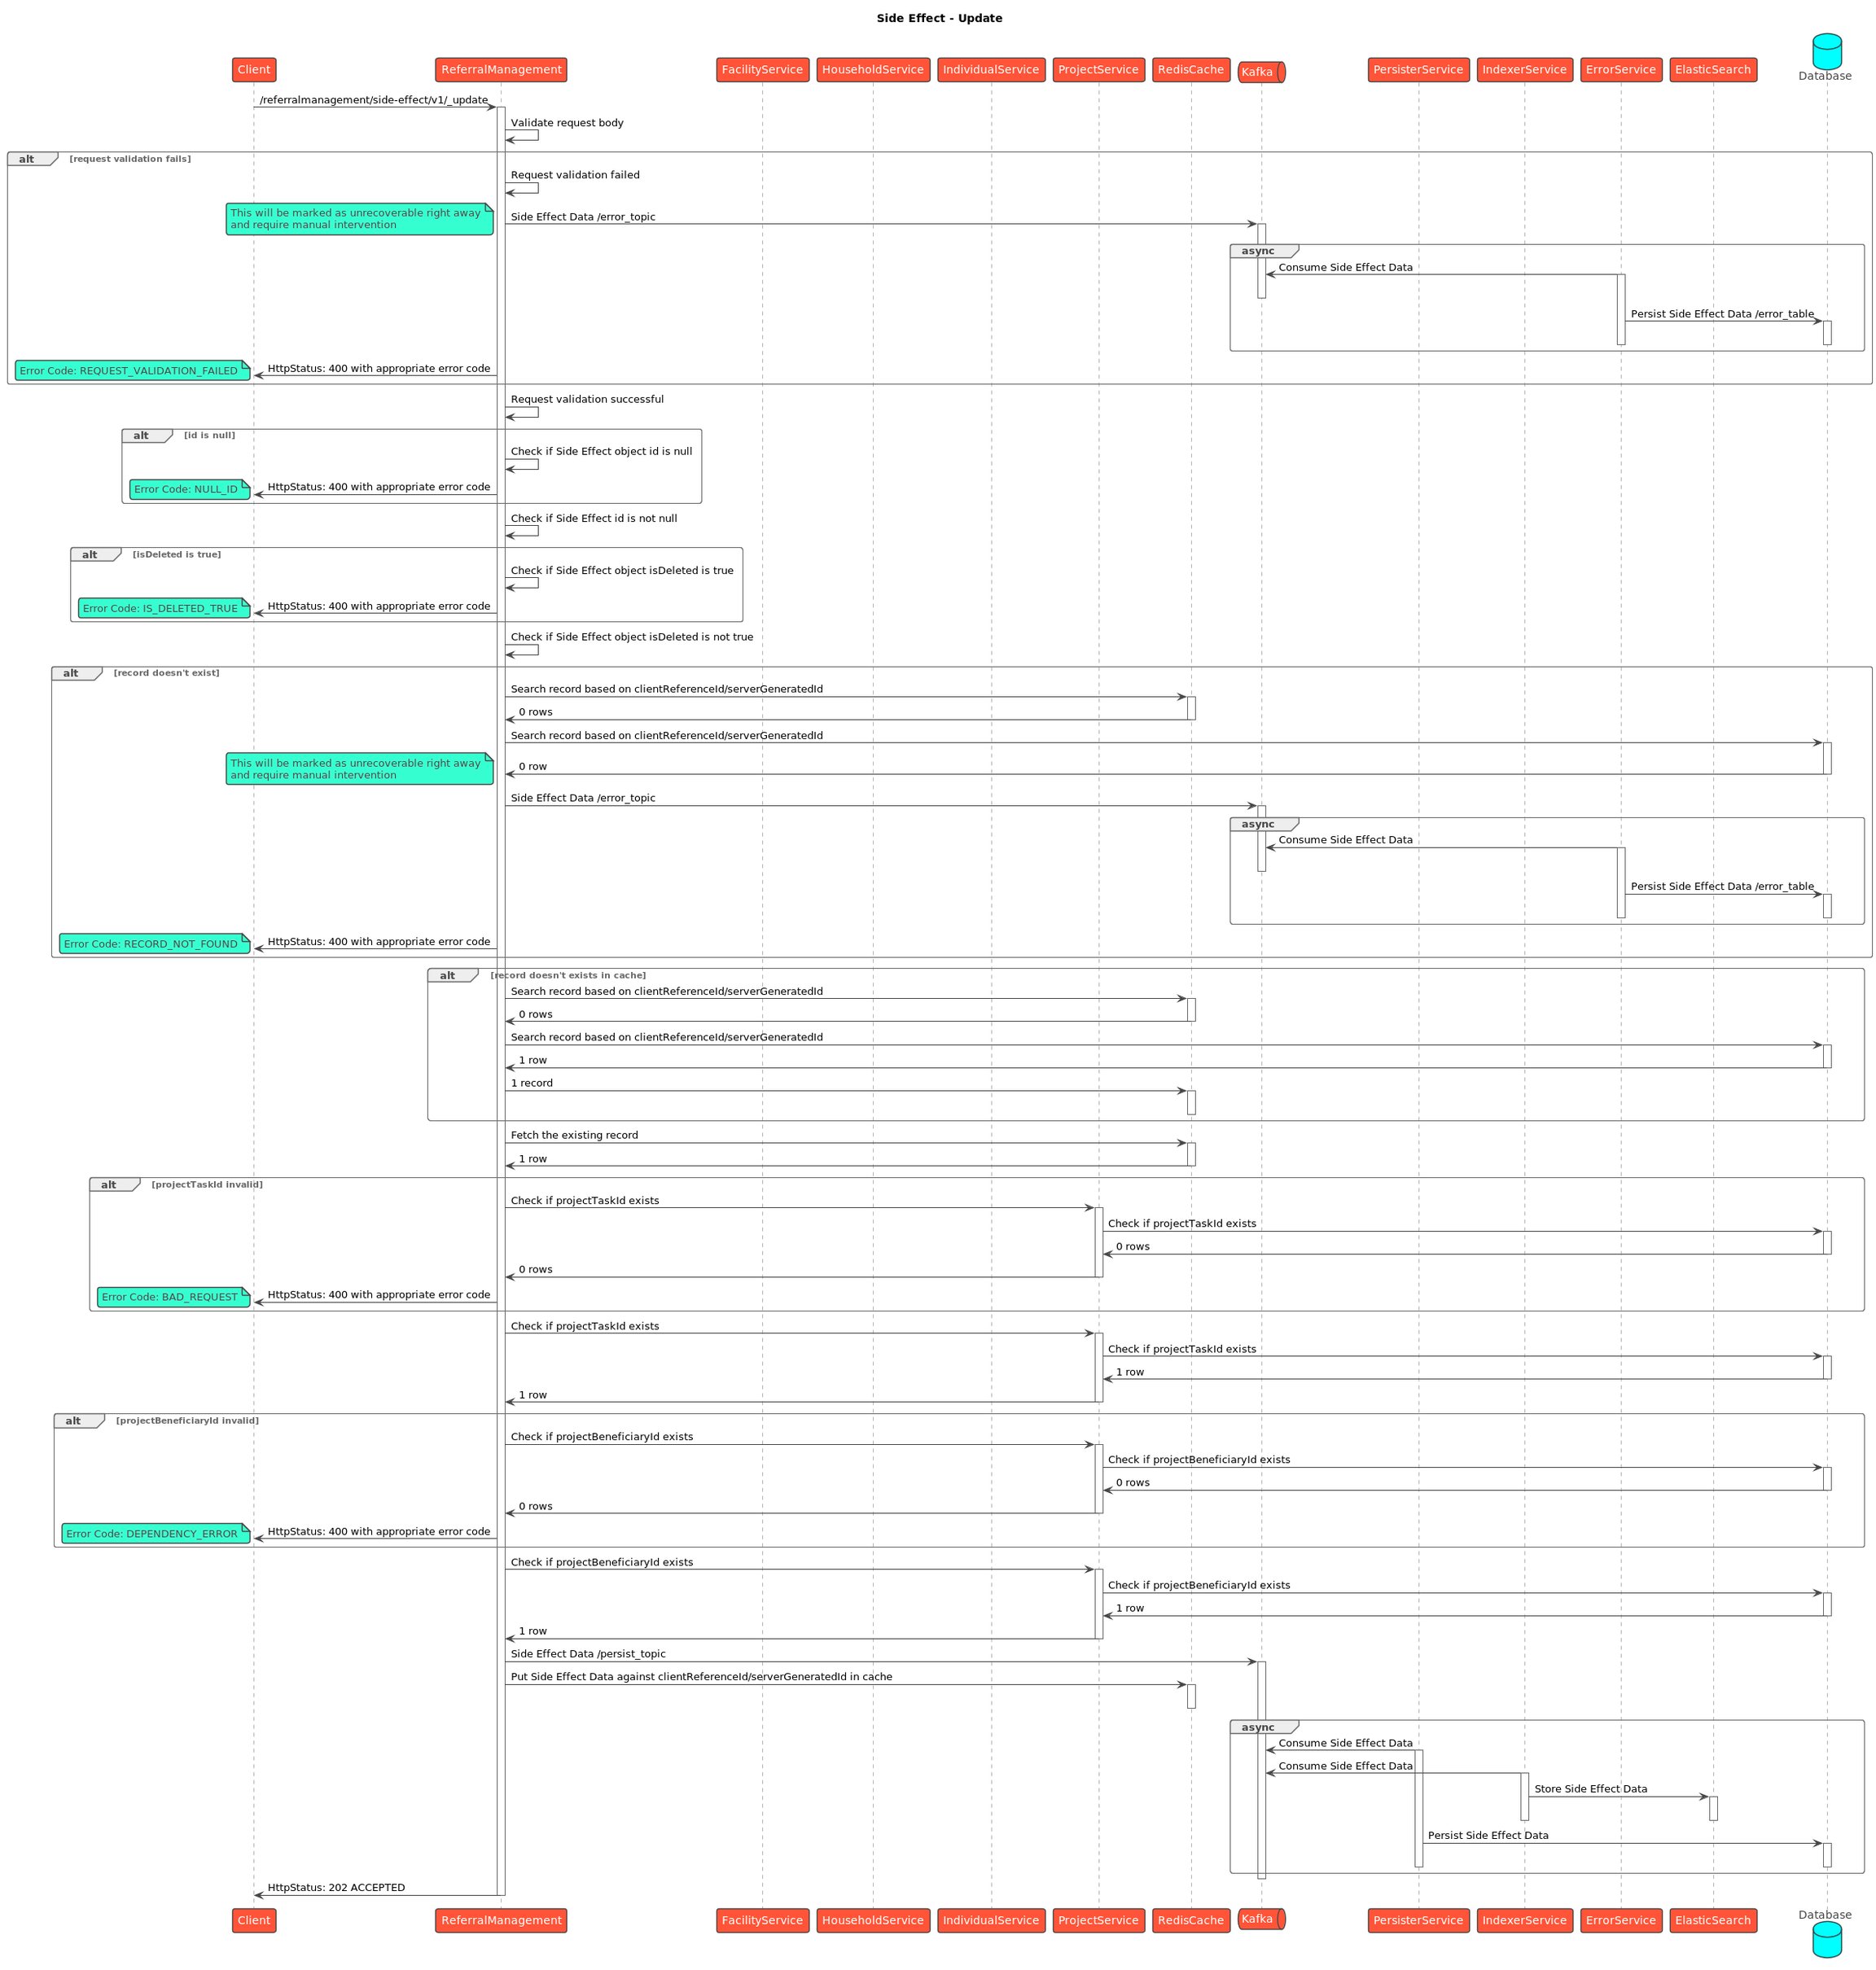
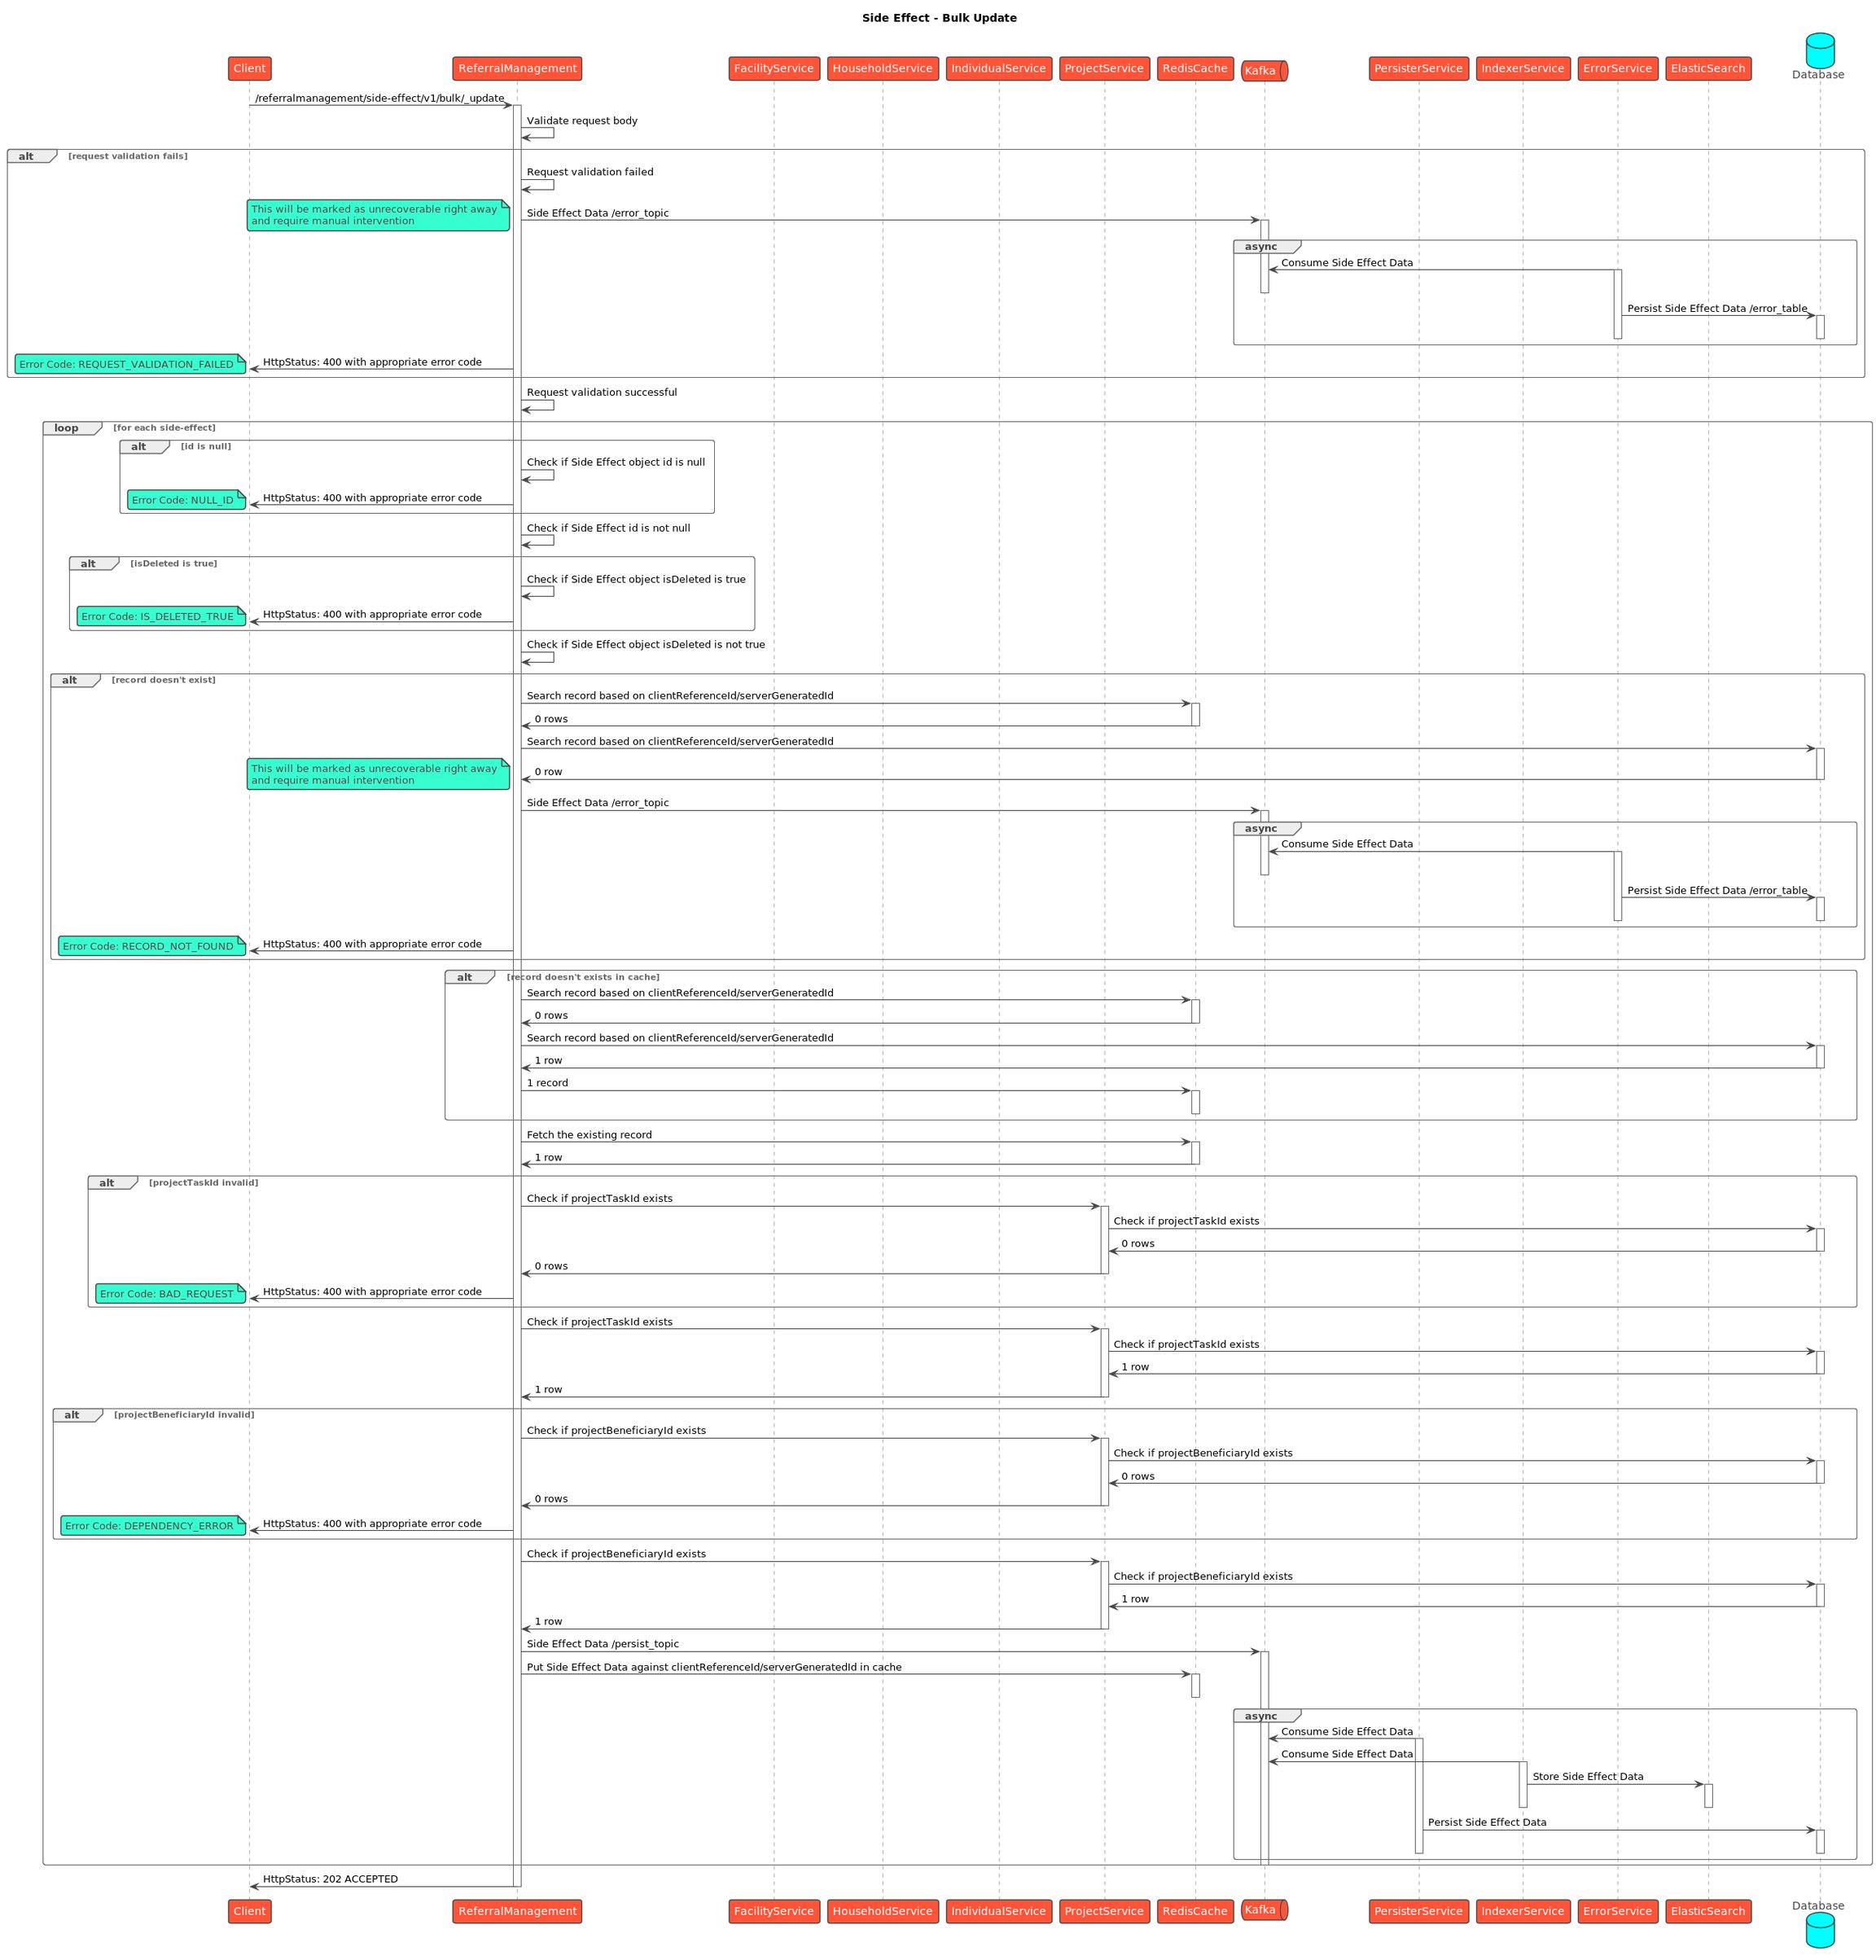
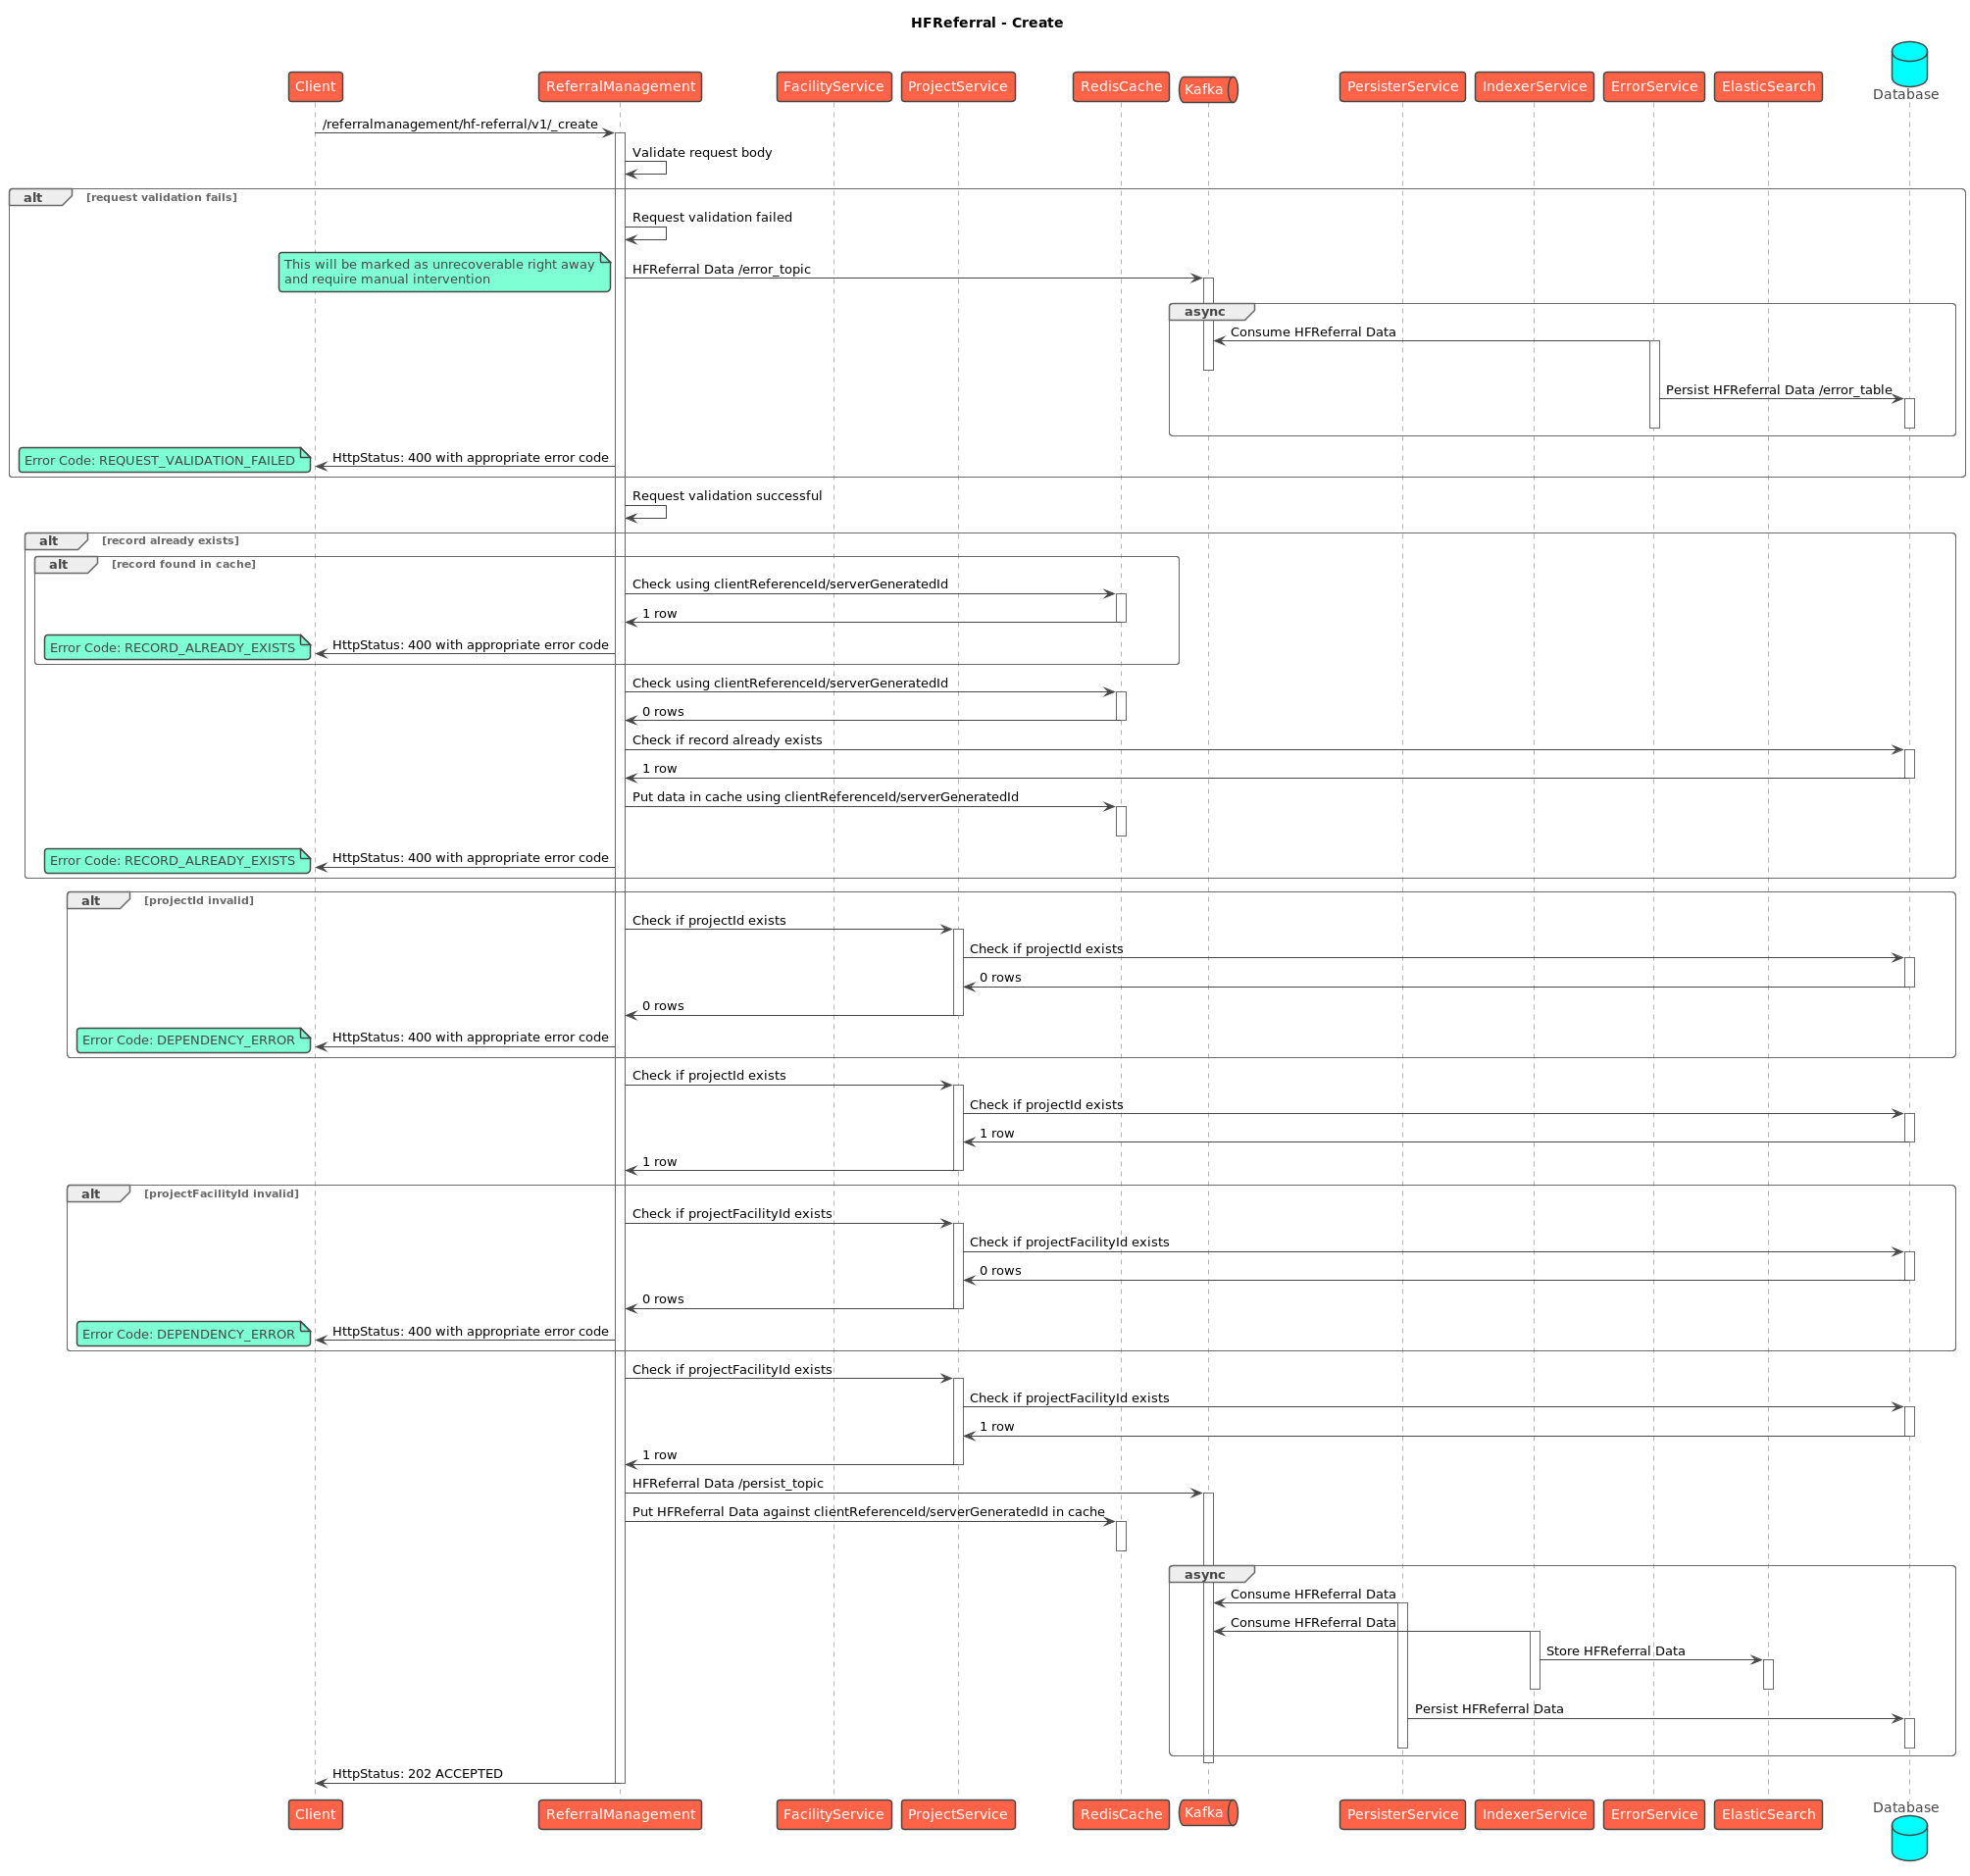
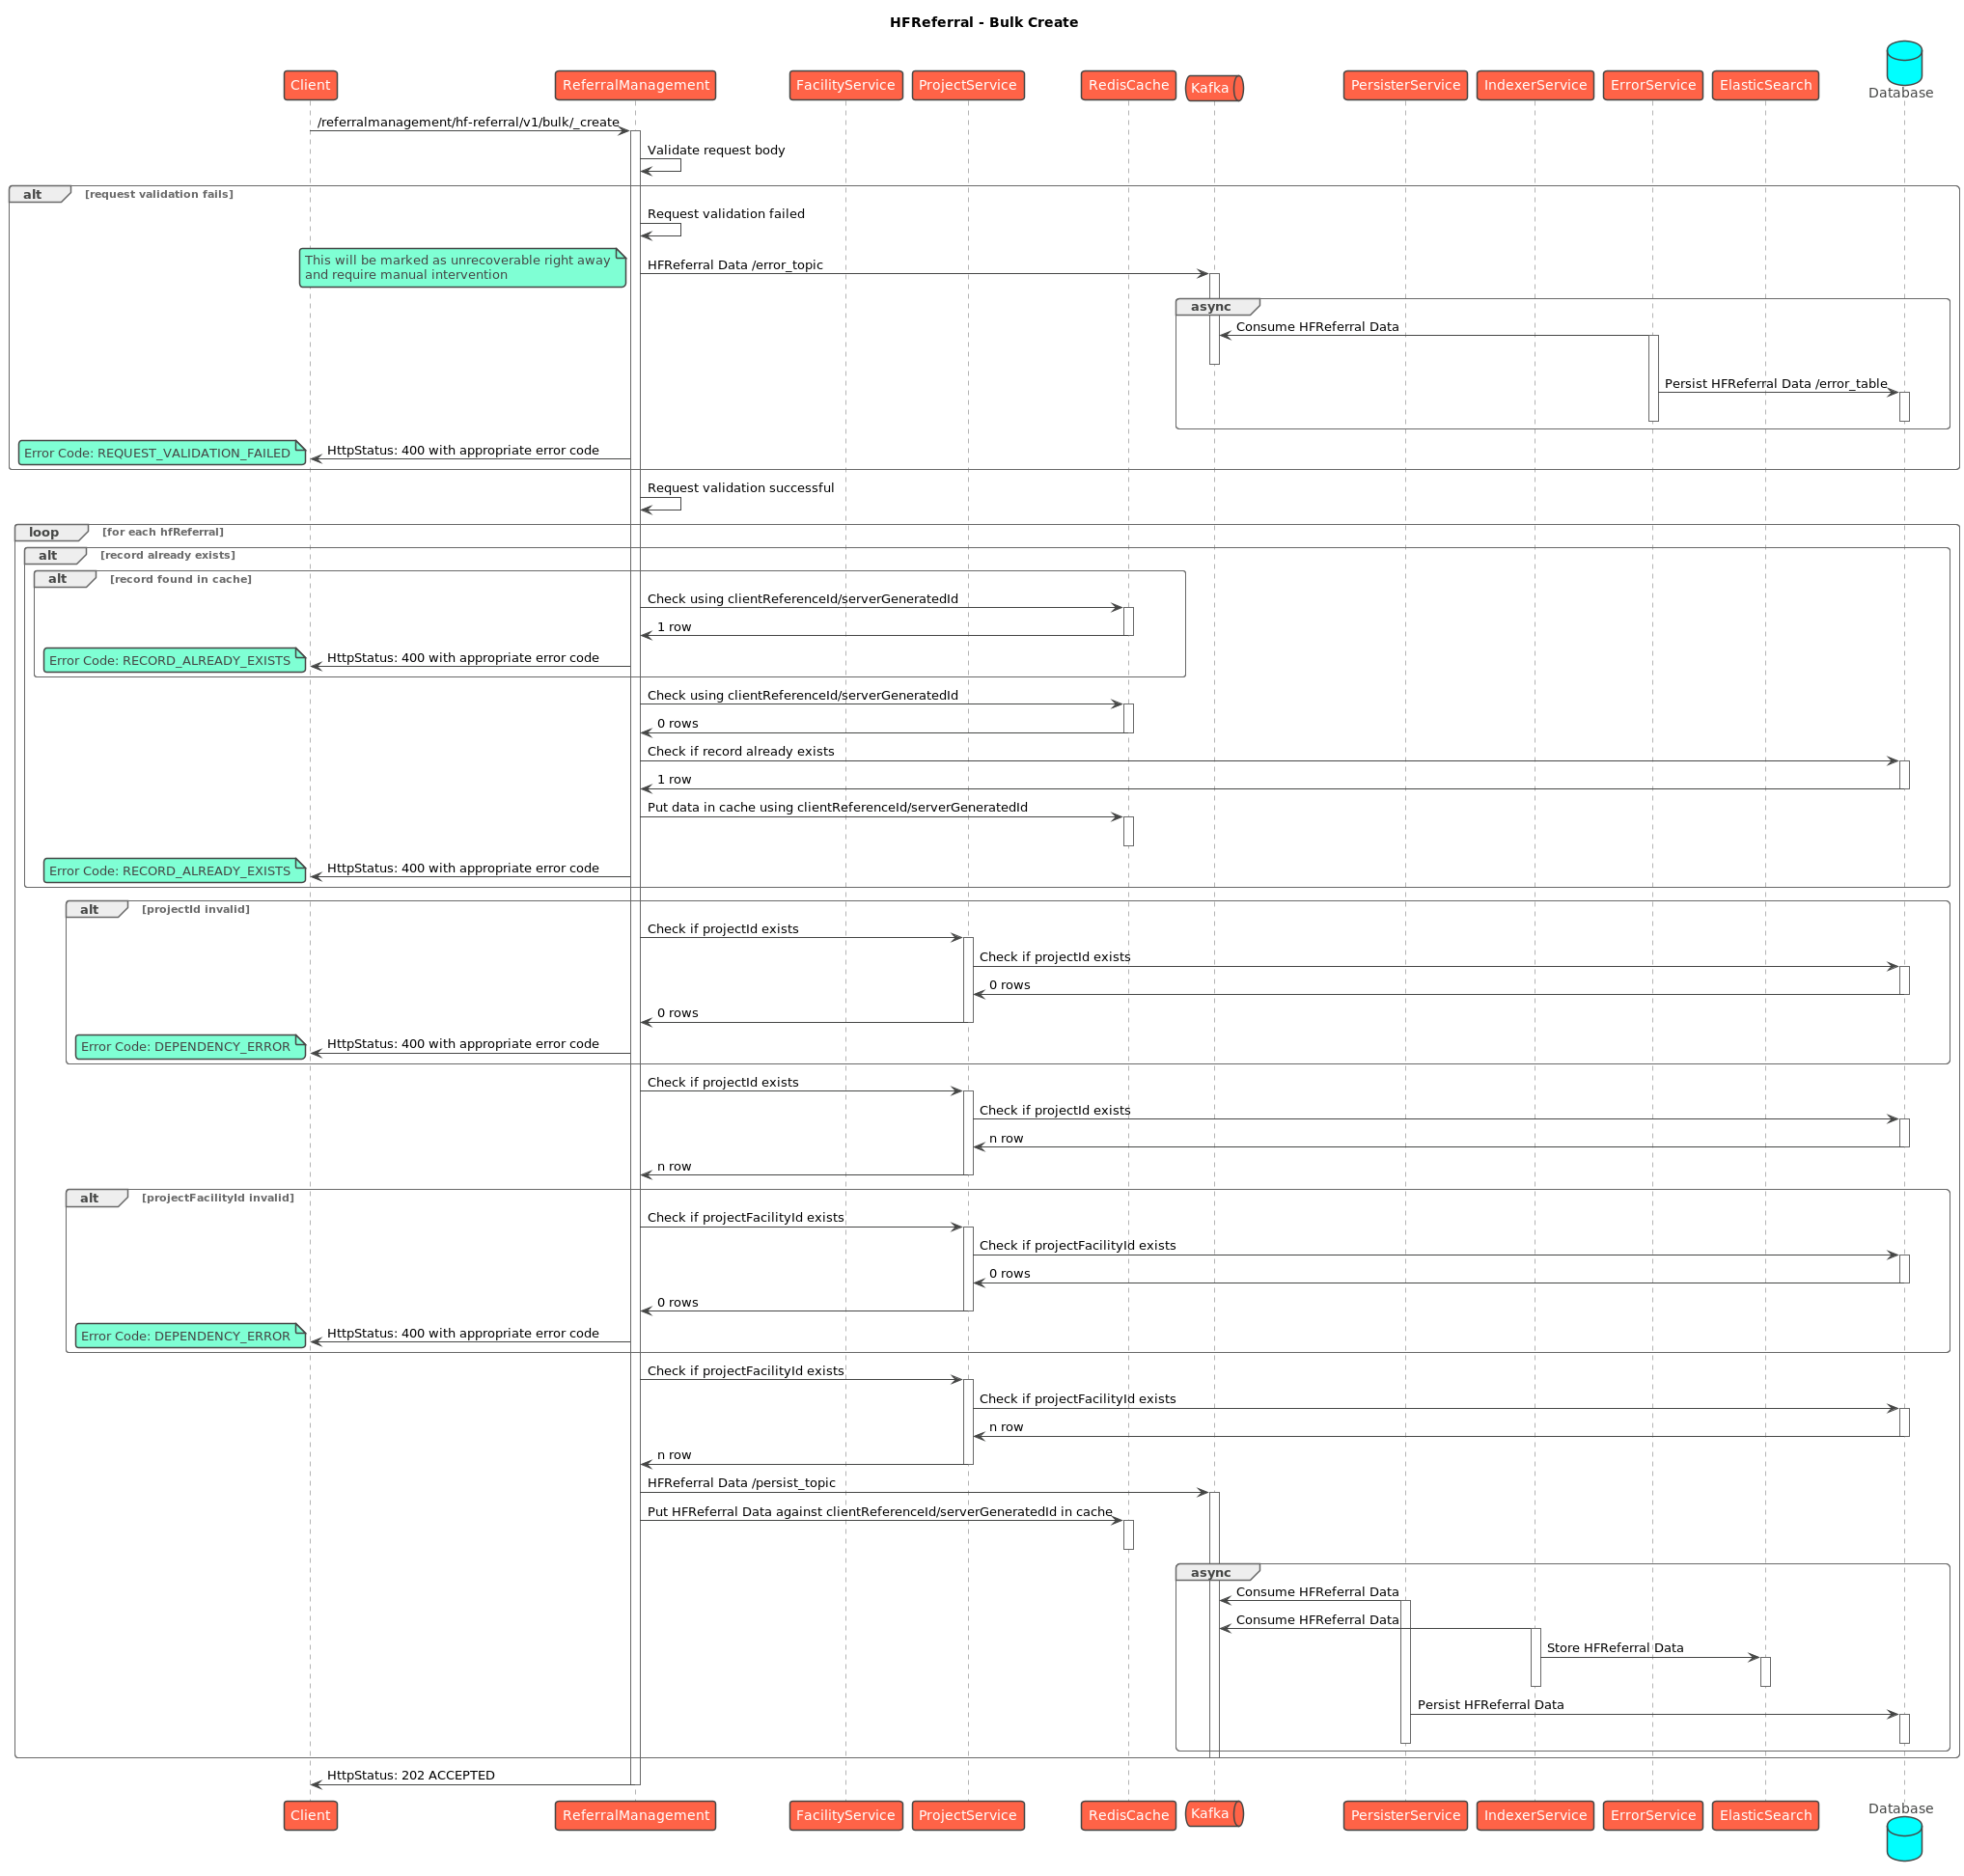
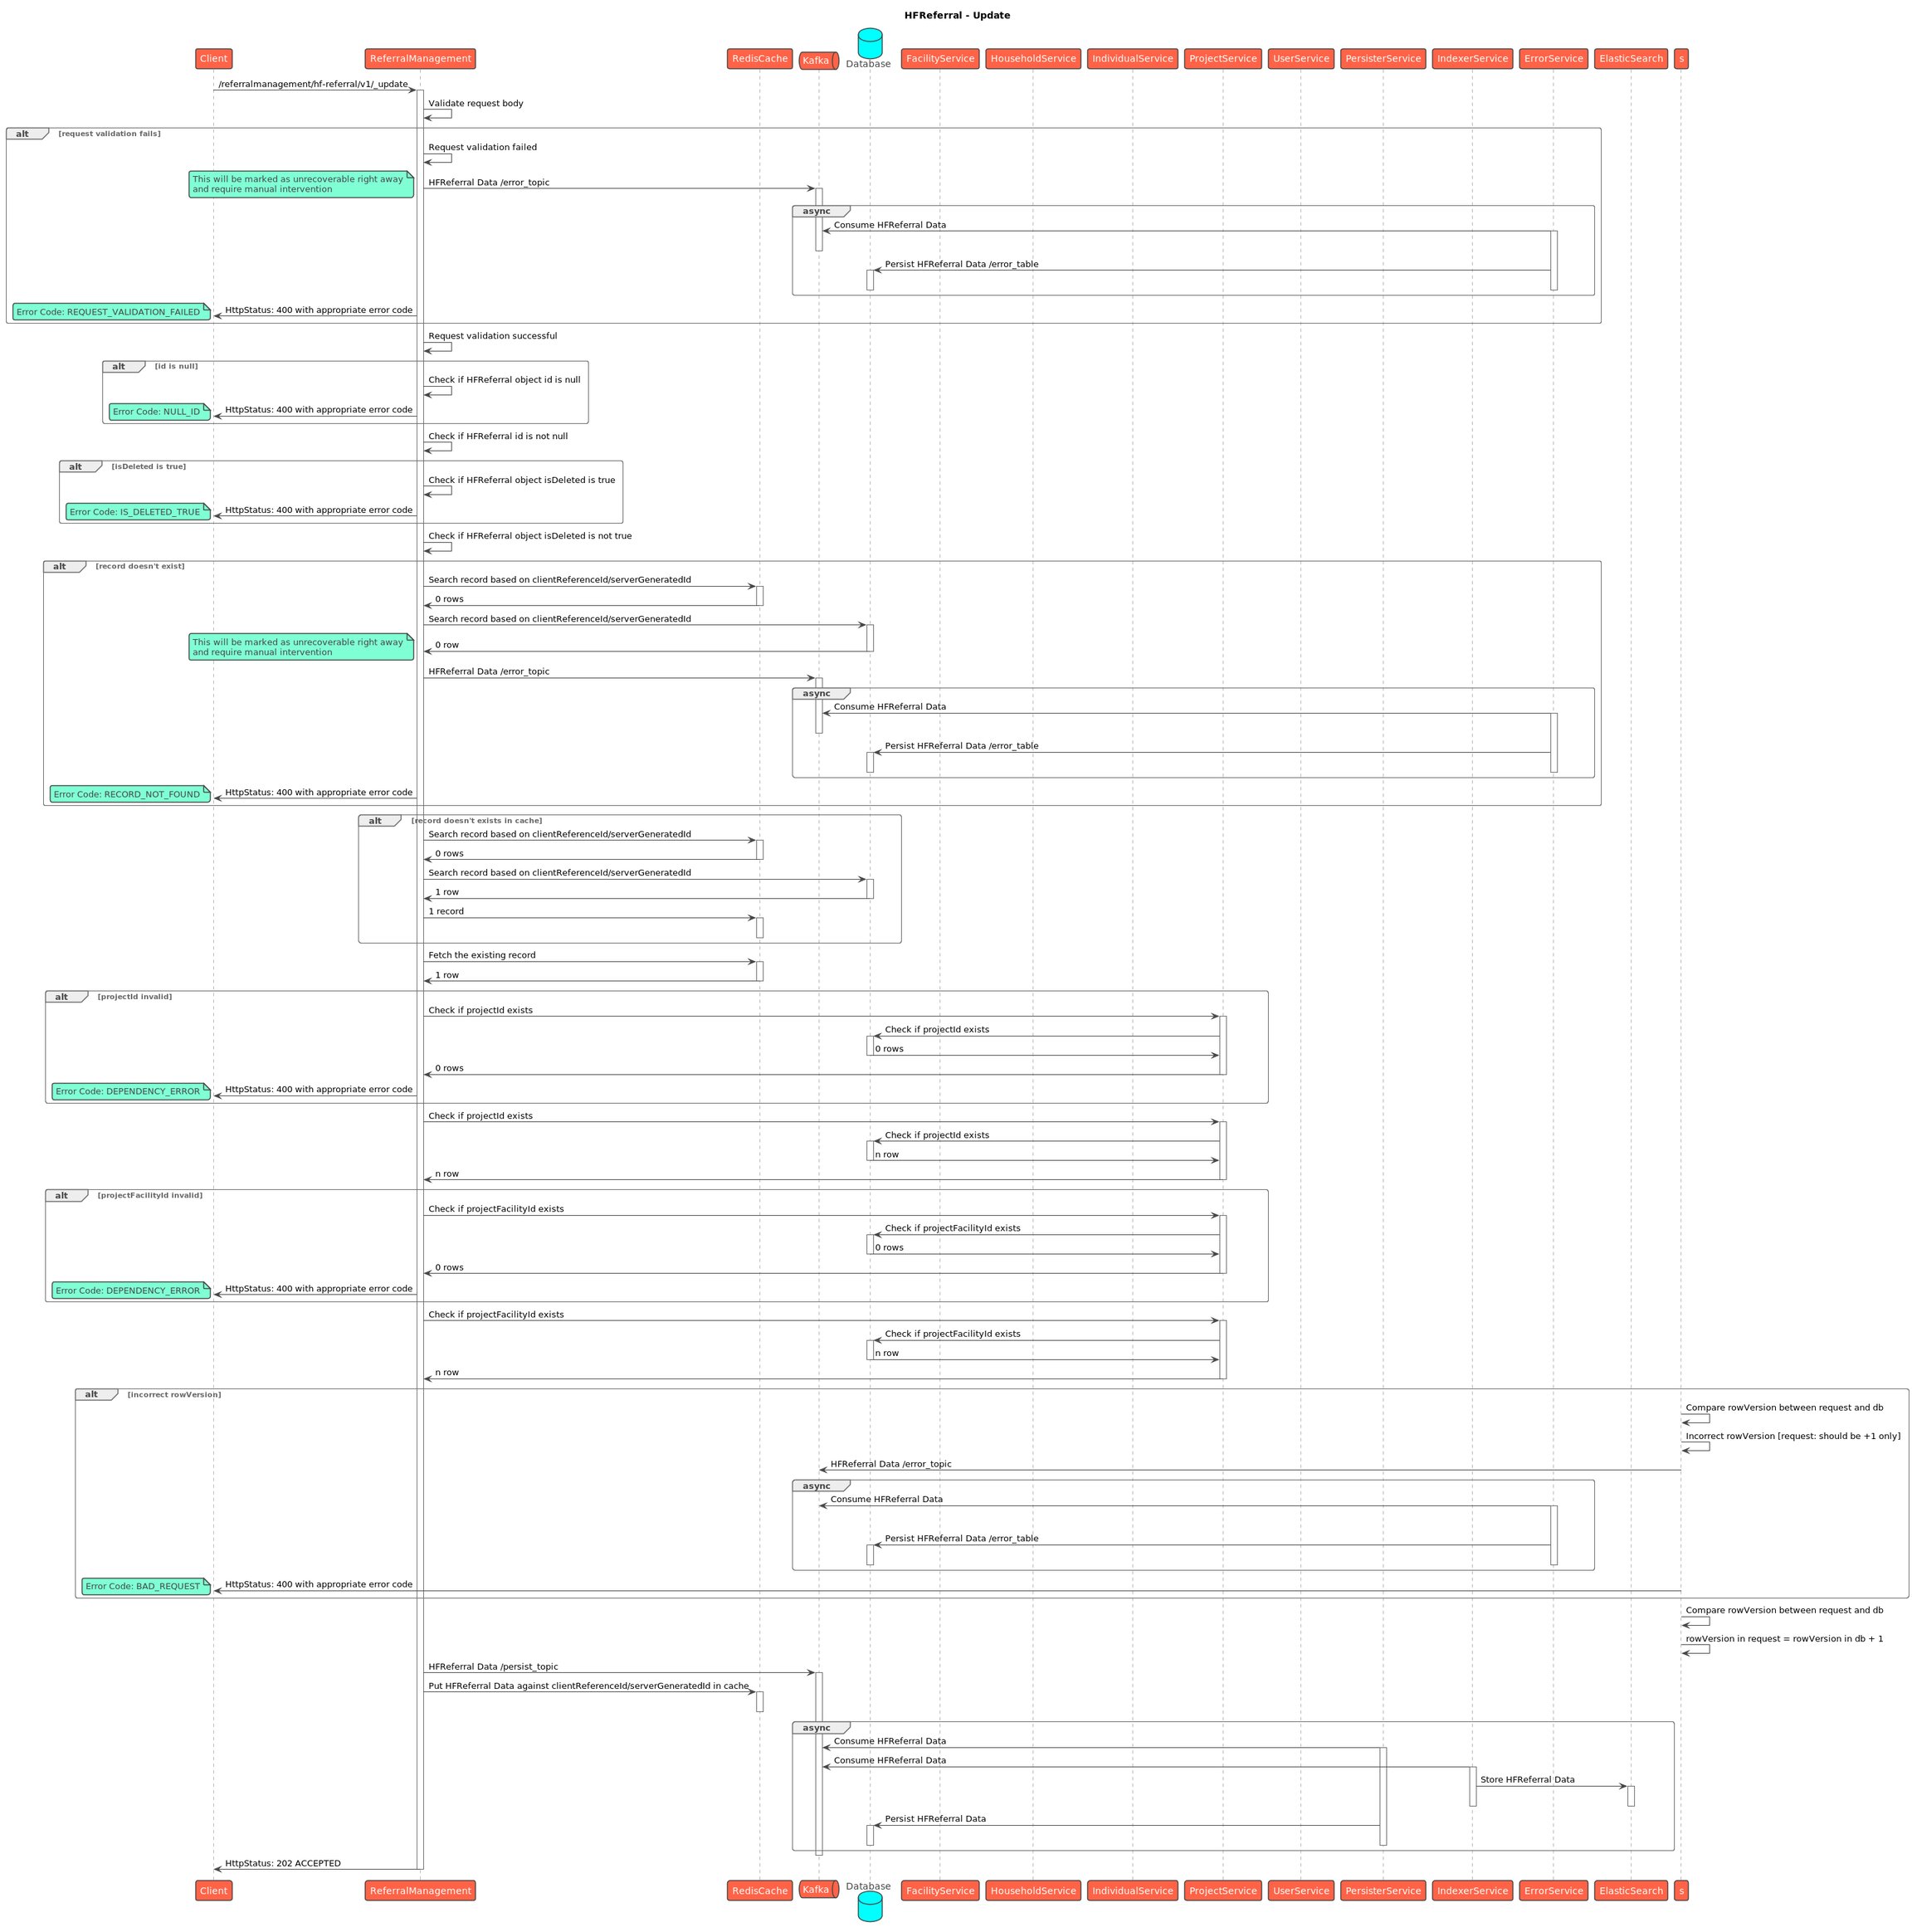
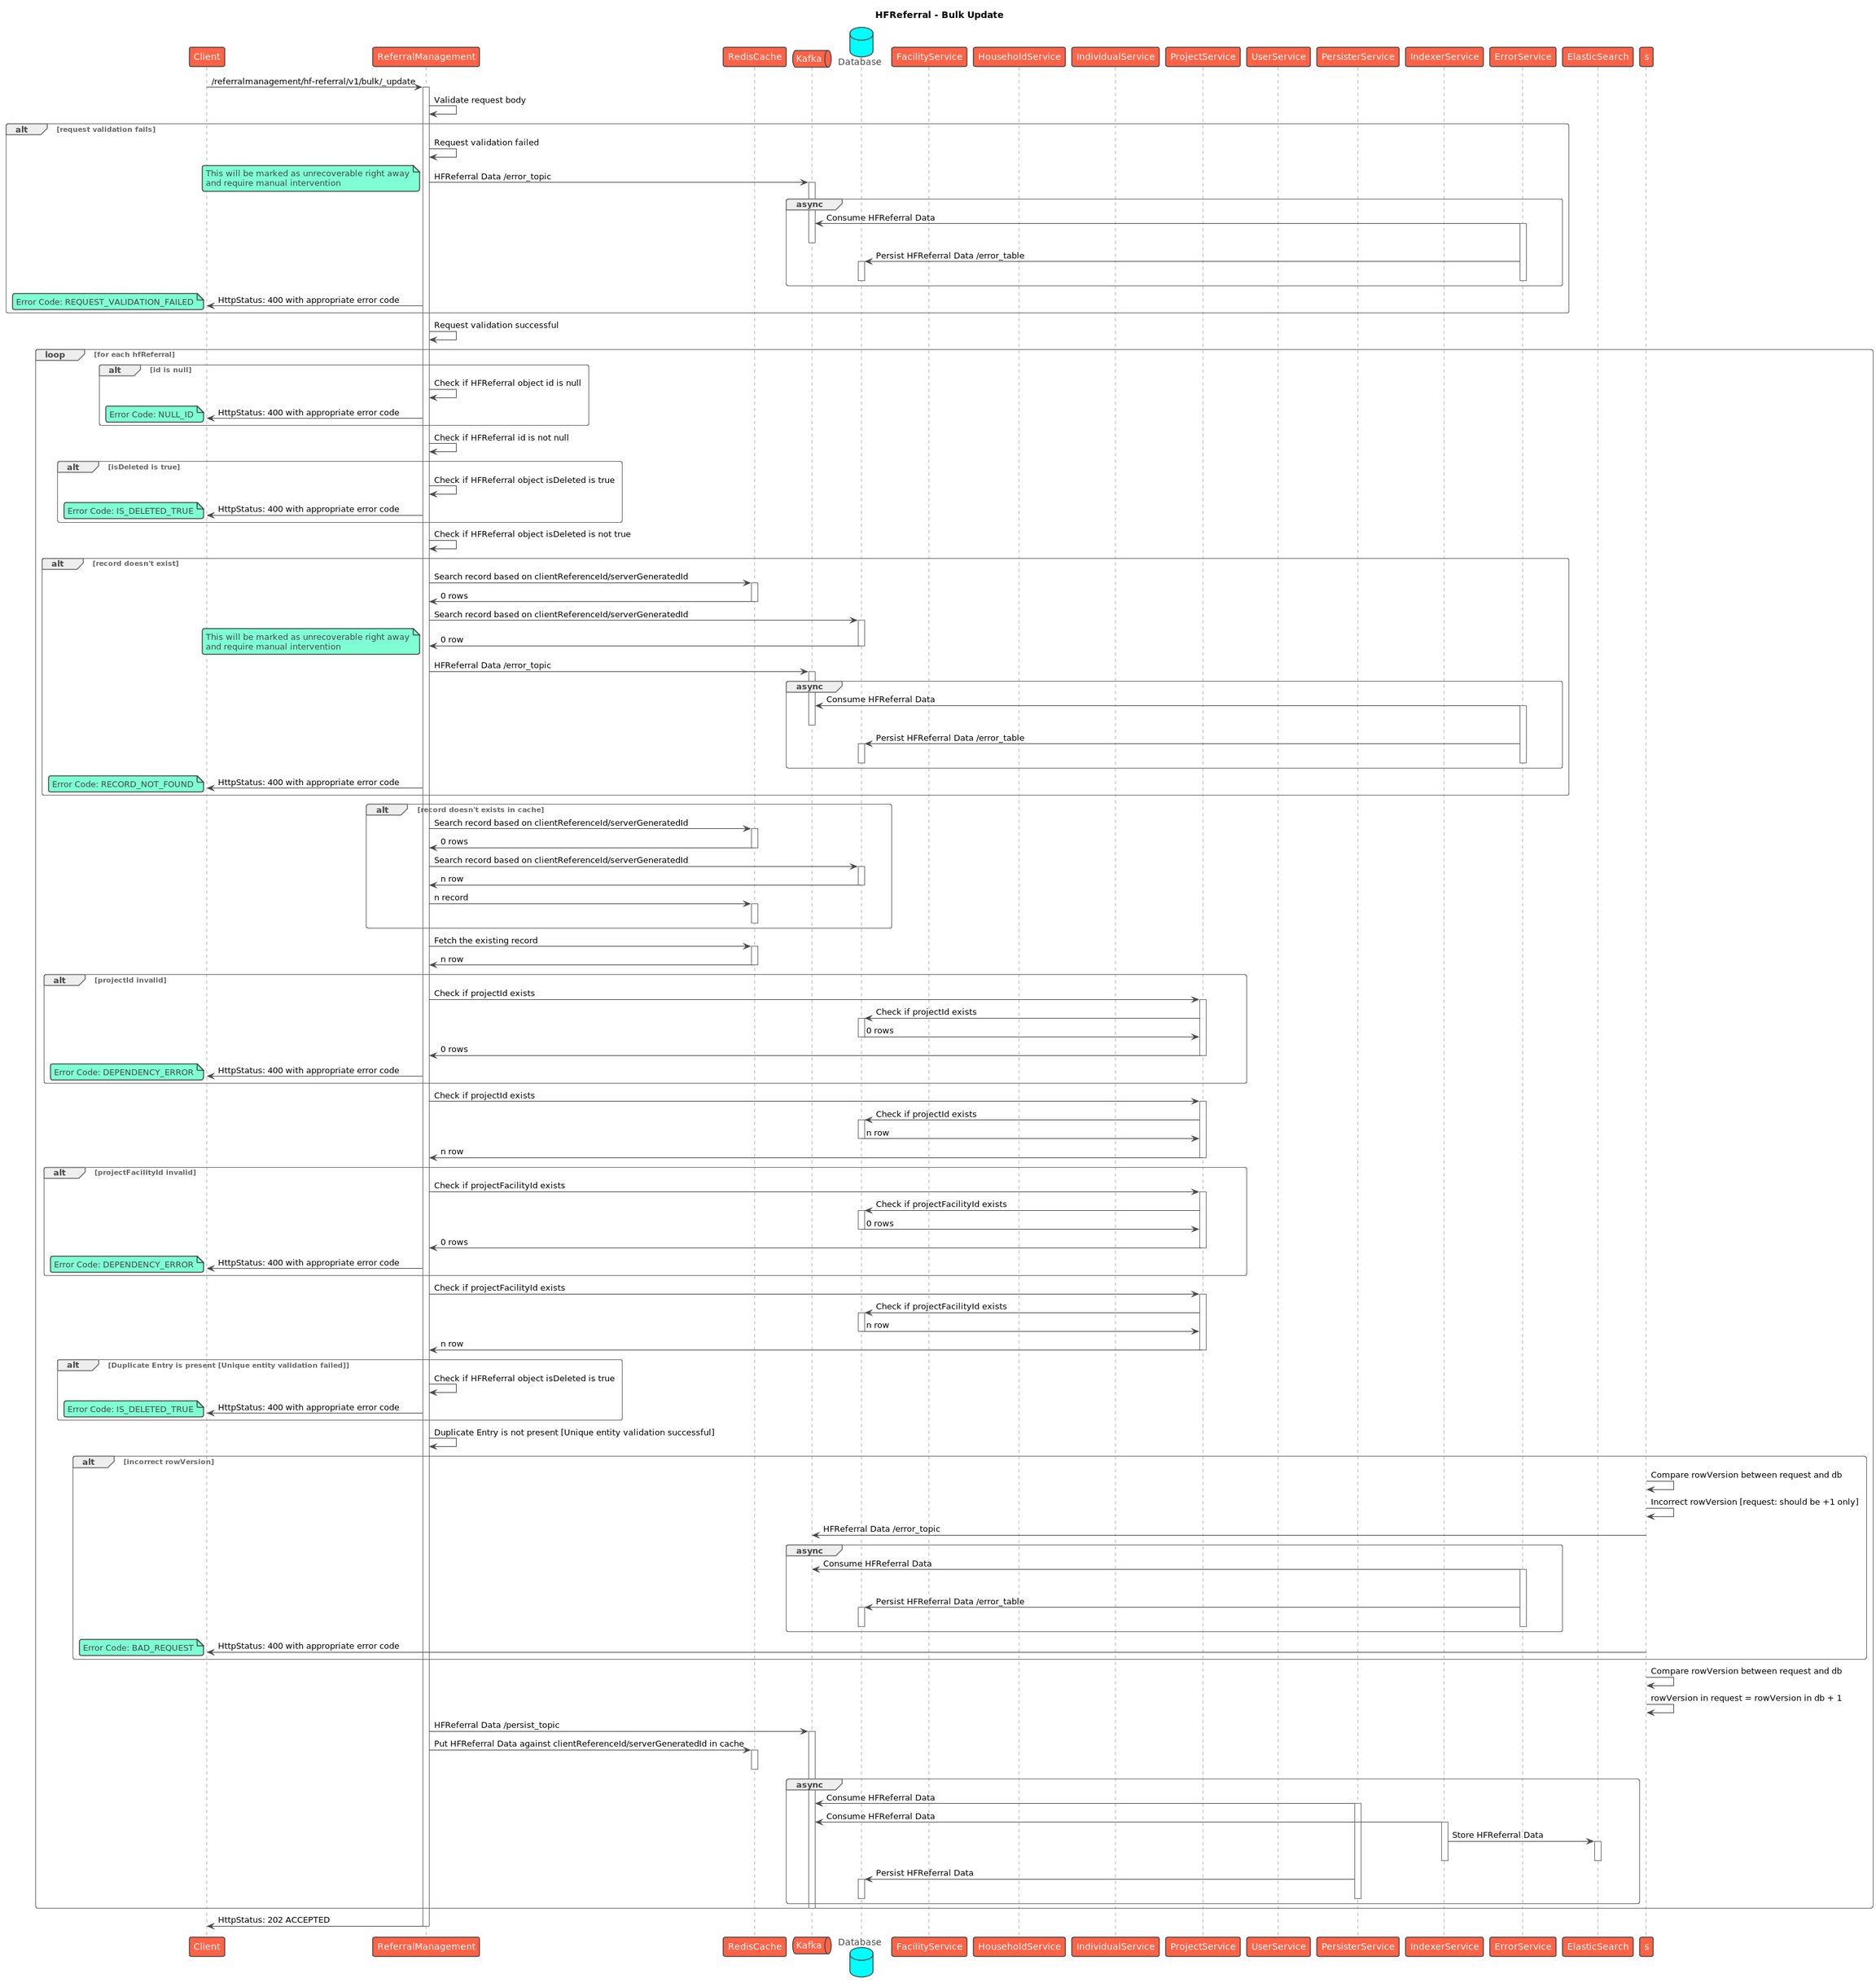
Writes are asynchronous:
The API validates and enriches the request. It then acknowledges the request.
A Kafka consumer processes the request. It emits a
save-*,update-*, ordelete-*event.egov-persister writes that event to Postgres. The transformer/indexer projects it to Elasticsearch for dashboards.
Search reads from Postgres. Downsync is a synchronous bulk read. It calls dependent services to build the device bundle.
Sequence Diagrams
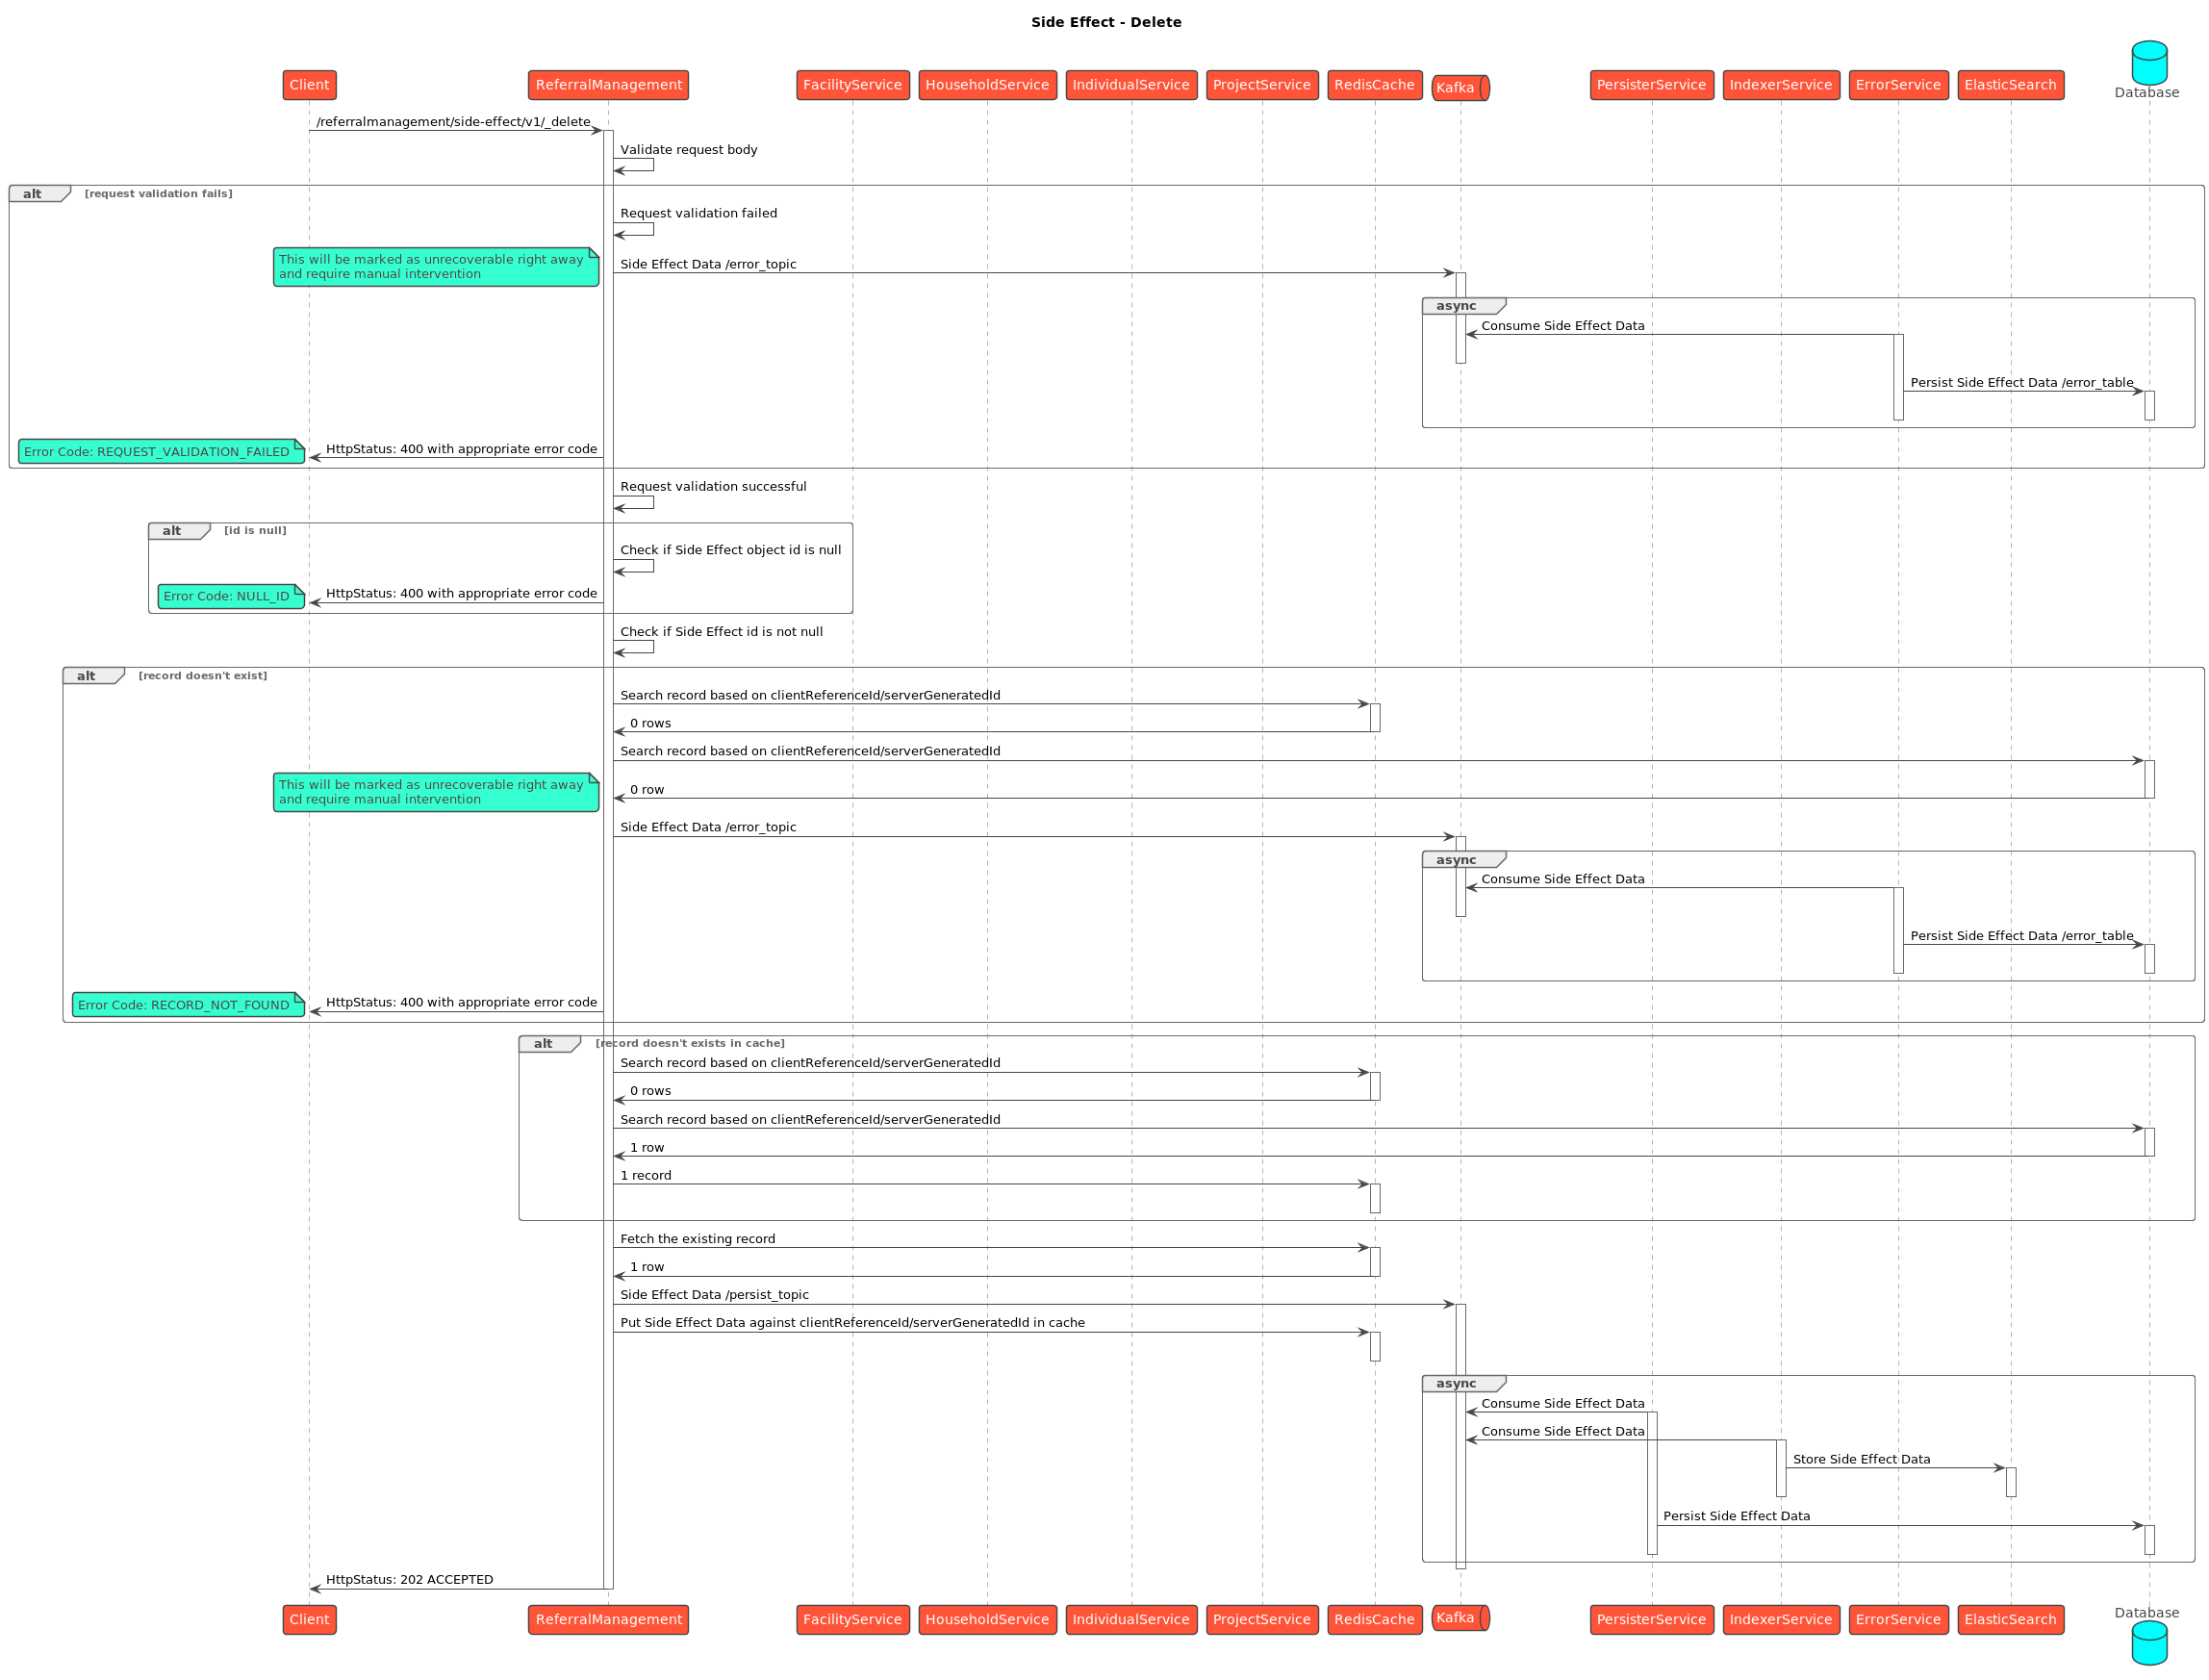
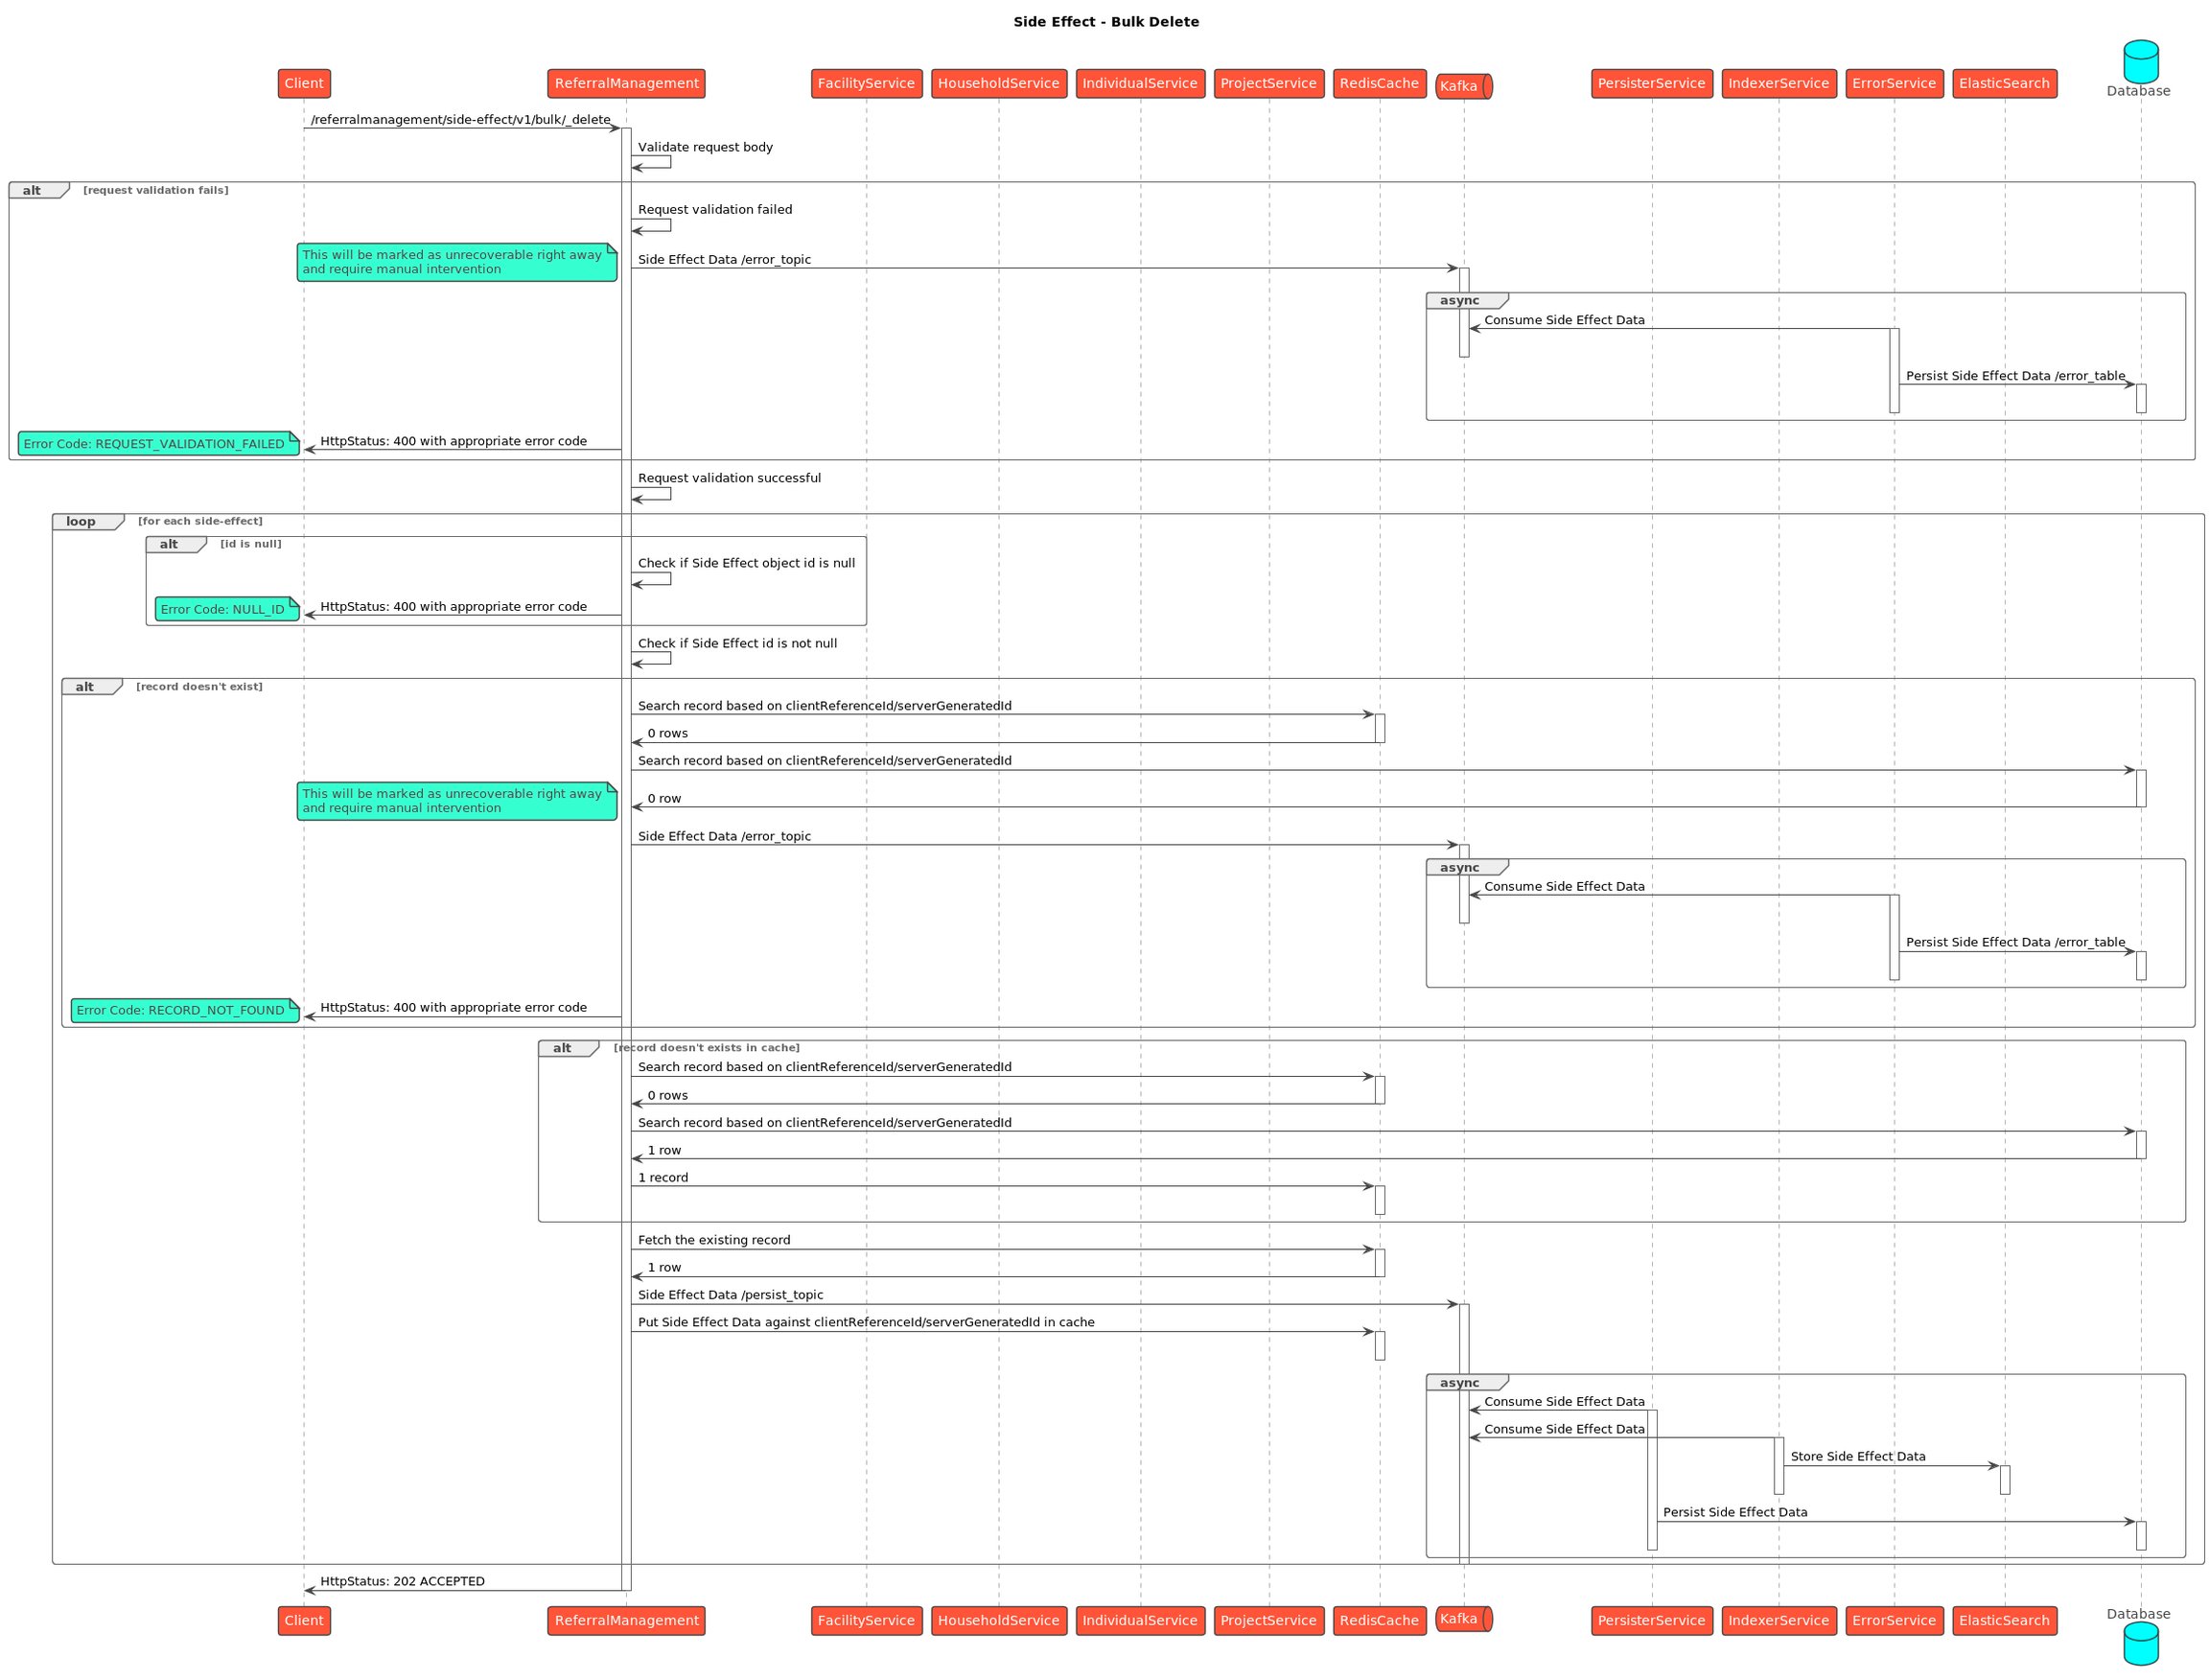
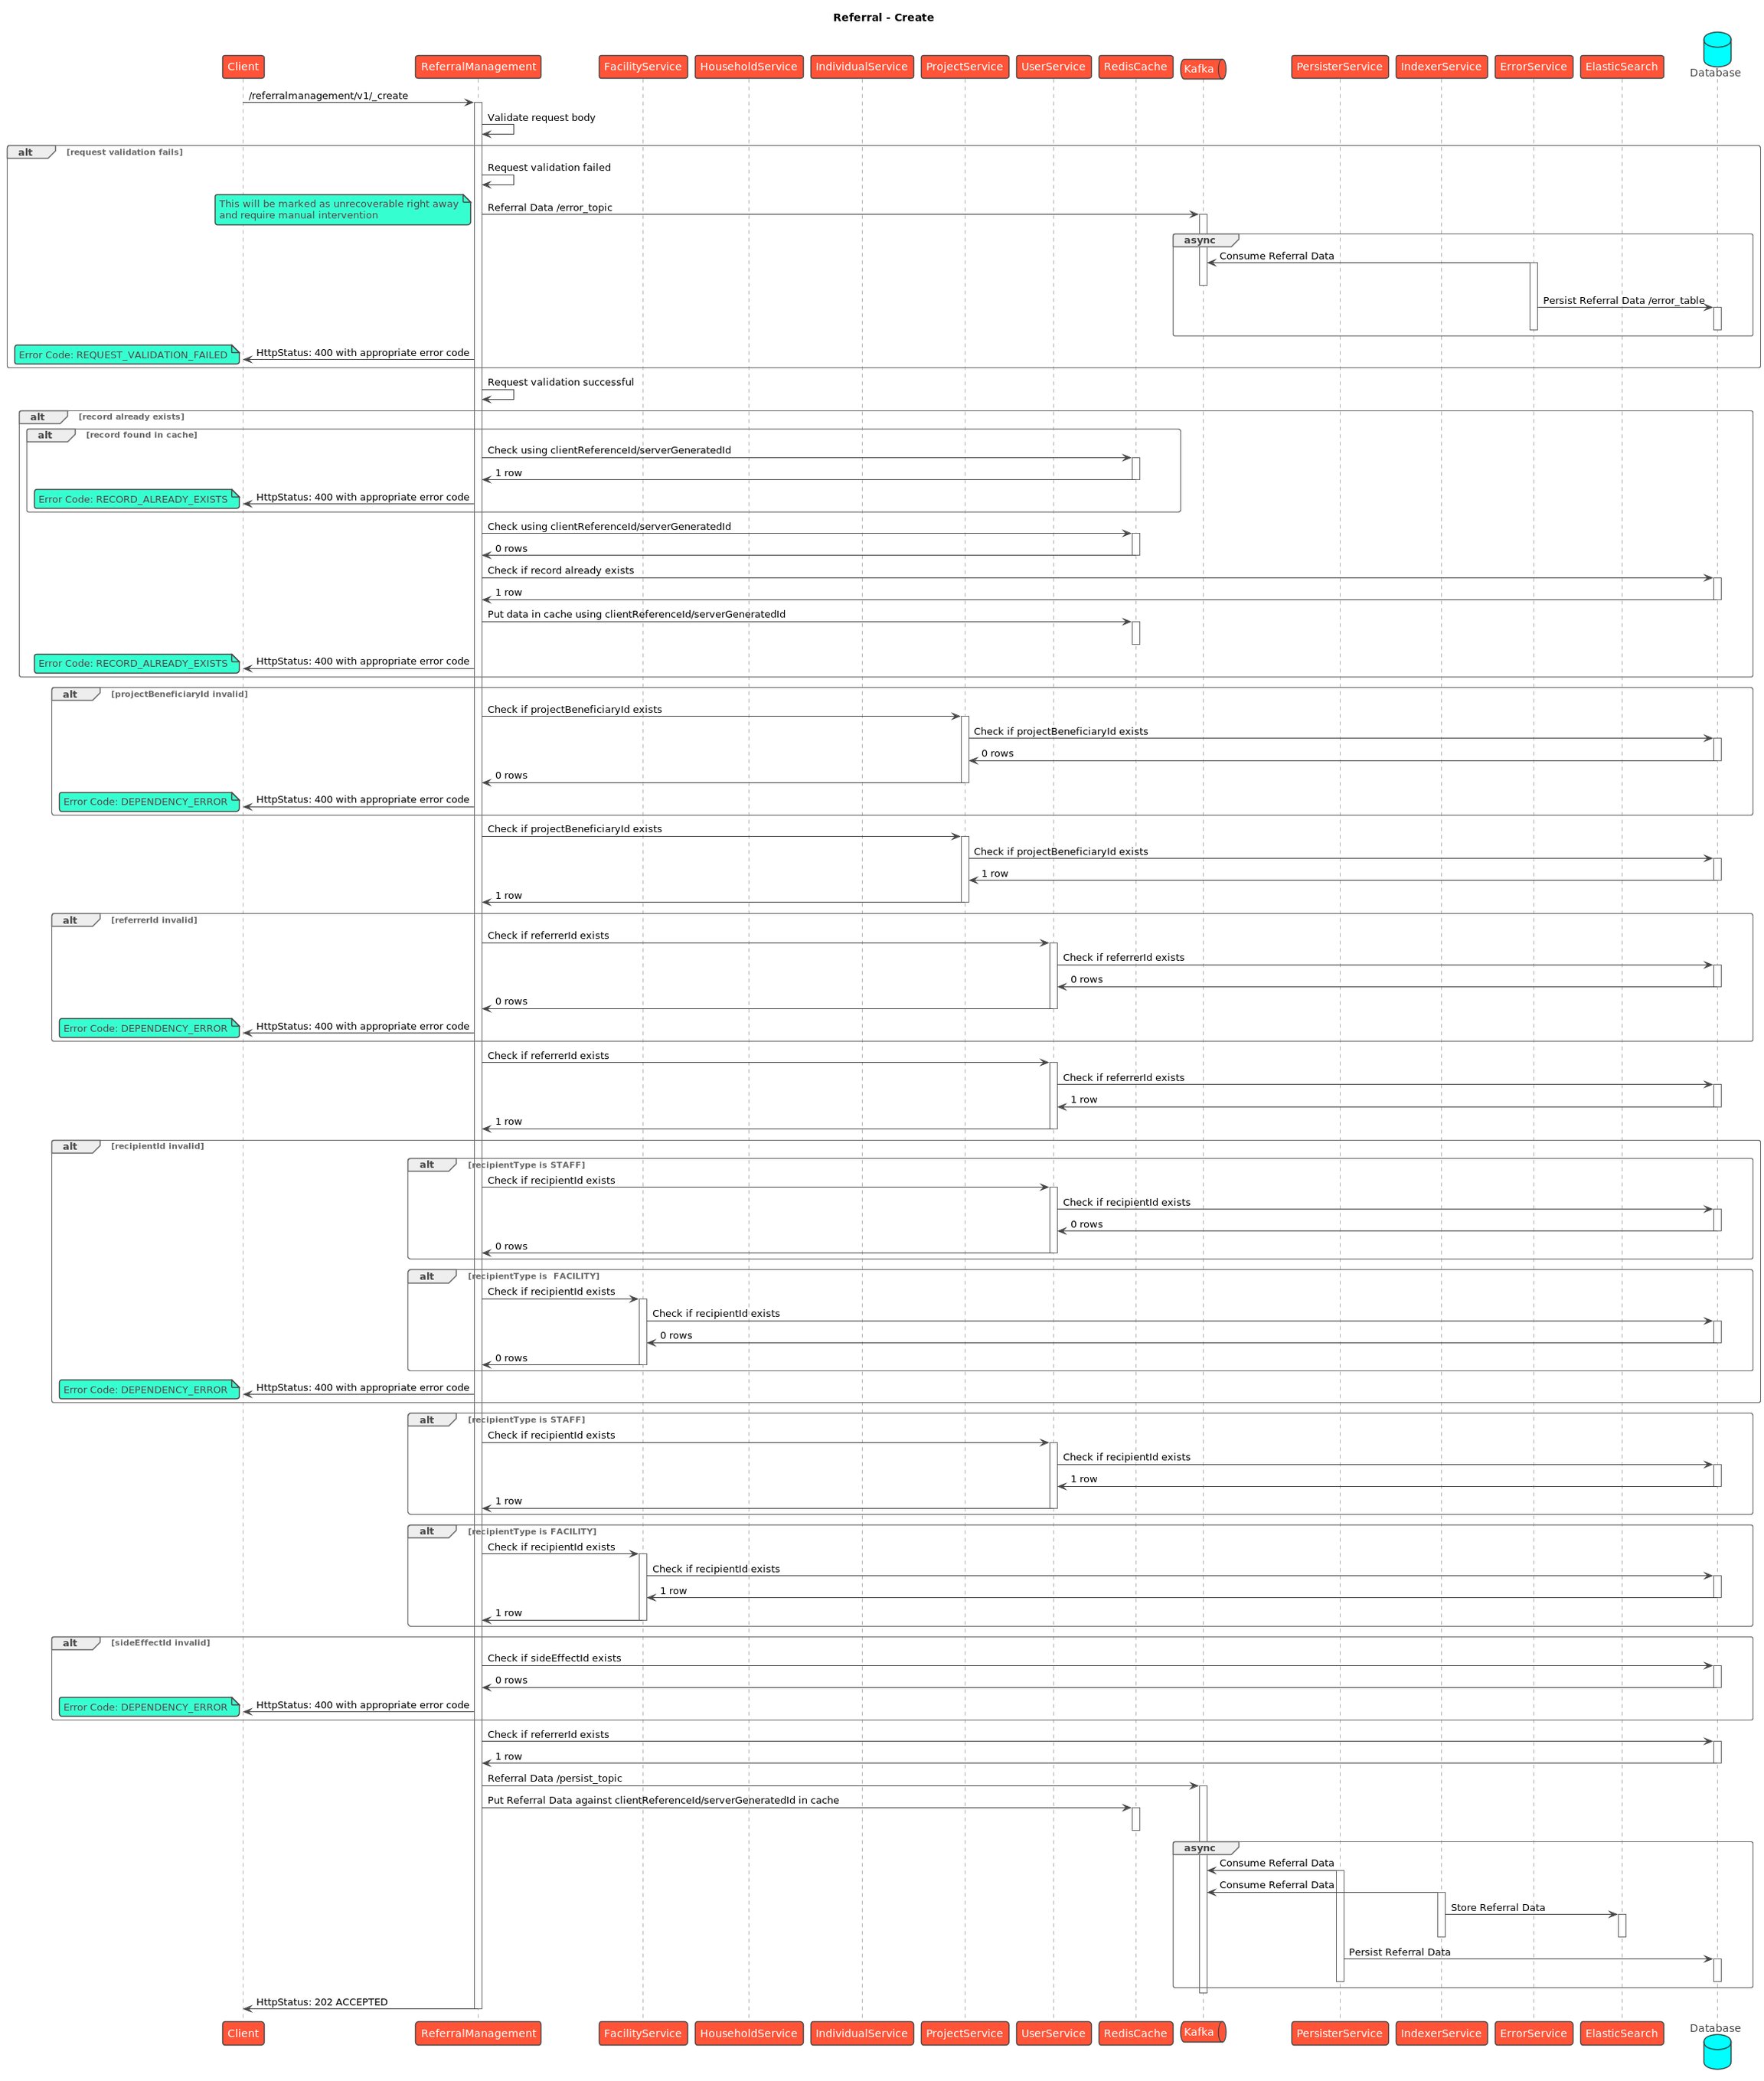
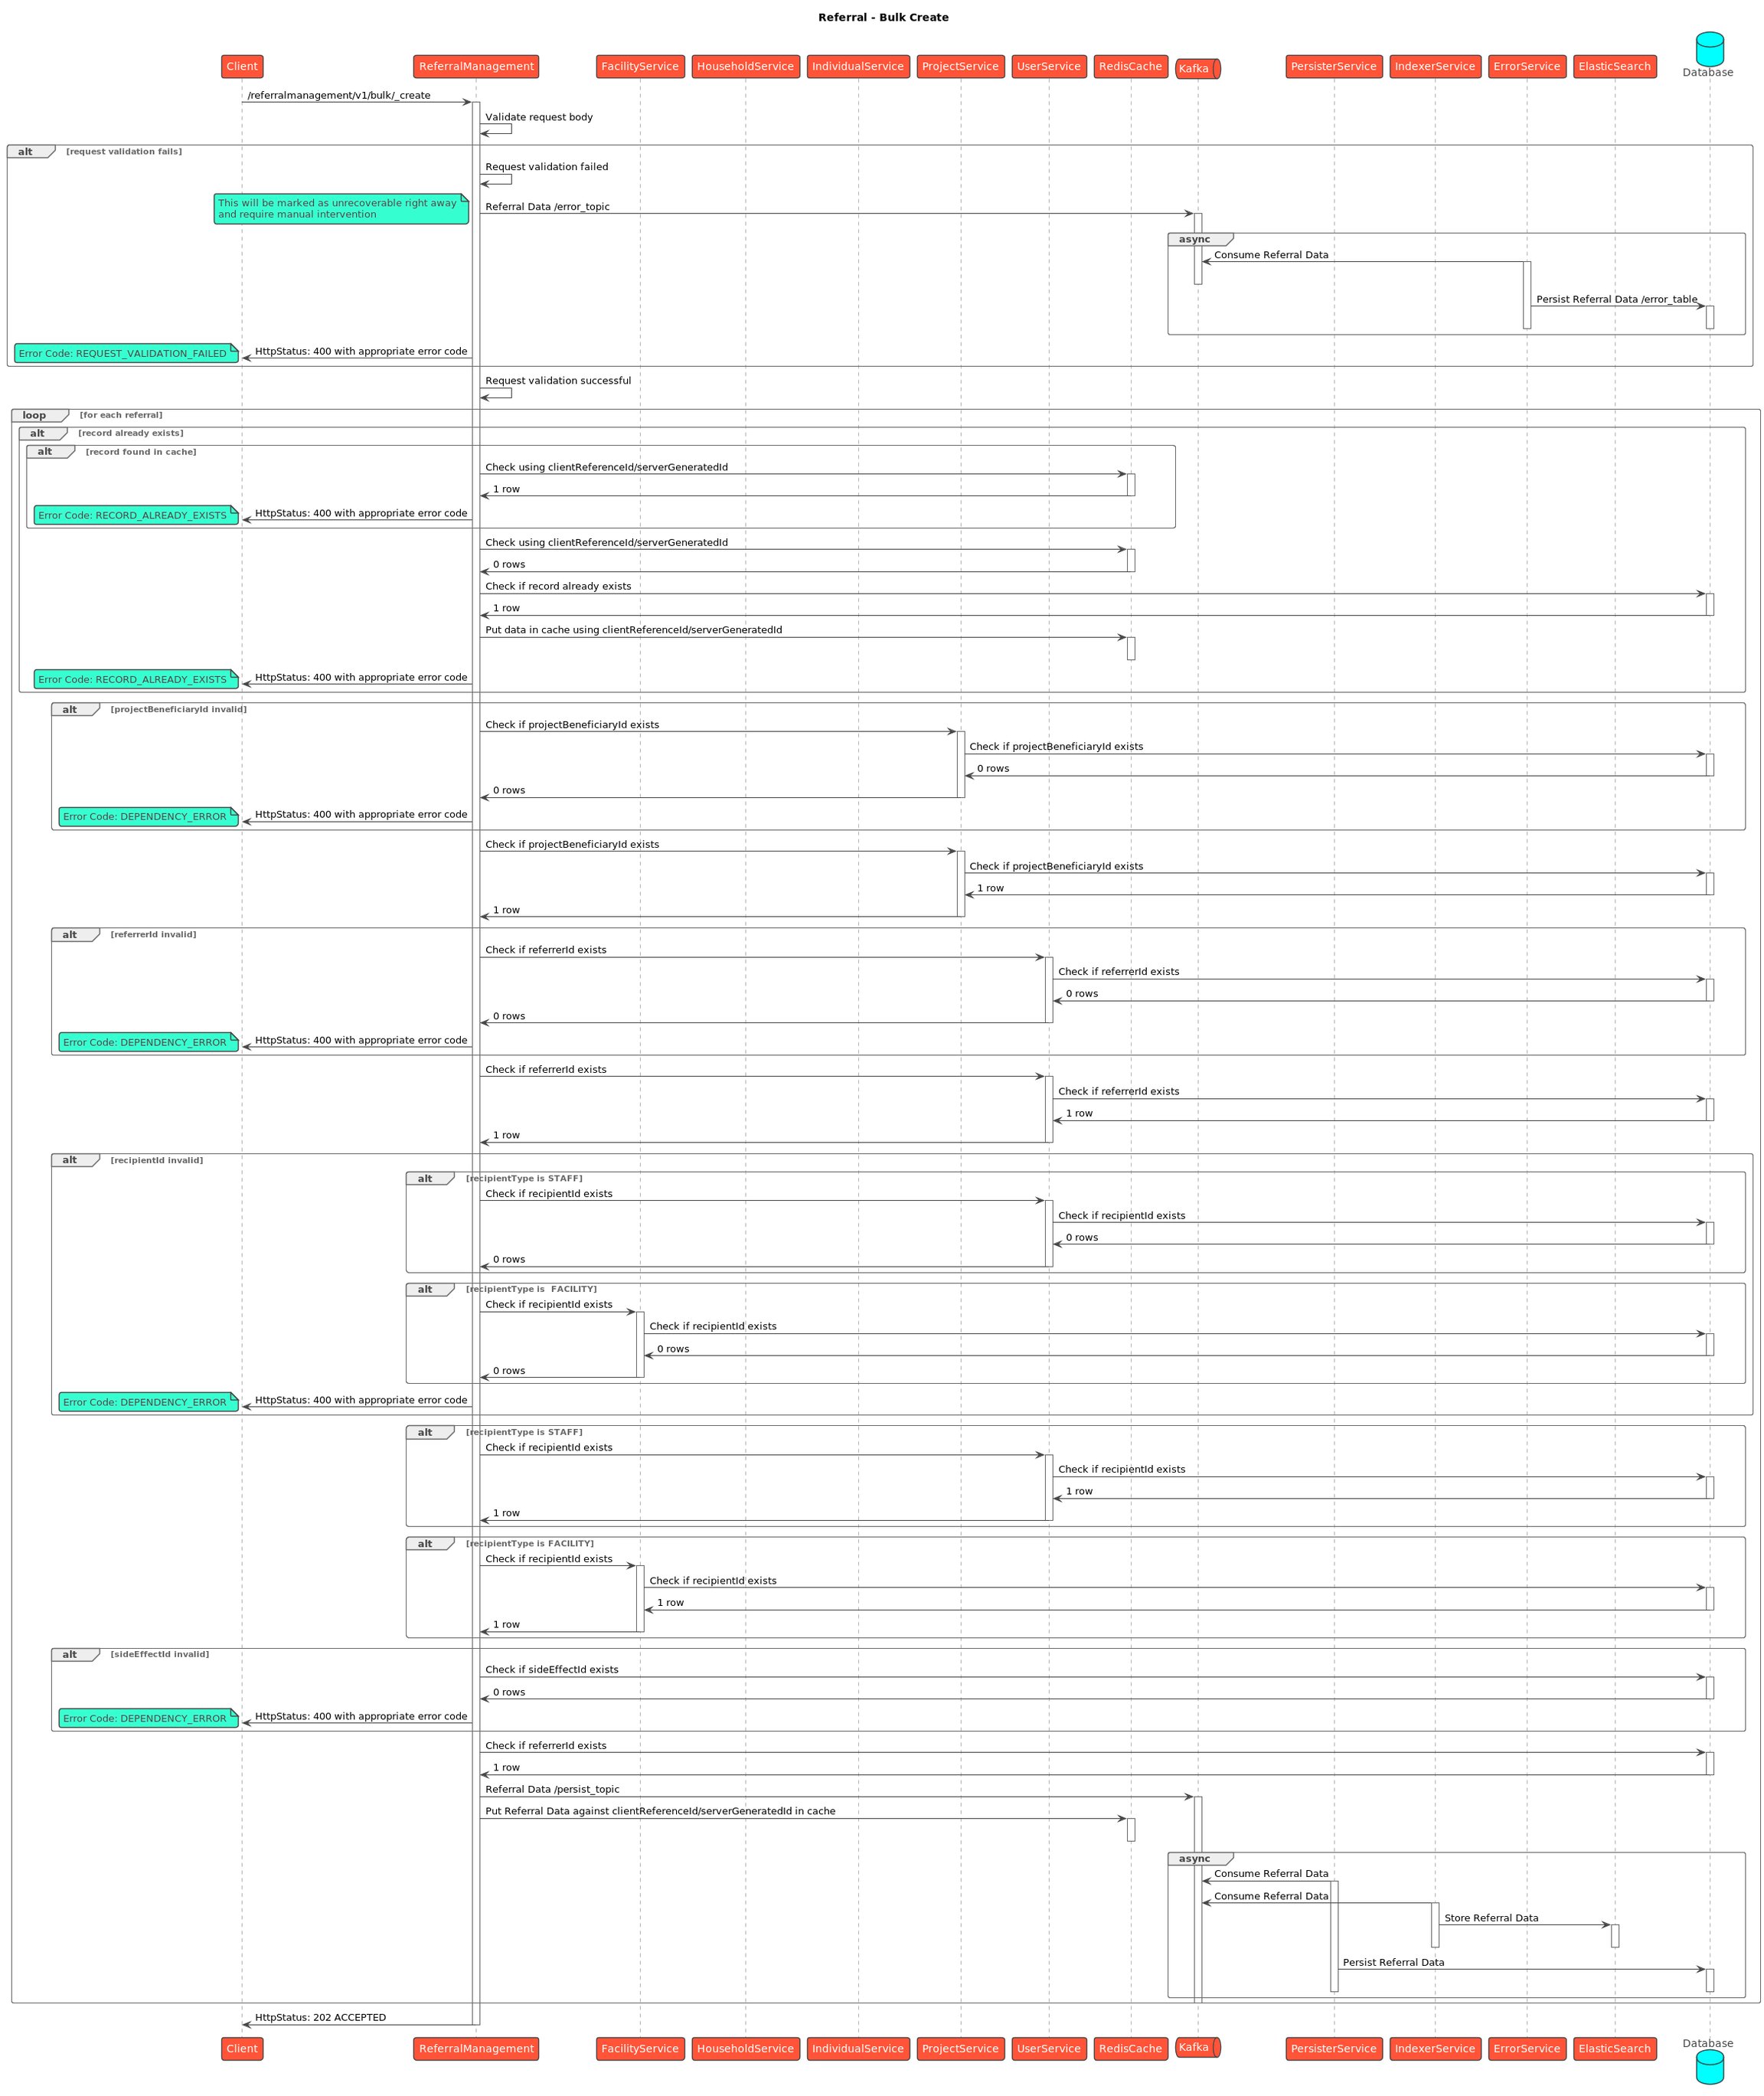
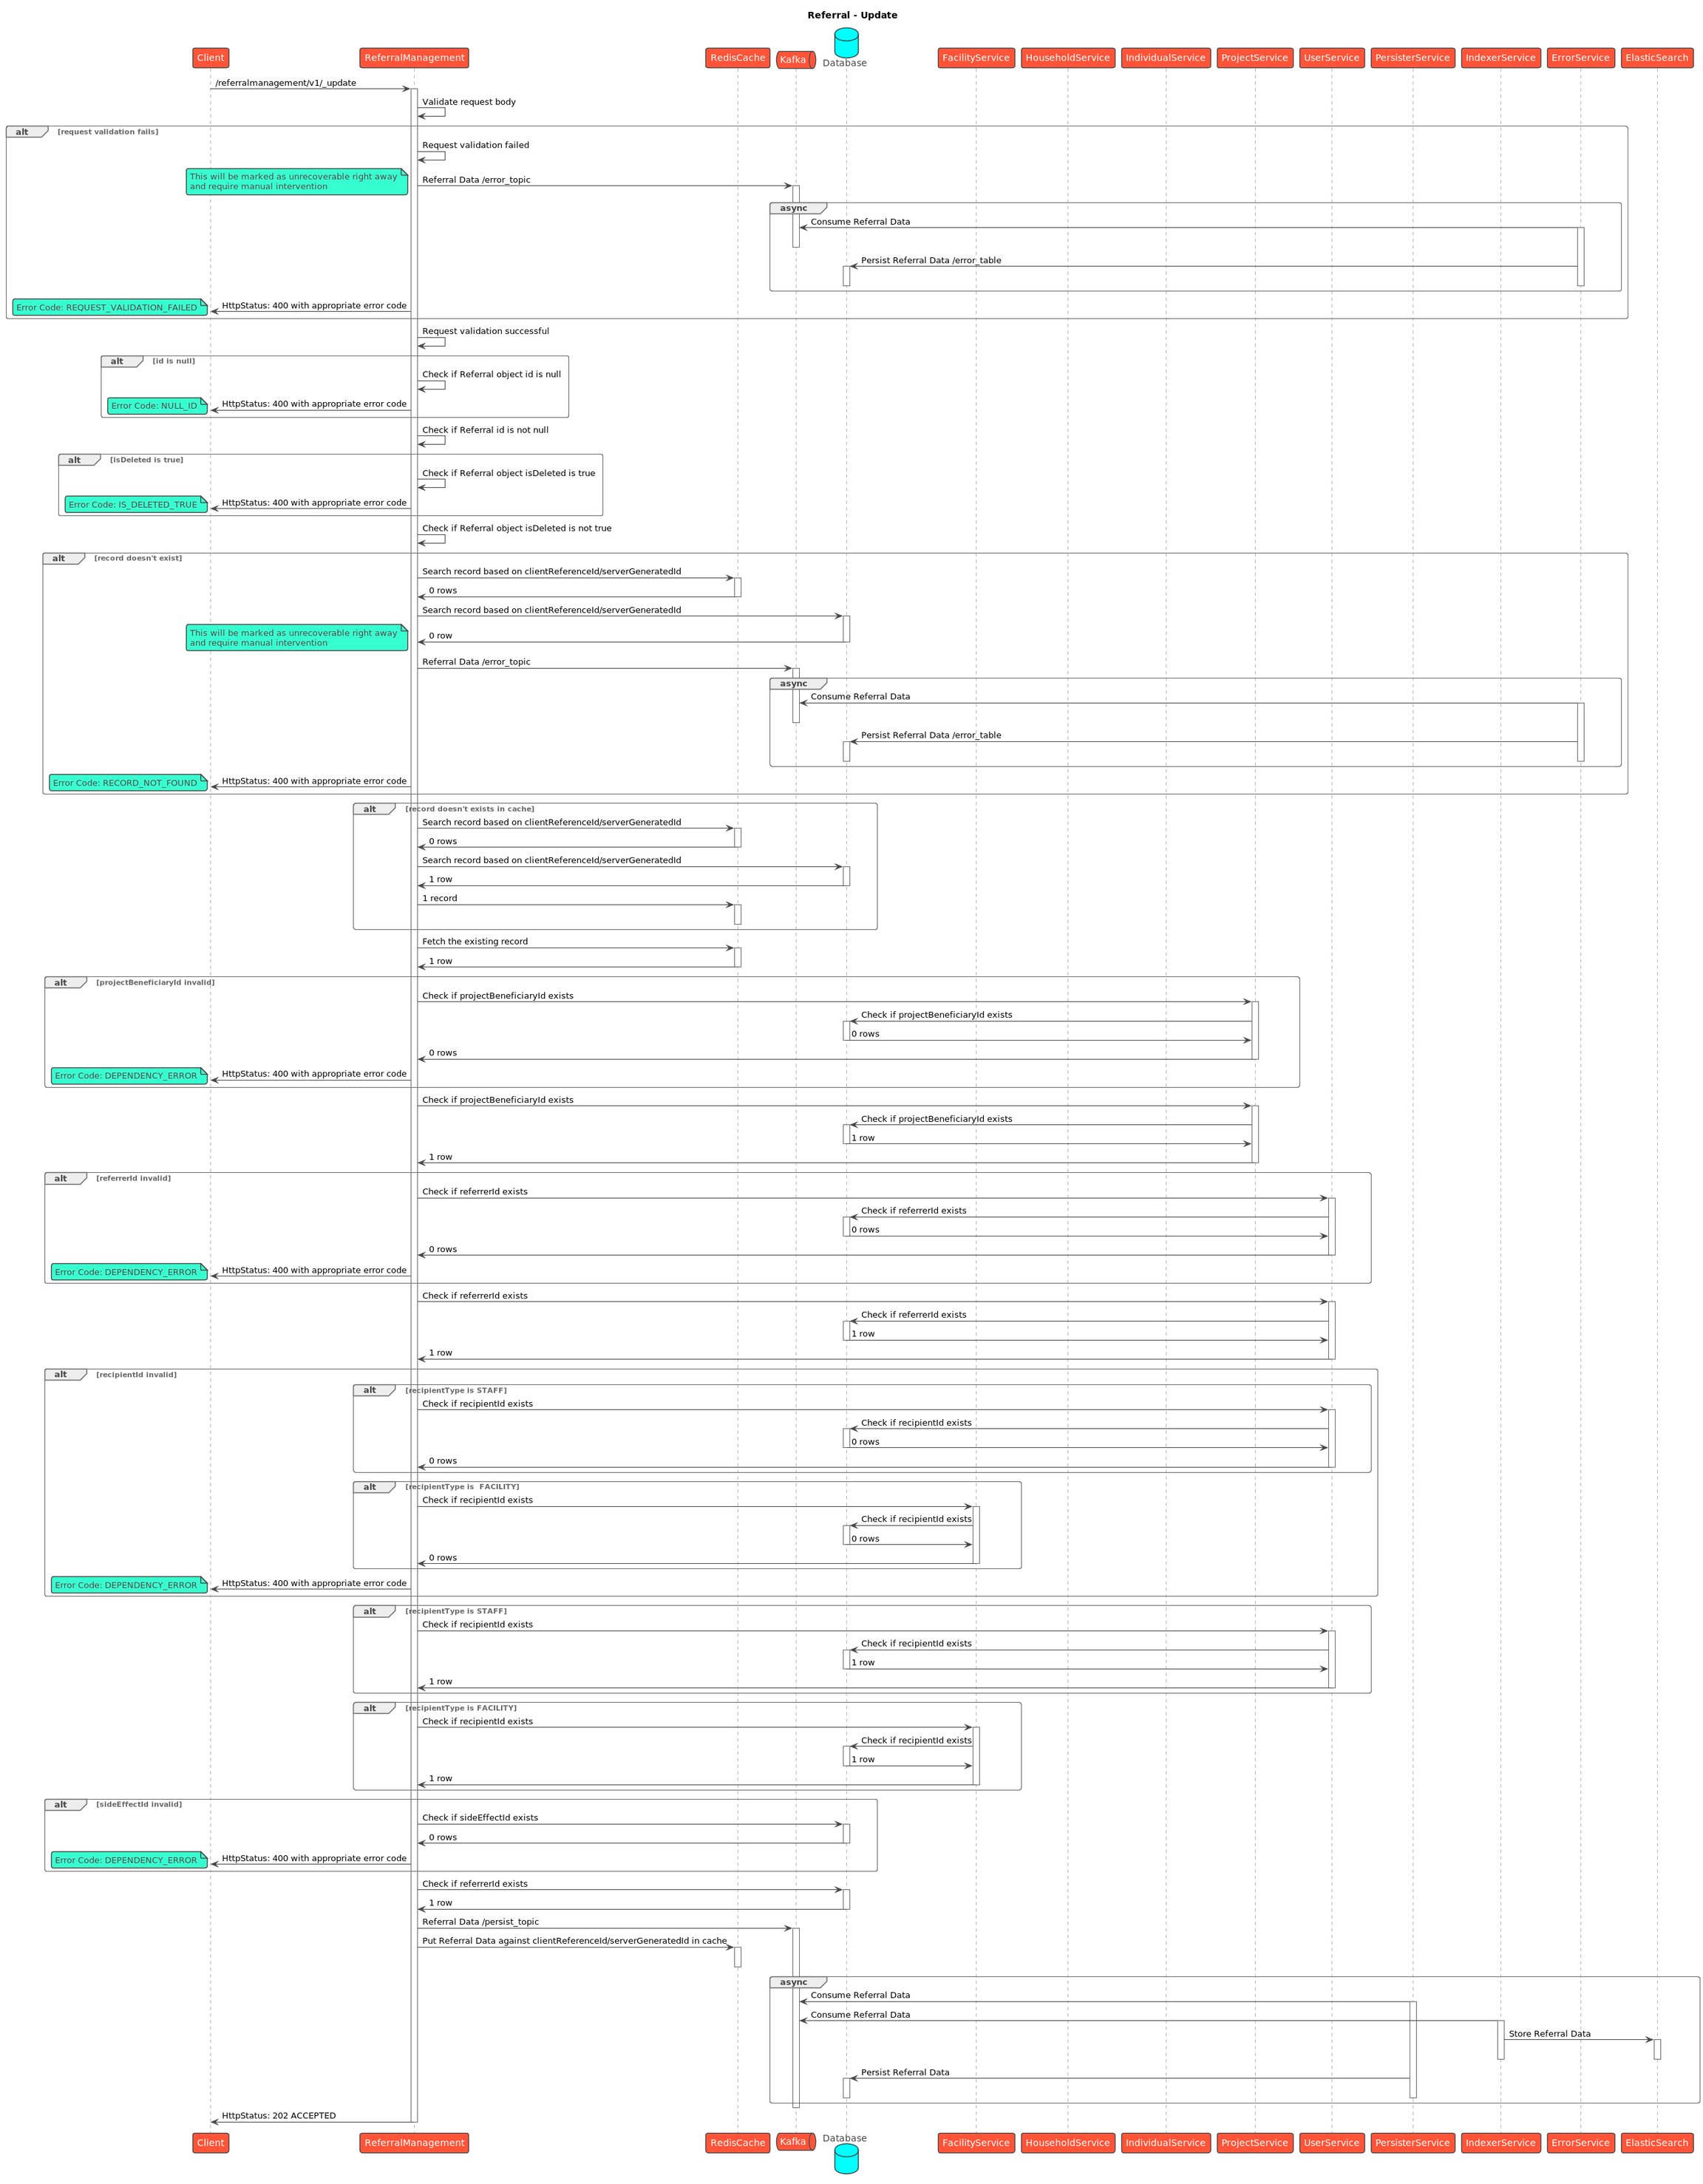
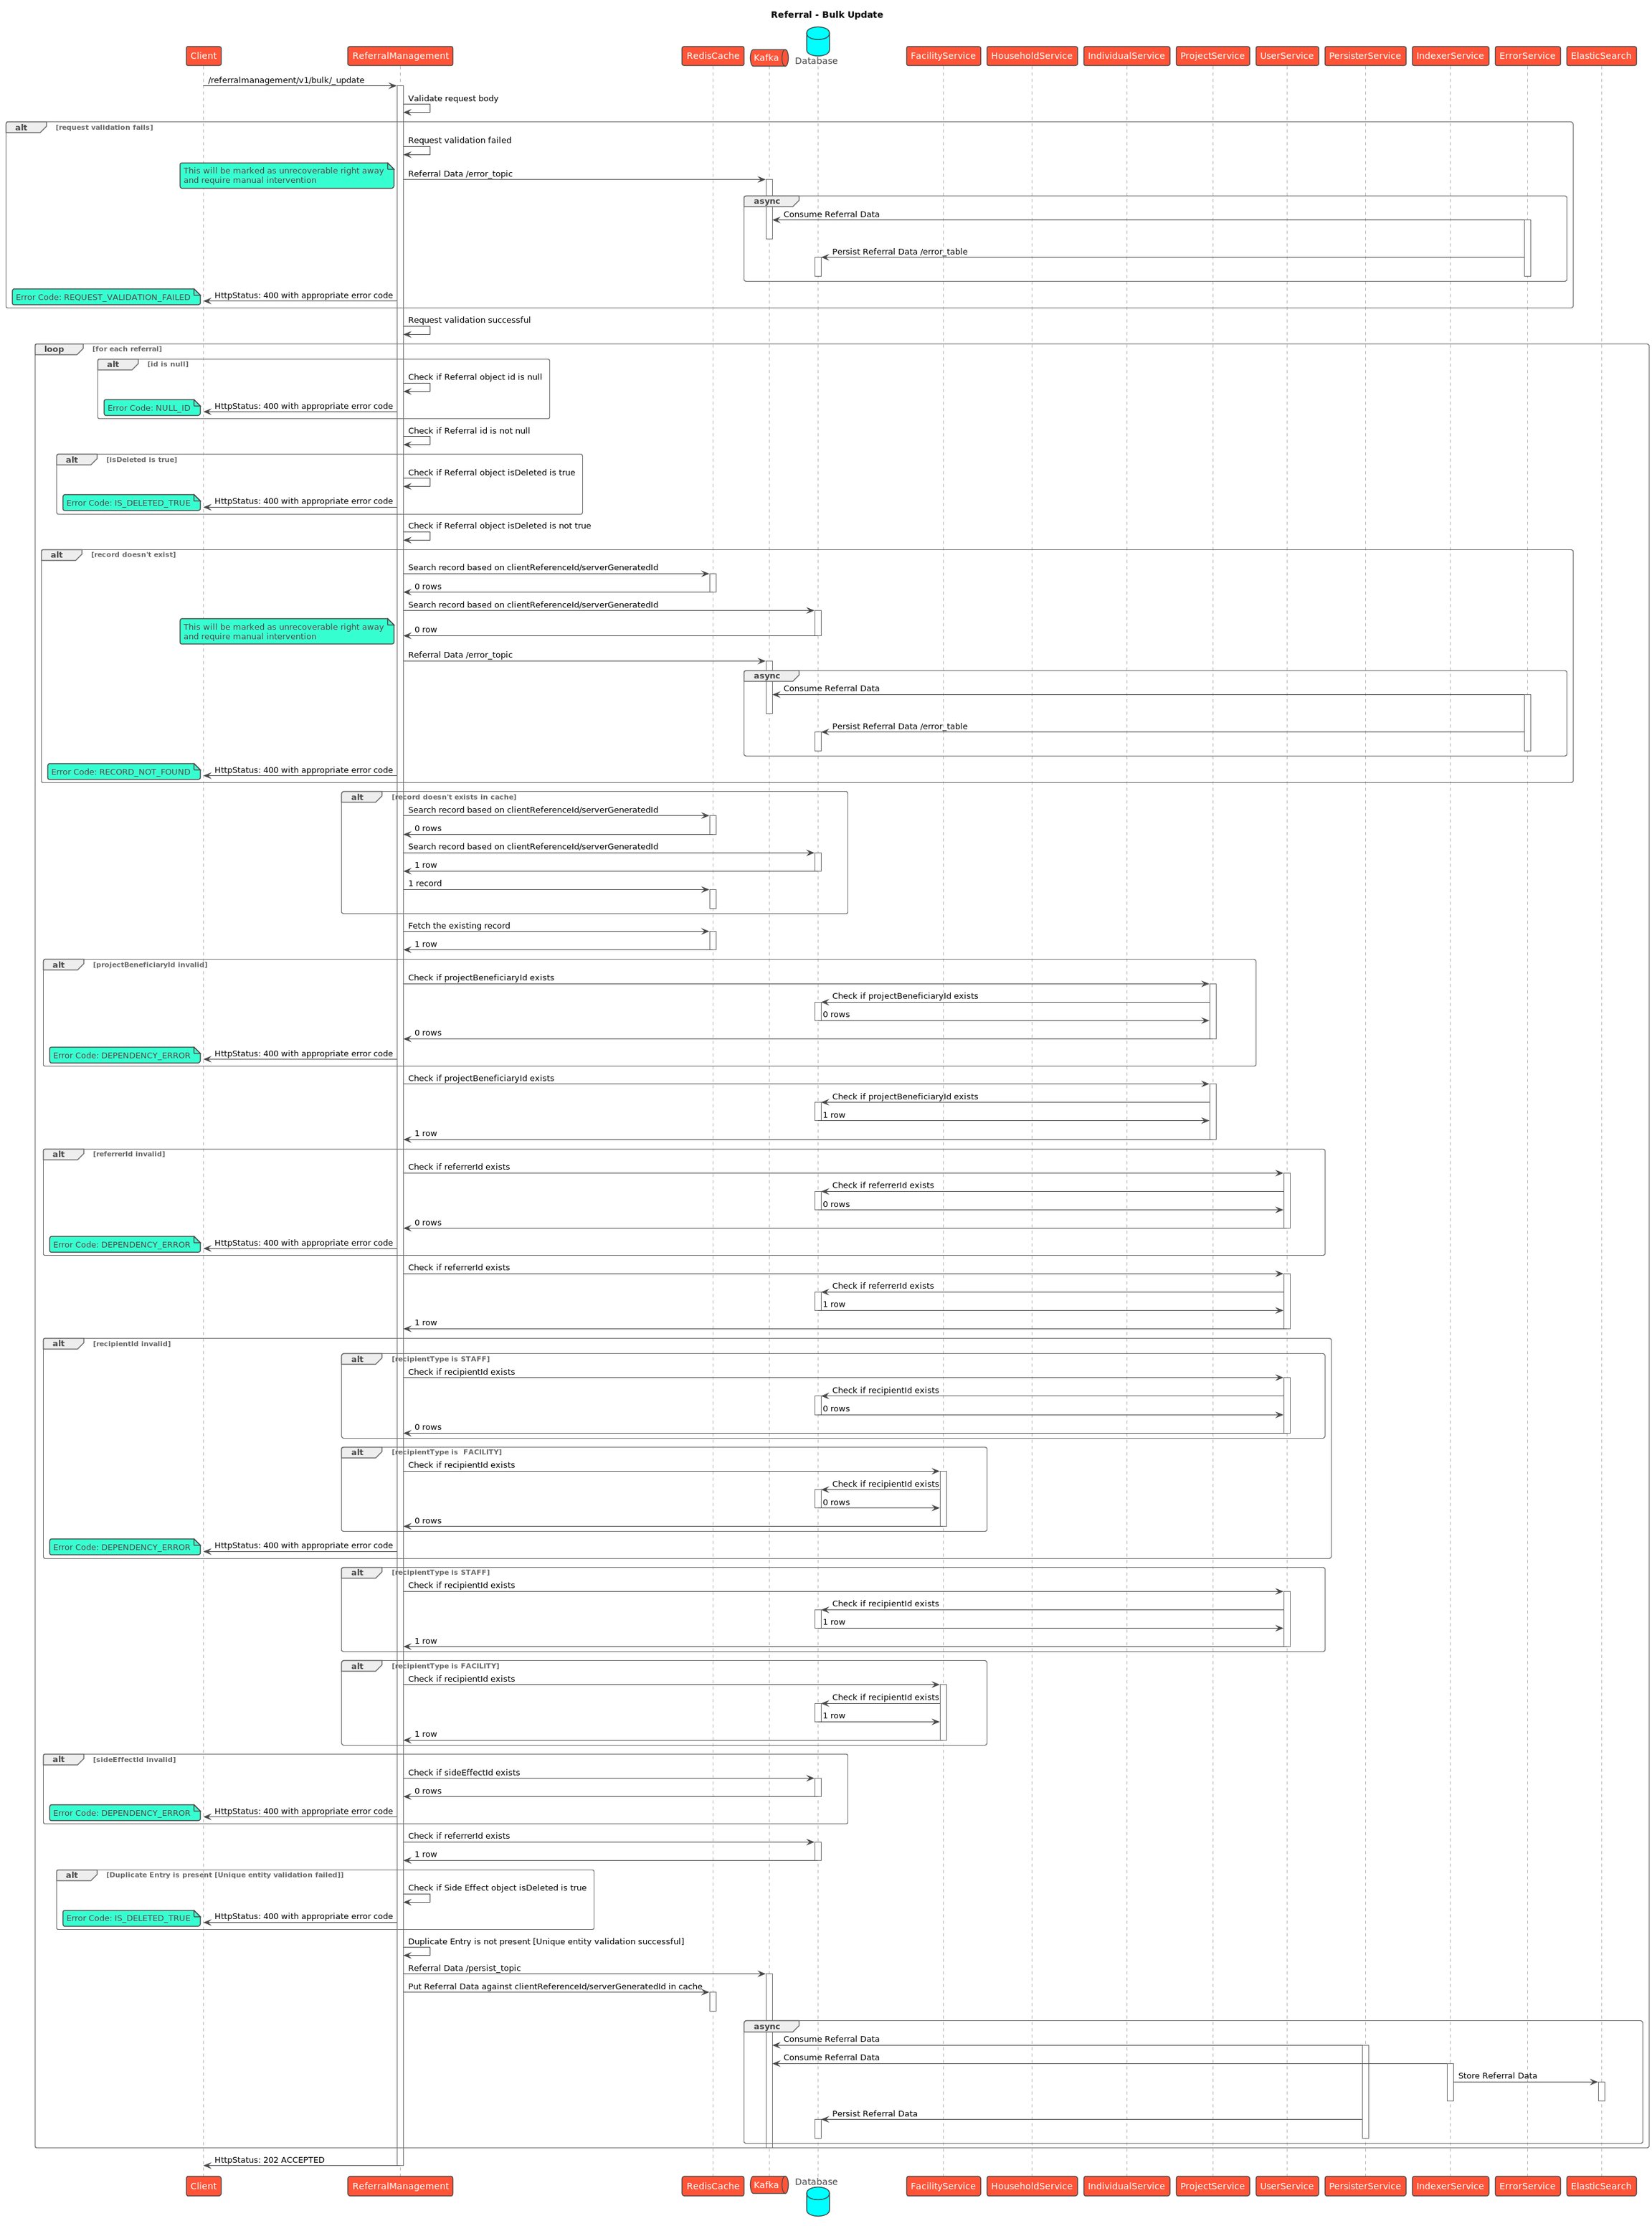
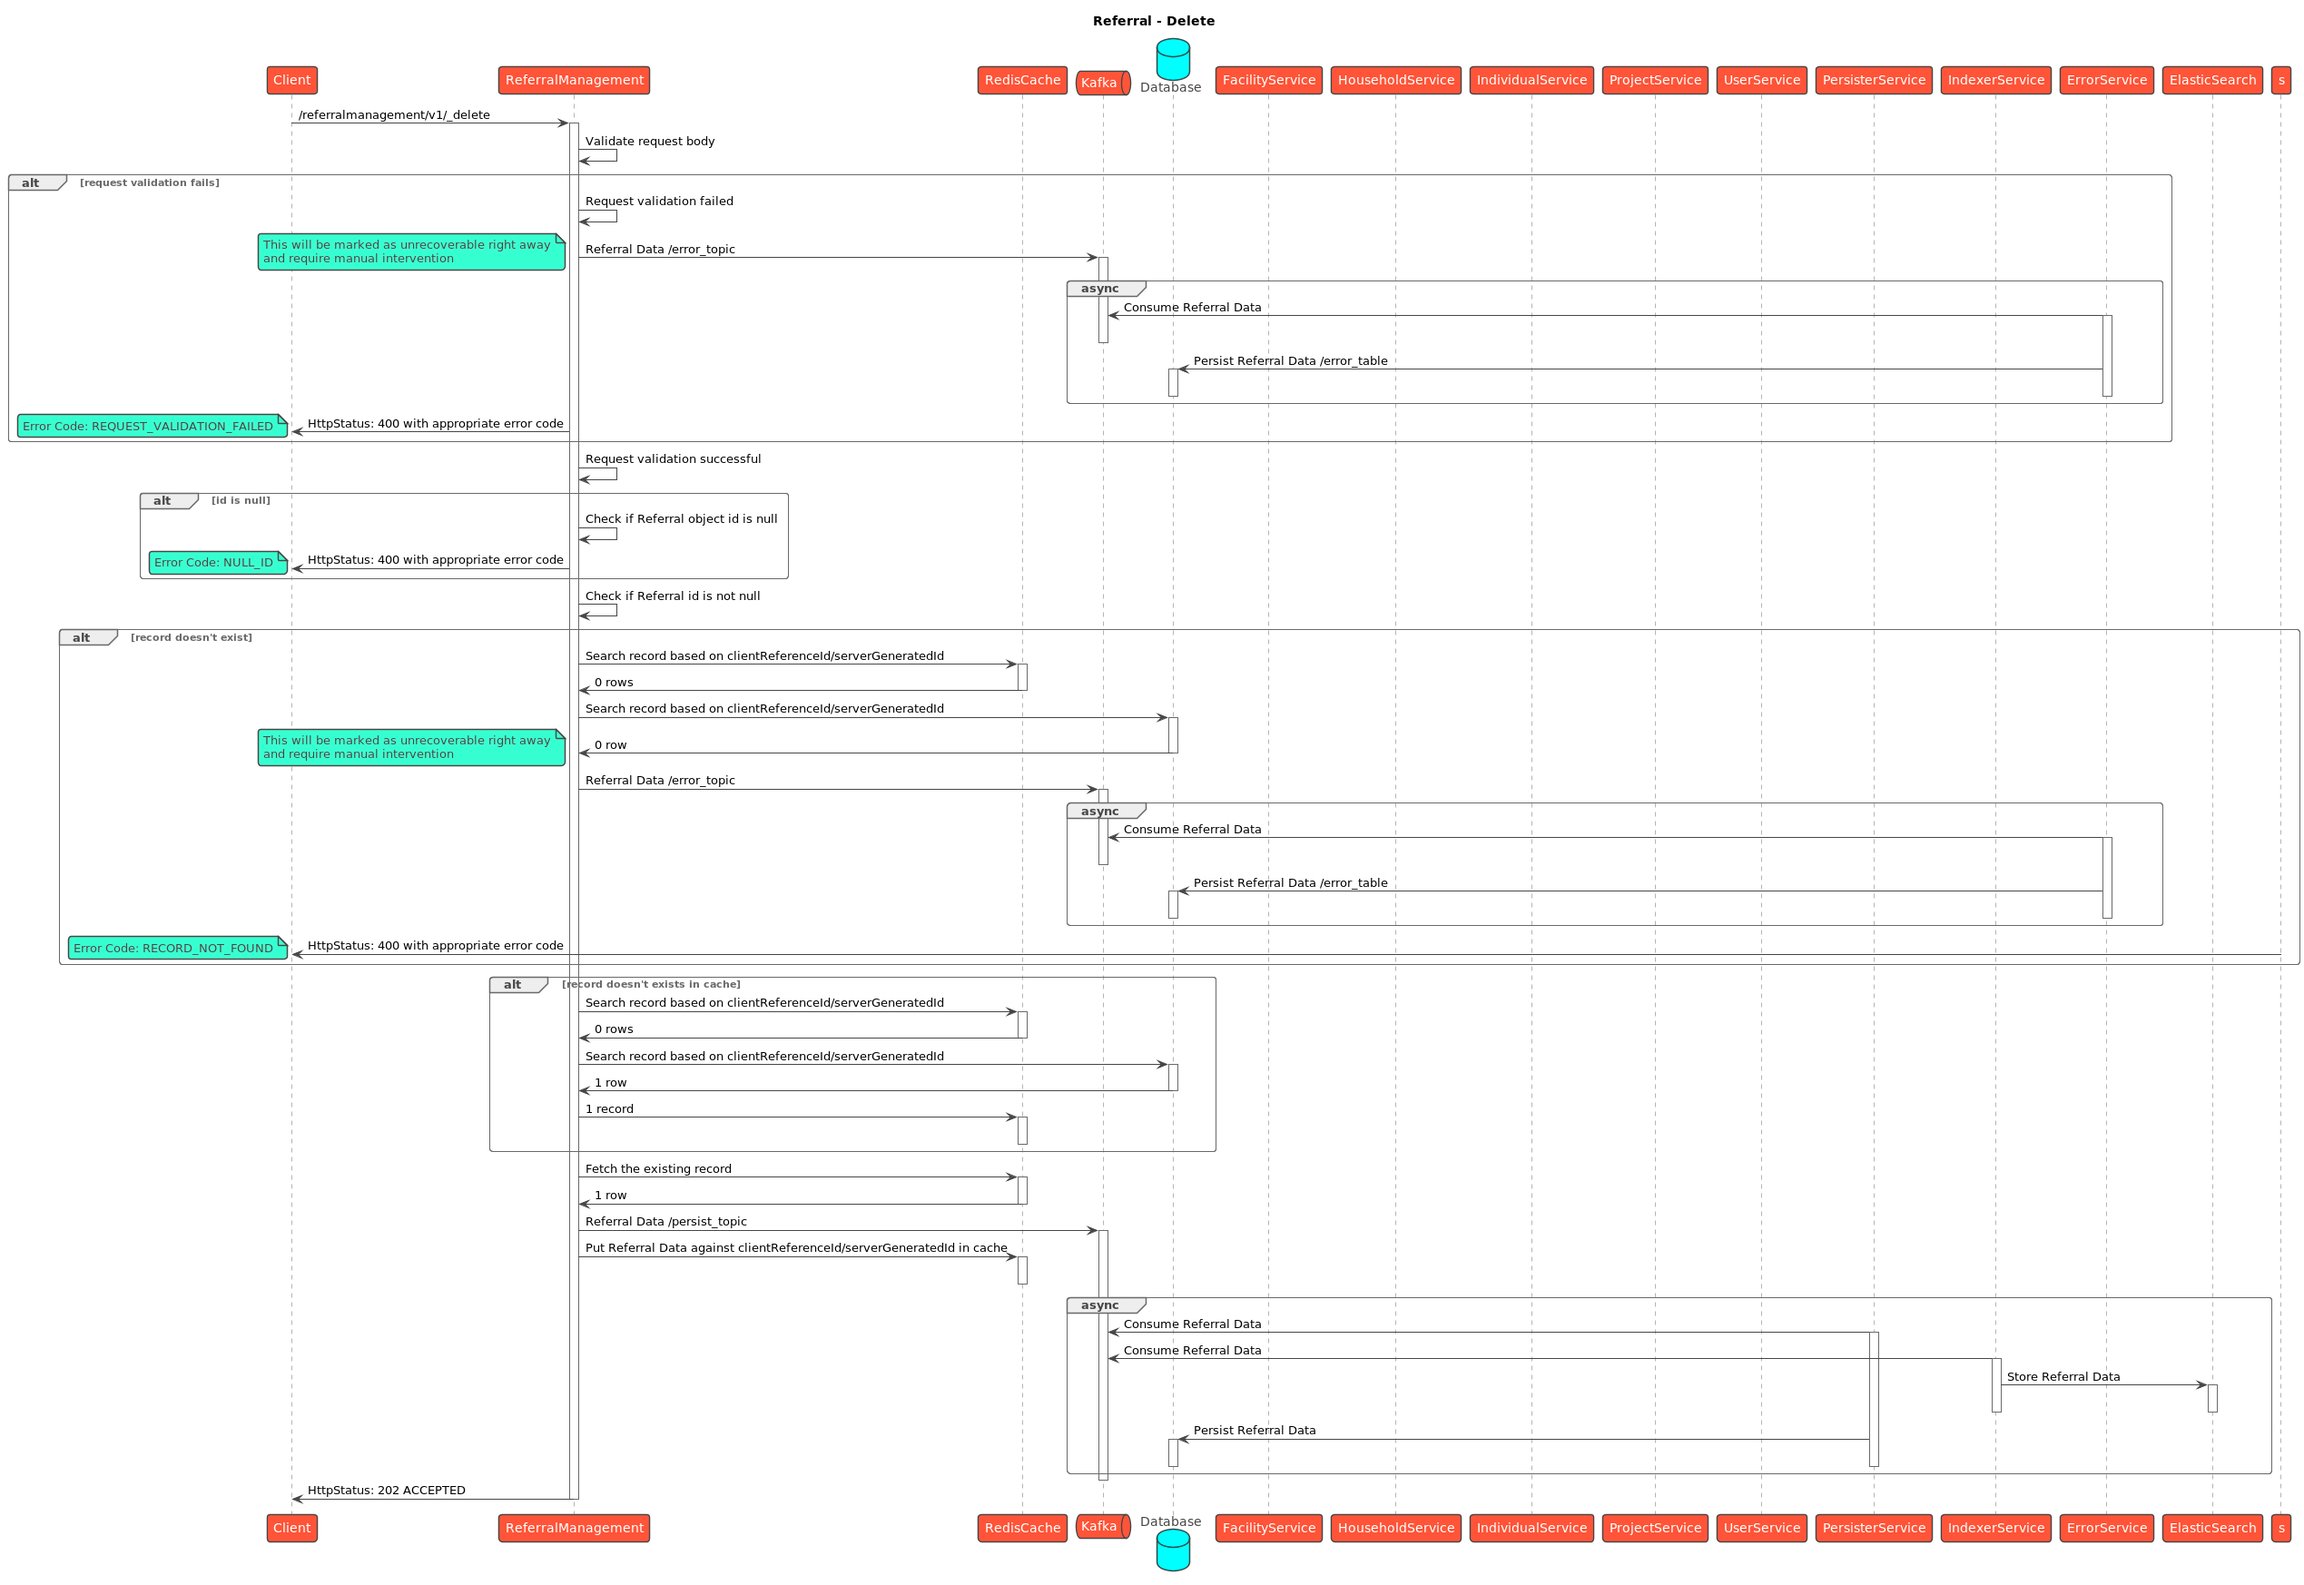
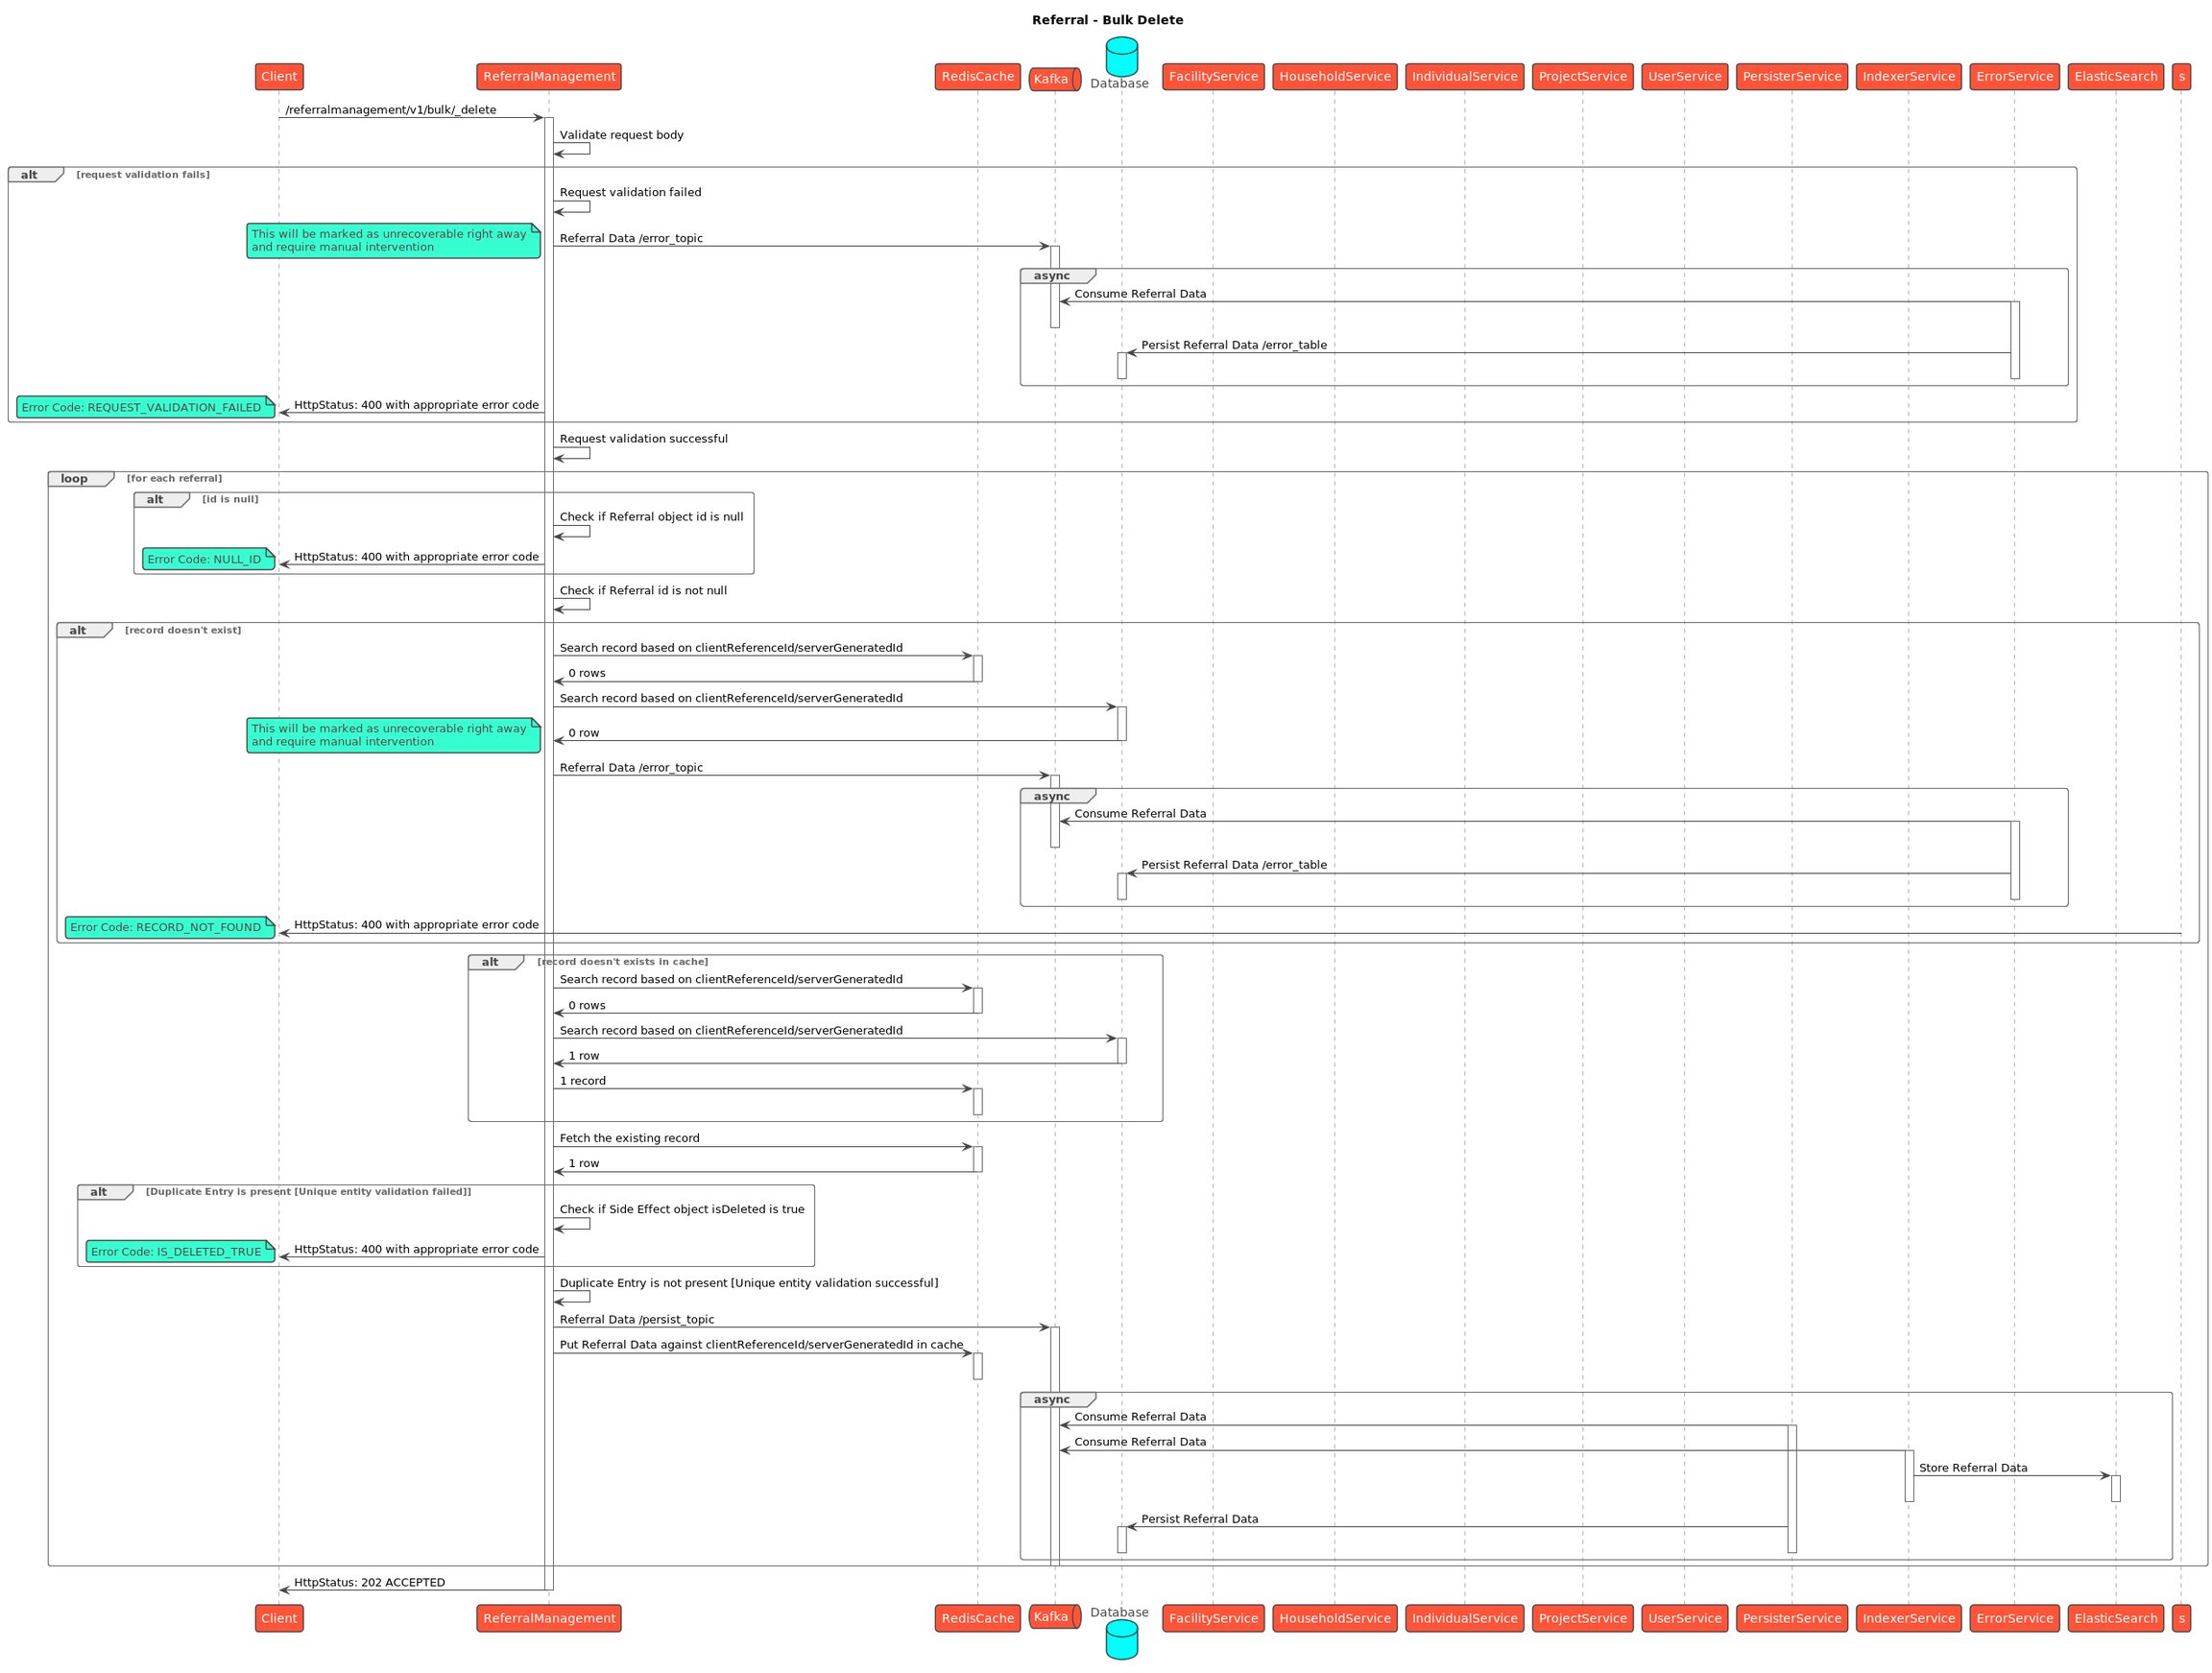
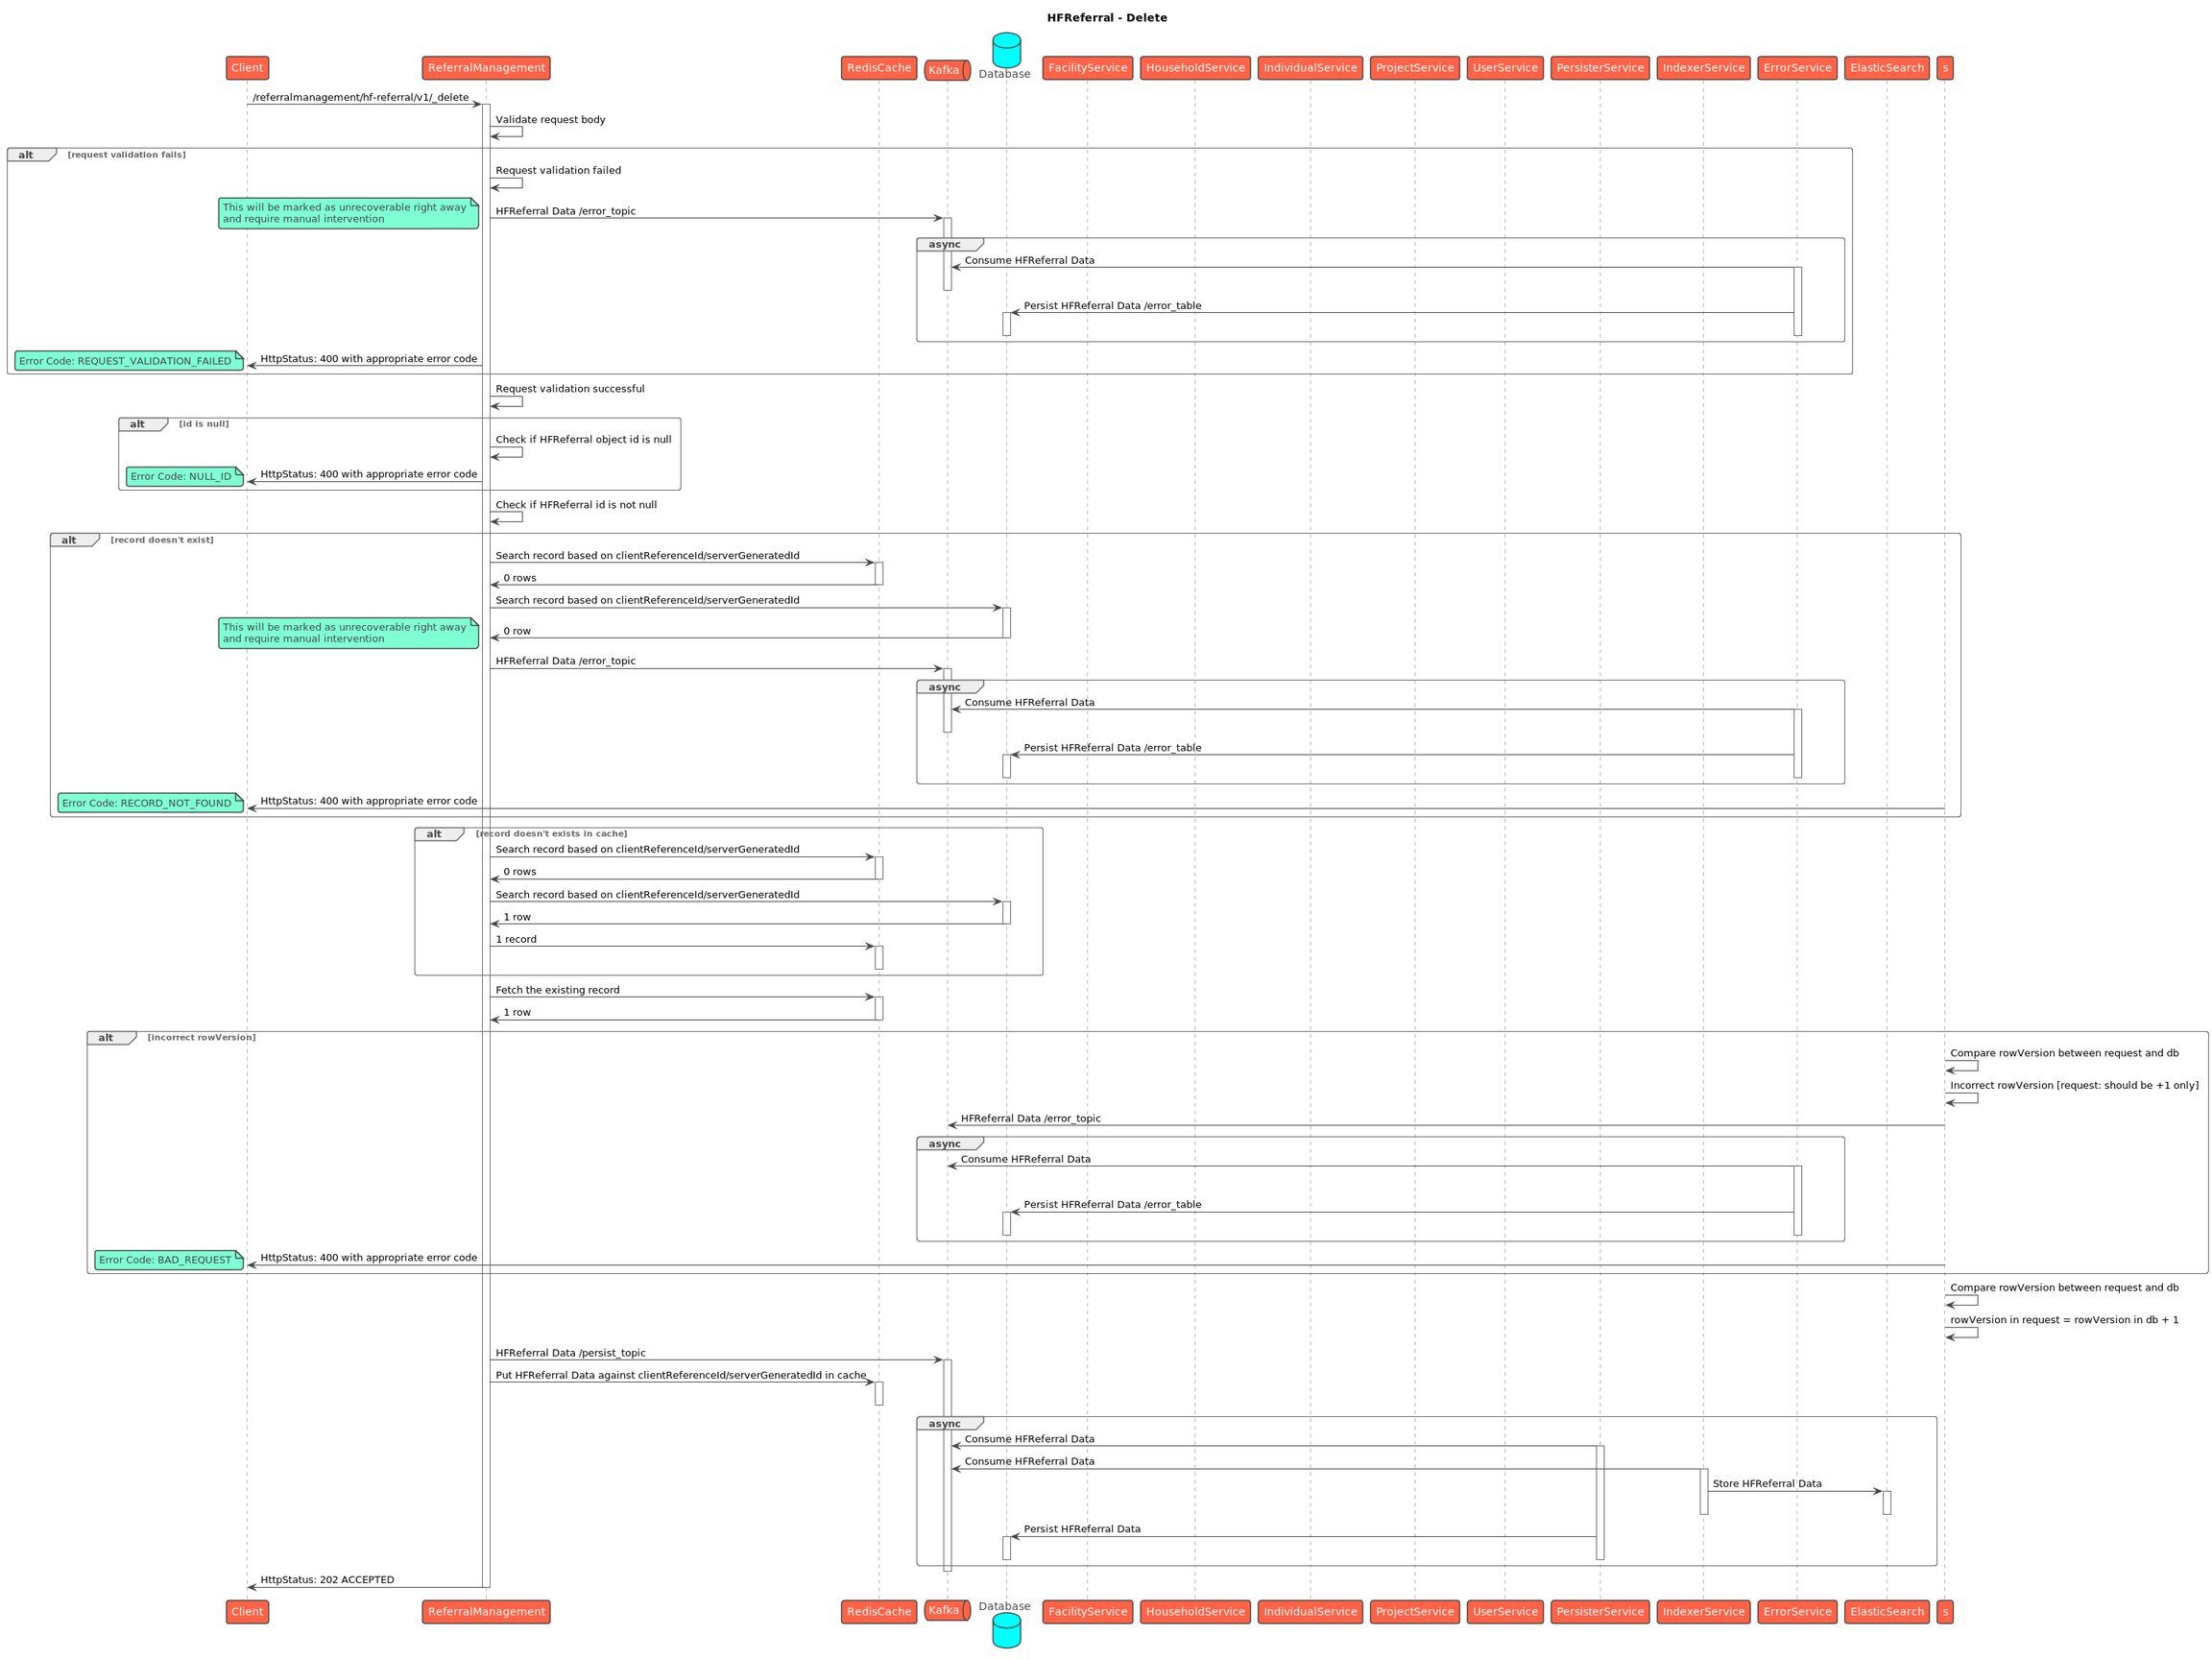
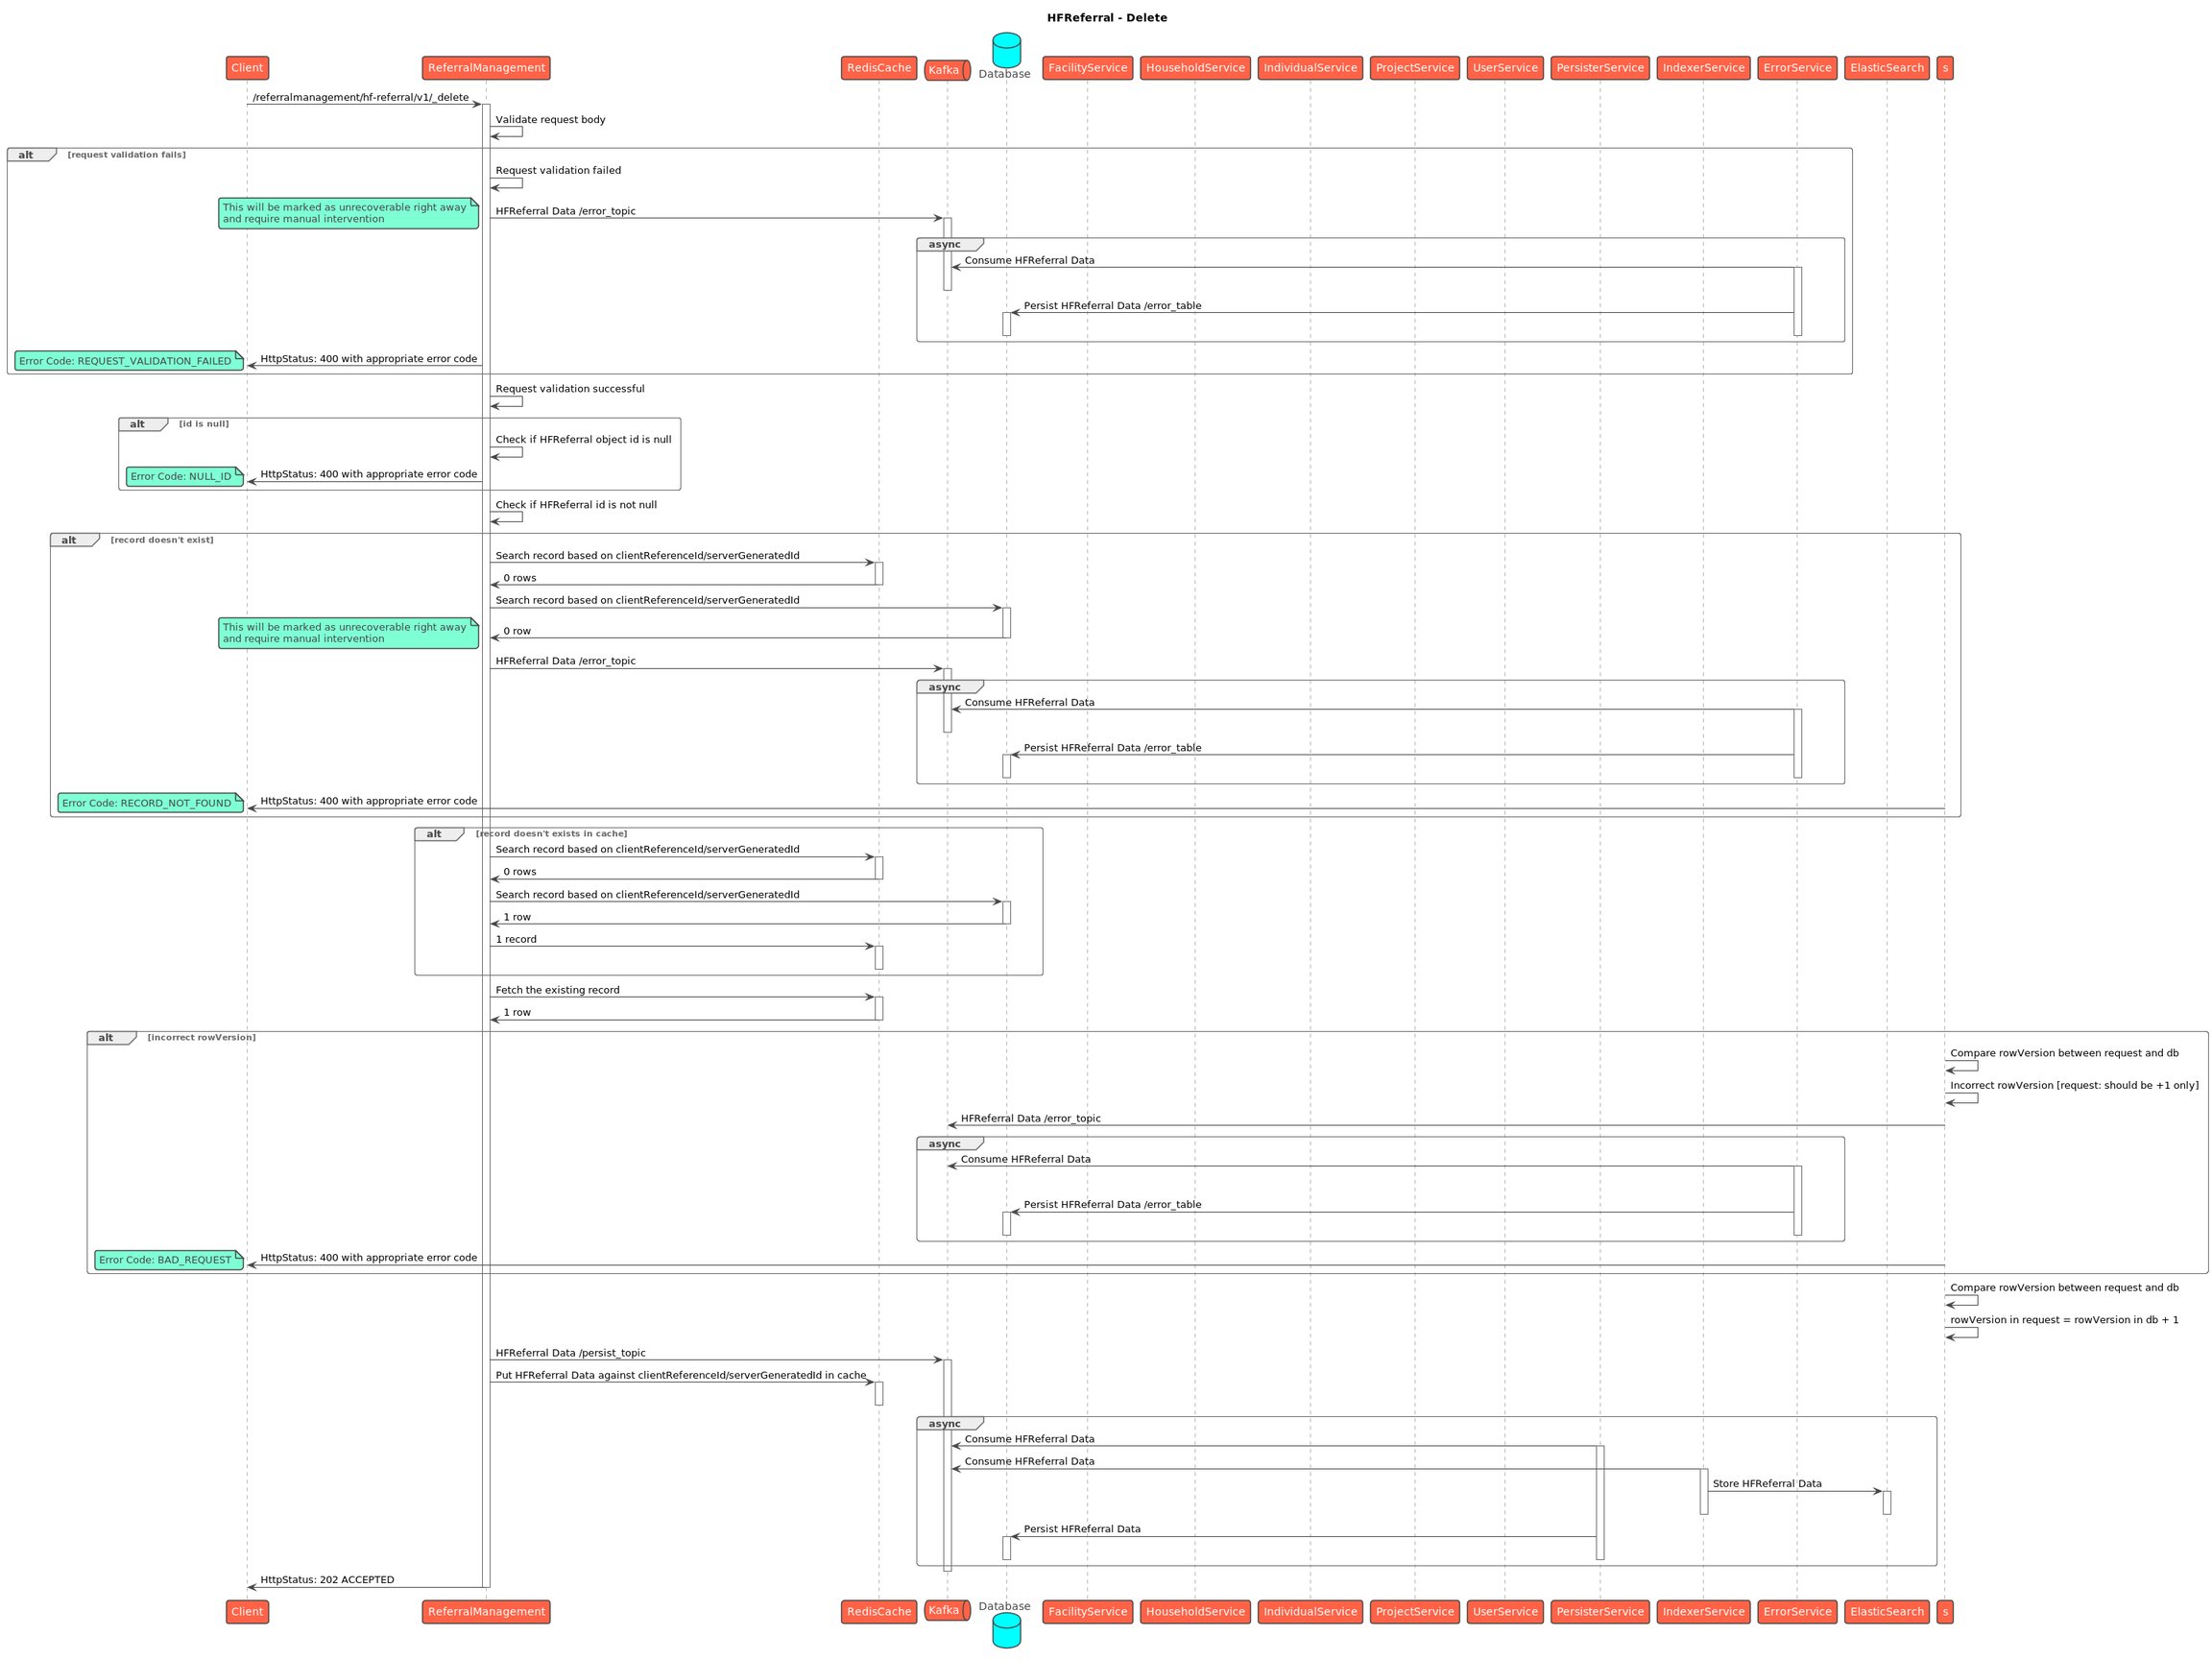
Failure / Retry Handling
Async, no batch rollback. A bulk request returns
202before persistence. If one record fails consumer validation, the others remain unchanged. Use each record'sclientReferenceIdto correlate it with consumer logs. Correct the failed record, then resubmit it.Idempotency is via
clientReferenceId— re-submitting the same one should not create a duplicate row (the unique-entity validators guard this).Optimistic locking via
rowVersionprotects against concurrent edits on update/delete.Soft delete (
isDeleted) everywhere — nothing is hard-deleted.Downsync is best-effort and bounded. If
lastSyncedTimeis missing or older than the staleness threshold (default 8h), the request is served from pre-generated files; if none exist yet it returnsPREGEN_NOT_AVAILABLEand a generation job must be triggered first.Downsync generation is single-flight per tenant/project. A second
/downsync/v1/_generatewhile one is running returns409 Conflictwith progress details; interrupted jobs are resumed on startup (503 SERVICE_INITIALIZINGuntil that scan completes). Per-file failures are tracked, so a job can finishCOMPLETED,PARTIAL_FAILURE, orFAILED.If the persister config for the referral topics is missing/stale in an environment, the API will accept writes but rows will silently not appear in Postgres — a classic "it worked in QA" trap.
Known Risks / Limitations
Downsync correctness depends on fresh pre-generated files. For stale/cold syncs, the device gets whatever was last generated; if no generation job has run, the locality returns no data (
PREGEN_NOT_AVAILABLE) — operations must schedule/trigger generation.recipientType/reasons/symptomscarry free-form or list data validated only at app level — the DB won't stop unexpected values.Side effects are linked to a task; the linkage query is a known shortcut (flagged in code as needing a proper task-search enhancement) — keep an eye on it as task volumes grow.
Relaxed-edit / last-write semantics across devices. With
includeOnlyUpdatedByOthers, a device intentionally ignores its own latest edits during sync; QA should confirm multi-device edit scenarios behave as expected.Downsync fans out to many services synchronously. A slow household/individual/project search makes the on-device bundle path slow; the pre-gen path exists precisely to take that off the request hot path.
CLAUDE.md lists
health-services-commonas 1.1.5-SNAPSHOT, but this service'spom.xmlis on1.1.3-SNAPSHOT— confirm the intended version before release.
Last updated
Was this helpful?